


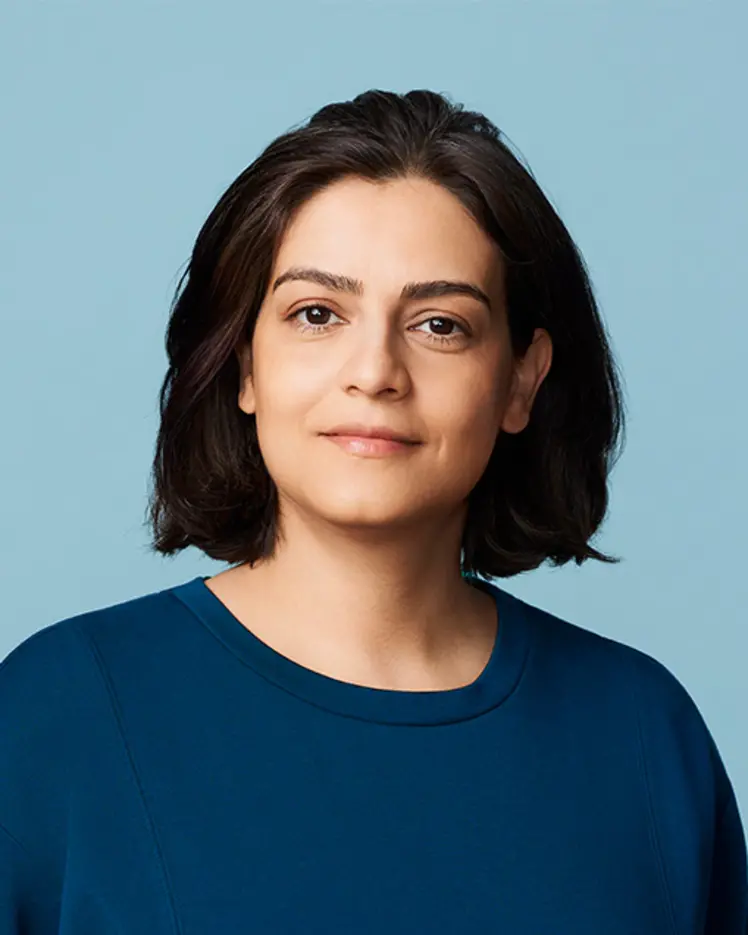
Portrait de Reihaneh Rabbany

Reihaneh Rabbany

Membre académique principal
Chaire en IA Canada-CIFAR
Professeure adjointe, McGill University, École d'informatique
Sujets de recherche
Apprentissage de représentations
Apprentissage sur graphes
Exploration des données
Réseaux de neurones en graphes
Traitement du langage naturel

Biographie

Reihaneh Rabbany est professeure adjointe à l'École d'informatique de l'Université McGill. Elle est membre du corps professoral de Mila – Institut québécois d’intelligence artificielle et titulaire d'une chaire en IA Canada-CIFAR. Elle est également membre du corps enseignant du Centre pour l’étude de la citoyenneté démocratique de McGill. Avant de se joindre à l’Université McGill, elle a été boursière postdoctorale à la School of Computer Science de l'Université Carnegie Mellon. Elle a obtenu un doctorat à l’Université de l’Alberta, au Département d'informatique. Elle dirige le laboratoire de données complexes, dont les recherches se situent à l'intersection de la science des réseaux, de l'exploration des données et de l'apprentissage automatique, et se concentrent sur l'analyse des données interconnectées du monde réel et sur les applications sociales.
Étudiants actuels

Doctorat - UdeM
Superviseur⋅e principal⋅e :
Visiteur de recherche indépendant - Mila
Stagiaire de recherche - UdeM
Superviseur⋅e principal⋅e :
Visiteur de recherche indépendant - University of Sherbrooke
Collaborateur·rice de recherche - McGill
Doctorat - UdeM
Superviseur⋅e principal⋅e :
Stagiaire de recherche - McGill
Stagiaire de recherche - McGill University
Collaborateur·rice de recherche - McGill
Co-superviseur⋅e :
Doctorat - McGill
Superviseur⋅e principal⋅e :
Stagiaire de recherche - McGill University
Postdoctorat - McGill
Superviseur⋅e principal⋅e :
Postdoctorat - UdeM
Superviseur⋅e principal⋅e :
Doctorat - UdeM
Superviseur⋅e principal⋅e :
Maîtrise recherche - McGill University
Visiteur de recherche indépendant - McGill
Maîtrise recherche - McGill University
Maîtrise recherche - McGill
Collaborateur·rice de recherche - UdeM
Superviseur⋅e principal⋅e :
Maîtrise recherche - McGill
Baccalauréat - McGill University
Co-superviseur⋅e :
Maîtrise recherche - McGill
Maîtrise recherche - UdeM
Superviseur⋅e principal⋅e :

Publications

ControBench: An Interaction-Aware Benchmark for Controversial Discourse Analysis on Social Networks
Ta Thanh Thuy
Jiaqi Zhu
Xuan Liu
Lin Shang
Lihui Chen
Zheng Yilun
Understanding how people argue across ideological divides online is important for studying political polarization, misinformation, and conte… (voir plus)nt moderation. Existing datasets capture only part of this problem: some preserve text but ignore interaction structure, some model structure without rich semantics, and others represent conversations without stable user-level ideological identity. We introduce ControBench, a benchmark for controversial discourse analysis that combines heterogeneous social interaction graphs with rich textual semantics. Built from Reddit discussions on three topics, Trump, abortion, and religion, ControBench contains 7,370 users, 1,783 posts, and 26,525 interactions. The graph contains user and post nodes connected by semantically enriched edges; in particular, user-comment-user edges encode both a reply and the parent comment that it responds to, preserving local argumentative context. User labels are derived from self-declared Reddit flairs, providing a scalable proxy for ideological identity without manual annotation. The resulting datasets exhibit low or negative adjusted homophily (Trump: -0.77, Abortion: 0.06, Religion: 0.04), reflecting the cross-cutting structure of real-world debate. We evaluate graph neural networks, pretrained language models, and large language models on ControBench and observe distinct performance patterns across topics and model families, especially when ideological boundaries are ambiguous. These results position ControBench as a challenging and realistic benchmark for controversial discourse analysis.
AI Epistemic Risks: Emerging Mechanisms & Evidence
Mick Yang
Stephen Casper
Jonathan Stray
Jasmine Li
Cameron Jones
Anna Gausen
Natasha Jacques
Brian Christian
Bálint Gyevnár
Hannah Rose Kirk
Zhonghao He
Dan Zhao (285025)
Siao Si Looi
J. Levy
Kobi Hackenburg
Elizabeth Seger
Matt Kowal
Michelle Malonza
Luke Hewitt
Hause Lin … (voir 10 de plus)
Maarten Sap
Dylan Hadfield-Menell
Thomas Costello
David Rand
Atoosa Kasirzadeh
Gordon Pennycook
Grounding Computer Use Agents on Human Demonstrations
Xiangru Jian
Kevin Qinghong Lin
Kaixin Li
Johan Obando-Ceron
Juan A. Rodriguez
Adriana Romero-Soriano
Christopher Pal
Sai Rajeswar
Building reliable computer-use agents requires grounding: accurately connecting natural language instructions to the correct on-screen eleme… (voir plus)nts. While large datasets exist for web and mobile interactions, high-quality resources for desktop environments are limited. To address this gap, we introduce GroundCUA, a large-scale desktop grounding dataset built from expert human demonstrations. It covers 87 applications across 12 categories and includes 56K screenshots, with every on-screen element carefully annotated for a total of over 3.56M human-verified annotations. From these demonstrations, we generate diverse instructions that capture a wide range of real-world tasks, providing high-quality data for model training. Using GroundCUA, we develop the GroundNext family of models that map instructions to their target UI elements. At both 3B and 7B scales, GroundNext achieves state-of-the-art results across five benchmarks using supervised fine-tuning, while requiring less than one-tenth the training data of prior work. Reinforcement learning post-training further improves performance. These results demonstrate the critical role of high-quality, expert-driven datasets in advancing general-purpose computer-use agents.
Position: Time to Close The Validation Gap in LLM Social Simulations
LLM-based social simulations—in which many language model agents interact over multiple turns—are rapidly proliferating across policy an… (voir plus)alysis, epidemiology, and computational social science. Yet the field lacks consensus on how to validate these simulations, with evaluation methods that are sparse, inconsistent, and rarely shared across disciplinary silos. We argue this creates a serious risk: premature deployment of unvalidated simulators in high-stakes domains. Our position is that the field must pivot from expansion to consolidation, prioritizing methodological standardization—shared benchmarks, open data, and reproducible evaluation protocols grounded in social science and complex systems research. We outline a concrete research program organized around specific learning problems/benchmarks, providing a path toward answering the fundamental question: when are LLM social simulations useful modelling objects?
Large Language Model Applications in the Algebra Domain: A Systematic Review
MiNT: Multi-Network Transfer Benchmark for Temporal Graph Learning
Kiarash Shamsi
Tran Gia Bao Ngo
Poupak Azad
Baris Coskunuzer
Cuneyt Gurcan Akcora
Temporal Graph Learning (TGL) aims to discover patterns in evolving networks or temporal graphs and leverage these patterns to predict futur… (voir plus)e interactions. However, most existing research focuses on learning from a single network in isolation, leaving the challenges of within-domain and cross-domain generalization largely unaddressed. In this study, we introduce a new benchmark of 84 real-world temporal transaction networks and propose **Temporal Multi-network Transfer (MiNT)**, a pre-training framework designed to capture transferable temporal dynamics across diverse networks. We train MiNT models on up to 64 transaction networks and evaluate their generalization ability on 20 held-out, unseen networks. Our results show that MiNT consistently outperforms individually trained models, revealing a strong relation between the number of pre-training networks and transfer performance. These findings highlight scaling trends in temporal graph learning and underscore the importance of network diversity in improving generalization. This work establishes the first large-scale benchmark for studying transferability in TGL and lays the groundwork for developing Temporal Graph Foundation Models. Our code is available at https://github.com/benjaminnNgo/ScalingTGNs
Higher Order Transformers: Efficient Attention Mechanism for Tensor Structured Data
Transformers are now ubiquitous for sequence modeling tasks, but their extension to multi-dimensional data remains a challenge due to the qu… (voir plus)adratic cost of the attention mechanism. In this paper, we propose Higher-Order Transformers (HOT), a novel architecture designed to efficiently process data with more than two axes, i.e. higher-order tensors. To address the computational challenges associated with high-order tensor attention, we introduce a novel Kronecker factorized attention mechanism that reduces the attention cost to quadratic in each axis' dimension, rather than quadratic in the total size of the input tensor. To further enhance efficiency, HOT leverages kernelized attention, reducing the complexity to linear. This strategy maintains the model's expressiveness while enabling scalable attention computation. We validate the effectiveness of HOT on two high-dimensional tasks, including multivariate time series forecasting, and 3D medical image classification. Experimental results demonstrate that HOT achieves competitive performance while significantly improving computational efficiency, showcasing its potential for tackling a wide range of complex, multi-dimensional data.
Reframing AI-for-Good: Radical Questioning in AI for Human Trafficking Interventions
This paper introduces Radical Questioning (RQ), a structured, pre-design ethics framework developed to assess whether artificial intelligenc… (voir plus)e (AI) should be applied to complex social problems rather than merely how. While much of responsible AI development focuses on aligning systems with principles such as fairness, transparency, and accountability, it often begins after the decision to build has already been made, implicitly treating the deployment of AI as a given rather than a question in itself. In domains such as human trafficking, marked by contested definitions, systemic injustice, and deep stakeholder asymmetries, such assumptions can obscure foundational ethical concerns. RQ offers an upstream, deliberative process for surfacing these concerns before design begins. Drawing from critical theory, participatory ethics, and relational responsibility, RQ formalizes a five-step framework to interrogate problem framings, confront techno-solutionist tendencies, and reflect on the moral legitimacy of intervention. Developed through interdisciplinary collaboration and engagement with survivor-led organizations, RQ was piloted in the domain of human trafficking (HT) which is a particularly high-stakes and ethically entangled application area. Its use led to a fundamental design shift: away from automated detection tools and toward survivor-controlled, empowerment-based technologies. We argue that RQ's novelty lies in both its temporal position, i.e, prior to technical design, and its orientation toward domains where harm is structural and ethical clarity cannot be achieved through one-size-fits-all solutions. RQ thus addresses a critical gap between abstract principles of responsible AI and the lived ethical demands of real-world deployment.
TGM: a Modular and Efficient Library for Machine Learning on Temporal Graphs
Tran Gia Bao Ngo
Jure Leskovec
Michael M. Bronstein
Matthias Fey
Well-designed open-source software drives progress in Machine Learning (ML) research. While static graph ML enjoys mature frameworks like Py… (voir plus)Torch Geometric and DGL, ML for temporal graphs (TG), networks that evolve over time, lacks comparable infrastructure. Existing TG libraries are often tailored to specific architectures, hindering support for diverse models in this rapidly evolving field. Additionally, the divide between continuous- and discrete-time dynamic graph methods (CTDG and DTDG) limits direct comparisons and idea transfer. To address these gaps, we introduce Temporal Graph Modelling (TGM), a research-oriented library for ML on temporal graphs, the first to unify CTDG and DTDG approaches. TGM offers first-class support for dynamic node features, time-granularity conversions, and native handling of link-, node-, and graph-level tasks. Empirically, TGM achieves an average 7.8x speedup across multiple models, datasets, and tasks compared to the widely used DyGLib, and an average 175x speedup on graph discretization relative to available implementations. Beyond efficiency, we show in our experiments how TGM unlocks entirely new research possibilities by enabling dynamic graph property prediction and time-driven training paradigms, opening the door to questions previously impractical to study. TGM is available at https://github.com/tgm-team/tgm
$\texttt{BluePrint}$: A Social Media User Dataset for LLM Persona Evaluation and Training
Large language models (LLMs) offer promising capabilities for simulating social media dynamics at scale, enabling studies that would be ethi… (voir plus)cally or logistically challenging with human subjects. However, the field lacks standardized data resources for fine-tuning and evaluating LLMs as realistic social media agents. We address this gap by introducing SIMPACT, the SIMulation-oriented Persona and Action Capture Toolkit, a privacy respecting framework for constructing behaviorally-grounded social media datasets suitable for training agent models. We formulate next-action prediction as a task for training and evaluating LLM-based agents and introduce metrics at both the cluster and population levels to assess behavioral fidelity and stylistic realism. As a concrete implementation, we release BluePrint, a large-scale dataset built from public Bluesky data focused on political discourse. BluePrint clusters anonymized users into personas of aggregated behaviours, capturing authentic engagement patterns while safeguarding privacy through pseudonymization and removal of personally identifiable information. The dataset includes a sizable action set of 12 social media interaction types (likes, replies, reposts, etc.), each instance tied to the posting activity preceding it. This supports the development of agents that use context-dependence, not only in the language, but also in the interaction behaviours of social media to model social media users. By standardizing data and evaluation protocols, SIMPACT provides a foundation for advancing rigorous, ethically responsible social media simulations. BluePrint serves as both an evaluation benchmark for political discourse modeling and a template for building domain specific datasets to study challenges such as misinformation and polarization.
Are Large Language Models Good Temporal Graph Learners?
Large Language Models (LLMs) have recently driven significant advancements in Natural Language Processing and various other applications. Wh… (voir plus)ile a broad range of literature has explored the graph-reasoning capabilities of LLMs, including their use of predictors on graphs, the application of LLMs to dynamic graphs -- real world evolving networks -- remains relatively unexplored. Recent work studies synthetic temporal graphs generated by random graph models, but applying LLMs to real-world temporal graphs remains an open question. To address this gap, we introduce Temporal Graph Talker (TGTalker), a novel temporal graph learning framework designed for LLMs. TGTalker utilizes the recency bias in temporal graphs to extract relevant structural information, converted to natural language for LLMs, while leveraging temporal neighbors as additional information for prediction. TGTalker demonstrates competitive link prediction capabilities compared to existing Temporal Graph Neural Network (TGNN) models. Across five real-world networks, TGTalker performs competitively with state-of-the-art temporal graph methods while consistently outperforming popular models such as TGN and HTGN. Furthermore, TGTalker generates textual explanations for each prediction, thus opening up exciting new directions in explainability and interpretability for temporal link prediction. The code is publicly available at https://github.com/shenyangHuang/TGTalker.
OpenFake: An Open Dataset and Platform Toward Real-World Deepfake Detection
Deepfakes, synthetic media created using advanced AI techniques, pose a growing threat to information integrity, particularly in politically… (voir plus) sensitive contexts. This challenge is amplified by the increasing realism of modern generative models, which our human perception study confirms are often indistinguishable from real images. Yet, existing deepfake detection benchmarks rely on outdated generators or narrowly scoped datasets (e.g., single-face imagery), limiting their utility for real-world detection. To address these gaps, we present OpenFake, a large politically grounded dataset specifically crafted for benchmarking against modern generative models with high realism, and designed to remain extensible through an innovative crowdsourced adversarial platform that continually integrates new hard examples. OpenFake comprises nearly four million total images: three million real images paired with descriptive captions and almost one million synthetic counterparts from state-of-the-art proprietary and open-source models. Detectors trained on OpenFake achieve near-perfect in-distribution performance, strong generalization to unseen generators, and high accuracy on a curated in-the-wild social media test set, significantly outperforming models trained on existing datasets. Overall, we demonstrate that with high-quality and continually updated benchmarks, automatic deepfake detection is both feasible and effective in real-world settings.