


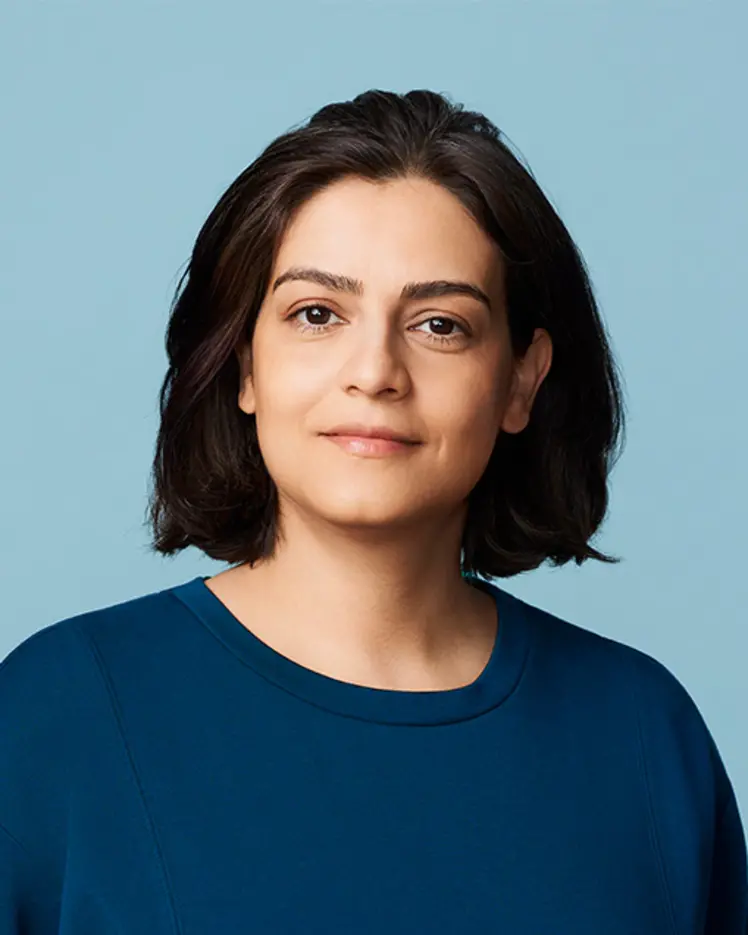
Portrait de Reihaneh Rabbany

Reihaneh Rabbany

Membre académique principal
Chaire en IA Canada-CIFAR
Professeure adjointe, McGill University, École d'informatique
Sujets de recherche
Apprentissage de représentations
Apprentissage sur graphes
Exploration des données
Réseaux de neurones en graphes
Traitement du langage naturel

Biographie

Reihaneh Rabbany est professeure adjointe à l'École d'informatique de l'Université McGill. Elle est membre du corps professoral de Mila – Institut québécois d’intelligence artificielle et titulaire d'une chaire en IA Canada-CIFAR. Elle est également membre du corps enseignant du Centre pour l’étude de la citoyenneté démocratique de McGill. Avant de se joindre à l’Université McGill, elle a été boursière postdoctorale à la School of Computer Science de l'Université Carnegie Mellon. Elle a obtenu un doctorat à l’Université de l’Alberta, au Département d'informatique. Elle dirige le laboratoire de données complexes, dont les recherches se situent à l'intersection de la science des réseaux, de l'exploration des données et de l'apprentissage automatique, et se concentrent sur l'analyse des données interconnectées du monde réel et sur les applications sociales.
Étudiants actuels

Doctorat - UdeM
Superviseur⋅e principal⋅e :
Visiteur de recherche indépendant - Mila
Stagiaire de recherche - UdeM
Superviseur⋅e principal⋅e :
Visiteur de recherche indépendant - University of Sherbrooke
Collaborateur·rice de recherche - McGill
Doctorat - UdeM
Superviseur⋅e principal⋅e :
Stagiaire de recherche - McGill
Stagiaire de recherche - McGill University
Collaborateur·rice de recherche - McGill
Co-superviseur⋅e :
Doctorat - McGill
Superviseur⋅e principal⋅e :
Stagiaire de recherche - McGill University
Postdoctorat - McGill
Superviseur⋅e principal⋅e :
Postdoctorat - UdeM
Superviseur⋅e principal⋅e :
Doctorat - UdeM
Superviseur⋅e principal⋅e :
Maîtrise recherche - McGill University
Visiteur de recherche indépendant - McGill
Maîtrise recherche - McGill University
Maîtrise recherche - McGill
Collaborateur·rice de recherche - UdeM
Superviseur⋅e principal⋅e :
Maîtrise recherche - McGill
Baccalauréat - McGill University
Co-superviseur⋅e :
Maîtrise recherche - McGill
Maîtrise recherche - UdeM
Superviseur⋅e principal⋅e :

Publications

Weak Supervision for Real World Graphs
Enhancing Privacy in the Early Detection of Sexual Predators Through Federated Learning and Differential Privacy
The increased screen time and isolation caused by the COVID-19 pandemic have led to a significant surge in cases of online grooming, which i… (voir plus)s the use of strategies by predators to lure children into sexual exploitation. Previous efforts to detect grooming in industry and academia have involved accessing and monitoring private conversations through centrally-trained models or sending private conversations to a global server. In this work, we implement a privacy-preserving pipeline for the early detection of sexual predators. We leverage federated learning and differential privacy in order to create safer online spaces for children while respecting their privacy. We investigate various privacy-preserving implementations and discuss their benefits and shortcomings. Our extensive evaluation using real-world data proves that privacy and utility can coexist with only a slight reduction in utility.
From Intuition to Understanding: Using AI Peers to Overcome Physics Misconceptions
Ruben Weijers
Denton Wu
Hannah Betts
Tamara Jacod
Yuxiang Guan
Kushal Dev
Toshali Goel
William Delooze
Ying Wu
Generative AI has the potential to transform personalization and accessibility of education. However, it raises serious concerns about accur… (voir plus)acy and helping students become independent critical thinkers. In this study, we designed a helpful yet fallible AI "Peer" to help students correct fundamental physics misconceptions related to Newtonian mechanic concepts. In contrast to approaches that seek near-perfect accuracy to create an authoritative AI tutor or teacher, we directly inform students that this AI can answer up to 40\% of questions incorrectly. In a randomized controlled trial with 165 students, those who engaged in targeted dialogue with the AI Peer achieved post-test scores that were, on average, 10.5 percentage points higher—with over 20 percentage points higher normalized gain—than a control group that discussed physics history. Qualitative feedback indicated that 91% of the treatment group's AI interactions were rated as helpful. Furthermore, by comparing student performance on pre- and post-test questions about the same concept, along with experts' annotations of the AI interactions, we find initial evidence suggesting the improvement in performance does not depend on the correctness of the AI. With further research, the AI Peer paradigm described here could open new possibilities for how we learn, adapt to, and grow with AI.
Rethinking Anti-Misinformation AI
This paper takes a position on how anti-misinformation AI works should be developed for the online misinformation context. We observe that t… (voir plus)he current literature is dominated by works that produce more information for users to process and that this function faces various challenges in bringing meaningful effects to reality. We use anti-misinformation insights from other domains to suggest a redirection of the existing line of work and identify an under-explored opportunity AI can facilitate exploring.
PairBench: Are Vision-Language Models Reliable at Comparing What They See?
Sai Rajeswar
Adriana Romero
Valentina Zantedeschi
Joao Monteiro
Understanding how effectively large vision language models (VLMs) compare visual inputs is crucial across numerous applications, yet this fu… (voir plus)ndamental capability remains insufficiently assessed. While VLMs are increasingly deployed for tasks requiring comparative judgment, including automated evaluation, re-ranking, and retrieval-augmented generation, no systematic framework exists to measure their performance in these scenarios. We present PairBench, a simple framework that evaluates VLMs as customizable similarity tools using widely available image datasets. Our approach introduces four key metrics for reliable comparison: alignment with human annotations, consistency across pair ordering, distribution smoothness, and controllability through prompting. Our analysis reveals that no model consistently excels across all metrics, with each demonstrating distinct strengths and weaknesses. Most concerning is the widespread inability of VLMs to maintain symmetric similarity scores. Interestingly, we demonstrate that performance on our benchmark strongly correlates with popular benchmarks used for more complex tasks, while providing additional metrics into controllability, smoothness and ordering. This makes PairBench a unique and comprehensive framework to evaluate the performance of VLMs for automatic evaluation depending on the task.
Hallucination Detox: Sensitivity Dropout (SenD) for Large Language Model Training
As large language models (LLMs) become increasingly prevalent, concerns about their reliability, particularly due to hallucinations - factua… (voir plus)lly inaccurate or irrelevant outputs - have grown. Our research investigates the relationship between the uncertainty in training dynamics and the emergence of hallucinations. Using models from the Pythia suite and several hallucination detection metrics, we analyze hallucination trends and identify significant variance during training. To address this, we propose Sensitivity Dropout (SenD), a novel training protocol designed to reduce hallucination variance during training by deterministically dropping embedding indices with significant variability. In addition, we develop an unsupervised hallucination detection metric, Efficient EigenScore (EES), which approximates the traditional EigenScore in 2x speed. This metric is integrated into our training protocol, allowing SenD to be both computationally scalable and effective at reducing hallucination variance. SenD improves test-time reliability of Pythia and Meta's Llama models by up to 17% and enhances factual accuracy in Wikipedia, Medical, Legal, and Coding domains without affecting downstream task performance.
Online Influence Campaigns: Strategies and Vulnerabilities
Ethan Kosak-Hine
Tom Gibbs
U. Montr'eal
Ivado
M. University
In order to combat the creation and spread of harmful content online, this paper defines and contextualizes the concept of inauthentic, soci… (voir plus)etal-scale manipulation by malicious actors. We review the literature on societally harmful content and how it proliferates to analyze the manipulation strategies used by such actors and the vulnerabilities they target. We also provide an overview of three case studies of extensive manipulation campaigns to emphasize the severity of the problem. We then address the role that Artificial Intelligence plays in the development and dissemination of harmful content, and how its evolution presents new threats to societal cohesion for countries across the globe. Our survey aims to increase our understanding of not just particular aspects of these threats, but also the strategies underlying their deployment, so we can effectively prepare for the evolving cybersecurity landscape.
Higher Order Transformers: Enhancing Stock Movement Prediction On Multimodal Time-Series Data
In this paper, we tackle the challenge of predicting stock movements in financial markets by introducing Higher Order Transformers, a novel … (voir plus)architecture designed for processing multivariate time-series data. We extend the self-attention mechanism and the transformer architecture to a higher order, effectively capturing complex market dynamics across time and variables. To manage computational complexity, we propose a low-rank approximation of the potentially large attention tensor using tensor decomposition and employ kernel attention, reducing complexity to linear with respect to the data size. Additionally, we present an encoder-decoder model that integrates technical and fundamental analysis, utilizing multimodal signals from historical prices and related tweets. Our experiments on the Stocknet dataset demonstrate the effectiveness of our method, highlighting its potential for enhancing stock movement prediction in financial markets.
TGB 2.0: A Benchmark for Learning on Temporal Knowledge Graphs and Heterogeneous Graphs
Multi-relational temporal graphs are powerful tools for modeling real-world data, capturing the evolving and interconnected nature of entiti… (voir plus)es over time. Recently, many novel models are proposed for ML on such graphs intensifying the need for robust evaluation and standardized benchmark datasets. However, the availability of such resources remains scarce and evaluation faces added complexity due to reproducibility issues in experimental protocols. To address these challenges, we introduce Temporal Graph Benchmark 2.0 (TGB 2.0), a novel benchmarking framework tailored for evaluating methods for predicting future links on Temporal Knowledge Graphs and Temporal Heterogeneous Graphs with a focus on large-scale datasets, extending the Temporal Graph Benchmark. TGB 2.0 facilitates comprehensive evaluations by presenting eight novel datasets spanning five domains with up to 53 million edges. TGB 2.0 datasets are significantly larger than existing datasets in terms of number of nodes, edges, or timestamps. In addition, TGB 2.0 provides a reproducible and realistic evaluation pipeline for multi-relational temporal graphs. Through extensive experimentation, we observe that 1) leveraging edge-type information is crucial to obtain high performance, 2) simple heuristic baselines are often competitive with more complex methods, 3) most methods fail to run on our largest datasets, highlighting the need for research on more scalable methods.
UTG: Towards a Unified View of Snapshot and Event Based Models for Temporal Graphs
Many real world graphs are inherently dynamic, constantly evolving with node and edge additions. These graphs can be represented by temporal… (voir plus) graphs, either through a stream of edge events or a sequence of graph snapshots. Until now, the development of machine learning methods for both types has occurred largely in isolation, resulting in limited experimental comparison and theoretical crosspollination between the two. In this paper, we introduce Unified Temporal Graph (UTG), a framework that unifies snapshot-based and event-based machine learning models under a single umbrella, enabling models developed for one representation to be applied effectively to datasets of the other. We also propose a novel UTG training procedure to boost the performance of snapshot-based models in the streaming setting. We comprehensively evaluate both snapshot and event-based models across both types of temporal graphs on the temporal link prediction task. Our main findings are threefold: first, when combined with UTG training, snapshot-based models can perform competitively with event-based models such as TGN and GraphMixer even on event datasets. Second, snapshot-based models are at least an order of magnitude faster than most event-based models during inference. Third, while event-based methods such as NAT and DyGFormer outperforms snapshot-based methods on both types of temporal graphs, this is because they leverage joint neighborhood structural features thus emphasizing the potential to incorporate these features into snapshotbased models as well. These findings highlight the importance of comparing model architectures independent of the data format and suggest the potential of combining the efficiency of snapshot-based models with the performance of event-based models in the future.
A Simulation System Towards Solving Societal-Scale Manipulation
Austin Welch
Gayatri K
Dan Zhao
Hao Yu
Ethan Kosak-Hine
Tom Gibbs
Busra Tugce Gurbuz
The rise of AI-driven manipulation poses significant risks to societal trust and democratic processes. Yet, studying these effects in real-w… (voir plus)orld settings at scale is ethically and logistically impractical, highlighting a need for simulation tools that can model these dynamics in controlled settings to enable experimentation with possible defenses. We present a simulation environment designed to address this. We elaborate upon the Concordia framework that simulates offline, `real life' activity by adding online interactions to the simulation through social media with the integration of a Mastodon server. We improve simulation efficiency and information flow, and add a set of measurement tools, particularly longitudinal surveys. We demonstrate the simulator with a tailored example in which we track agents' political positions and show how partisan manipulation of agents can affect election results.
Epistemic Integrity in Large Language Models
Large language models are increasingly relied upon as sources of information, but their propensity for generating false or misleading statem… (voir plus)ents with high confidence poses risks for users and society. In this paper, we confront the critical problem of epistemic miscalibration—where a model's linguistic assertiveness fails to reflect its true internal certainty. We introduce a new human-labeled dataset and a novel method for measuring the linguistic assertiveness of Large Language Models which cuts error rates by over 50% relative to previous benchmarks. Validated across multiple datasets, our method reveals a stark misalignment between how confidently models linguistically present information and their actual accuracy. Further human evaluations confirm the severity of this miscalibration. This evidence underscores the urgent risk of the overstated certainty Large Language Models hold which may mislead users on a massive scale. Our framework provides a crucial step forward in diagnosing and correcting this miscalibration, offering a path to safer and more trustworthy AI across domains.