Portrait de Pierre-Luc Bacon

Pierre-Luc Bacon

Membre académique principal
Chaire en IA Canada-CIFAR
Professeur agrégé, Université de Montréal, Département d'informatique et de recherche opérationnelle
Sujets de recherche
Apprentissage par renforcement

Biographie

Pierre-Luc Bacon est professeur agrégé au Département d'informatique et de recherche opérationnelle de l'Université de Montréal. Il est également membre de Mila – Institut québécois d’intelligence artificielle et d’IVADO et titulaire d'une chaire Facebook-CIFAR. Il dirige un groupe de recherche qui travaille sur le défi posé par la malédiction de l'horizon dans l'apprentissage par renforcement et le contrôle optimal.
Étudiants actuels

Stagiaire de recherche - McGill
Maîtrise recherche - École de technologie suprérieure
Maîtrise professionnelle - UdeM
Maîtrise recherche - Polytechnique
Superviseur⋅e principal⋅e :
Maîtrise recherche - UdeM
Postdoctorat - McGill
Superviseur⋅e principal⋅e :
Maîtrise recherche - UdeM
Collaborateur·rice de recherche - UdeM
Collaborateur·rice alumni - Polytechnique
Postdoctorat - UdeM
Superviseur⋅e principal⋅e :
Maîtrise recherche - UdeM

Publications

Layerwise LQR for Geometry-Aware Optimization of Deep Networks
Geometry-aware optimizers such as Newton and natural gradient can improve conditioning in deep learning, but scalable variants such as K-FAC… (voir plus), Shampoo, and related preconditioners usually impose structural approximations early, often discarding cross-layer interactions induced by the network computation. We introduce Layerwise LQR (LLQR), a framework for learning structured inverse preconditioners under a global layerwise optimal-control objective. The starting point is an exact equivalence: the steepest-descent step under a broad class of divergence-induced quadratic models--including Newton, Gauss-Newton, Fisher/natural-gradient, and intermediate-layer metrics--can be written as a finite-horizon Linear Quadratic Regulator (LQR) problem. This formulation serves as a reference that exposes the layerwise dynamics and cost matrices encoding the original dense geometry. We then derive a scalable relaxation that learns diagonal, (E-)Kronecker-factored, or other structured inverse preconditioners by minimizing the LQR objective and reusing them across iterations. The resulting optimizer wraps standard methods while retaining a principled connection to second-order geometry, without forming or inverting the global curvature matrix. Experiments on ResNets and Transformers show that LLQR improves optimization dynamics and often translates these gains into improved final test performance, while adding only modest wall-clock overhead. It establishes LLQR as a practical framework for geometry-aware second-order methods and a reference for evaluating scalable approximations.
Representation Learning Enables Scalable Multitask Deep Reinforcement Learning
Scaling reinforcement learning (RL) to diverse multitask settings remains a central challenge. While recent advances in model-based RL achie… (voir plus)ve strong performance, they rely on planning and complex training pipelines, making it unclear which components are essential for scalability. We revisit this question and argue that the primary driver of scalable multitask RL is not model-based control, but \emph{representation learning}. In particular, we show that combining predictive, model-based representations with high-capacity value function approximation is sufficient to achieve strong performance, even without planning. We evaluate a simple model-free algorithm, MR.Q, coupled with auxiliary predictive objectives into a scalable actor-critic architecture. This approach outperforms a recent world-model-based method and a range of deep RL baselines across a diverse suite of multitask continuous control tasks, while significantly reducing computational overhead and improving wall-clock efficiency. We observe consistent improvements with increased model capacity and show through ablations that predictive representation learning is critical for performance.
Reward Redistribution for CVaR MDPs using a Bellman Operator on L-infinity
Tail-end risk measures such as static conditional value-at-risk (CVaR) are used in safety-critical applications to prevent rare, yet catastr… (voir plus)ophic events. Unlike risk-neutral objectives, the static CVaR of the return depends on entire trajectories without admitting a recursive Bellman decomposition in the underlying Markov decision process. A classical resolution relies on state augmentation with a continuous variable. However, unless restricted to a specialized class of admissible value functions, this formulation induces sparse rewards and degenerate fixed points. In this work, we propose a novel formulation of the static CVaR objective based on augmentation. Our alternative approach leads to a Bellman operator with: (1) dense per-step rewards; (2) contracting properties on the full space of bounded value functions. Building on this theoretical foundation, we develop risk-averse value iteration and model-free Q-learning algorithms that rely on discretized augmented states. We further provide convergence guarantees and approximation error bounds due to discretization. Empirical results demonstrate that our algorithms successfully learn CVaR-sensitive policies and achieve effective performance-safety trade-offs.
Rotation-Preserving Supervised Fine-Tuning
Supervised fine-tuning (SFT) improves in-domain performance but can degrade out-of-domain (OOD) generalization. Prior work suggests that thi… (voir plus)s degradation is related to changes in dominant singular subspaces of pretrained weight matrices. However, directly identifying loss-sensitive directions with Hessian or Fisher information is computationally expensive at LLM scale. In this work, we propose preserving projected rotations in pretrained singular subspaces as an efficient proxy for Fisher-sensitive directions, which we call Rotation-Preserving Supervised Fine-Tuning (RPSFT). RPSFT penalizes changes in the projected top-
Do Tabular Foundation Models Know Physics? Contamination, Units, and the Deterministic Limit
Laurence Perreault Levasseur
Tabular foundation models (TFMs) learn to fill in tables the way language models fill in text, and tables are arguably the format in which m… (voir plus)ost physical measurement arrives. Did they learn any physics in the process? They are Bayesian by construction, so the question is what their prior contains. We probe it directly, evaluating four of them (TabPFN-3, TabICLv2, TabDPT and Real-TabPFN-2.5) against six baselines on datasets sampled from 316 physical equations, in and out of domain. TFMs dominate, out of the box and after tuning. But we show that their prior can represent neither a noiseless mechanism nor physical units, which is why they interpolate physics without yet being able to act as physical models.
Secure Agentic Coding through Counterexample-Grounded Feedback
Tue Le
Anh Nguyen Hoang
Doseok Jang
Nghi D. Q. Bui
As coding models and agent harnesses become more capable, reliable security verification is becoming a central bottleneck. Improving secure … (voir plus)code generation requires a signal whose reported progress remains aligned with actual program behavior under optimization; otherwise, an optimizer can improve the signal's verdict without removing the underlying vulnerability. Existing model-based approaches require models to either infer program behavior from source code or specify correct outcomes for adversarial tests, placing substantial reasoning demands on the security signal. We introduce \falcon{}, a counterexample-grounded verification framework that separates attack exploration from behavioral verification and connects them through execution traces of the program under test. In test-time repair, \falcon{} yields substantially stronger held-out functional-security gains than alternative security signals across secure code generation benchmarks, while preserving or improving functionality. As an RL reward, \falcon{} also outperforms static-analysis and learned rewards on held-out functional-security, even when all policies successfully optimize their respective training rewards. Combining \falcon{} with either proxy reward further improves held-out performance, suggesting that execution-grounded feedback can mitigate reward overoptimization while preserving useful guidance from existing security signals.
Generative Meta-Models are Adversarial Classifiers
We study adversarial prompt detection in LLMs through the geometry of intermediate activations. Our hypothesis is that token-level adversari… (voir plus)al attacks induce hidden states that lie outside the activation manifold associated with typical prompts. To test this, we use Generative Latent Priors (GLP), diffusion-based meta-models trained on LLM residual stream activations, as proxies for this manifold (Luo et al., 2026). We evaluate several training-free anomaly scores derived from GLP, namely Guard-GLP, including reconstruction error, diffusion time estimation, and a density-based estimate using Hutchinson trace estimation. Empirically, GLP reconstruction error separates benign prompts from adversarial prompts and provides a competitive classifier without supervised fine-tuning. We also study GLP as a regularizer for activation steering, showing that denoising edited activations can reduce attack success while limiting over-refusal and nonsensical generations. Overall, our results suggest that generative priors over LLM activations provide a useful interface for both adversarial prompt detection and safer activation-level interventions.
Building2Building: A Large Scale Benchmark for Generalizable Real-World Reinforcement Learning
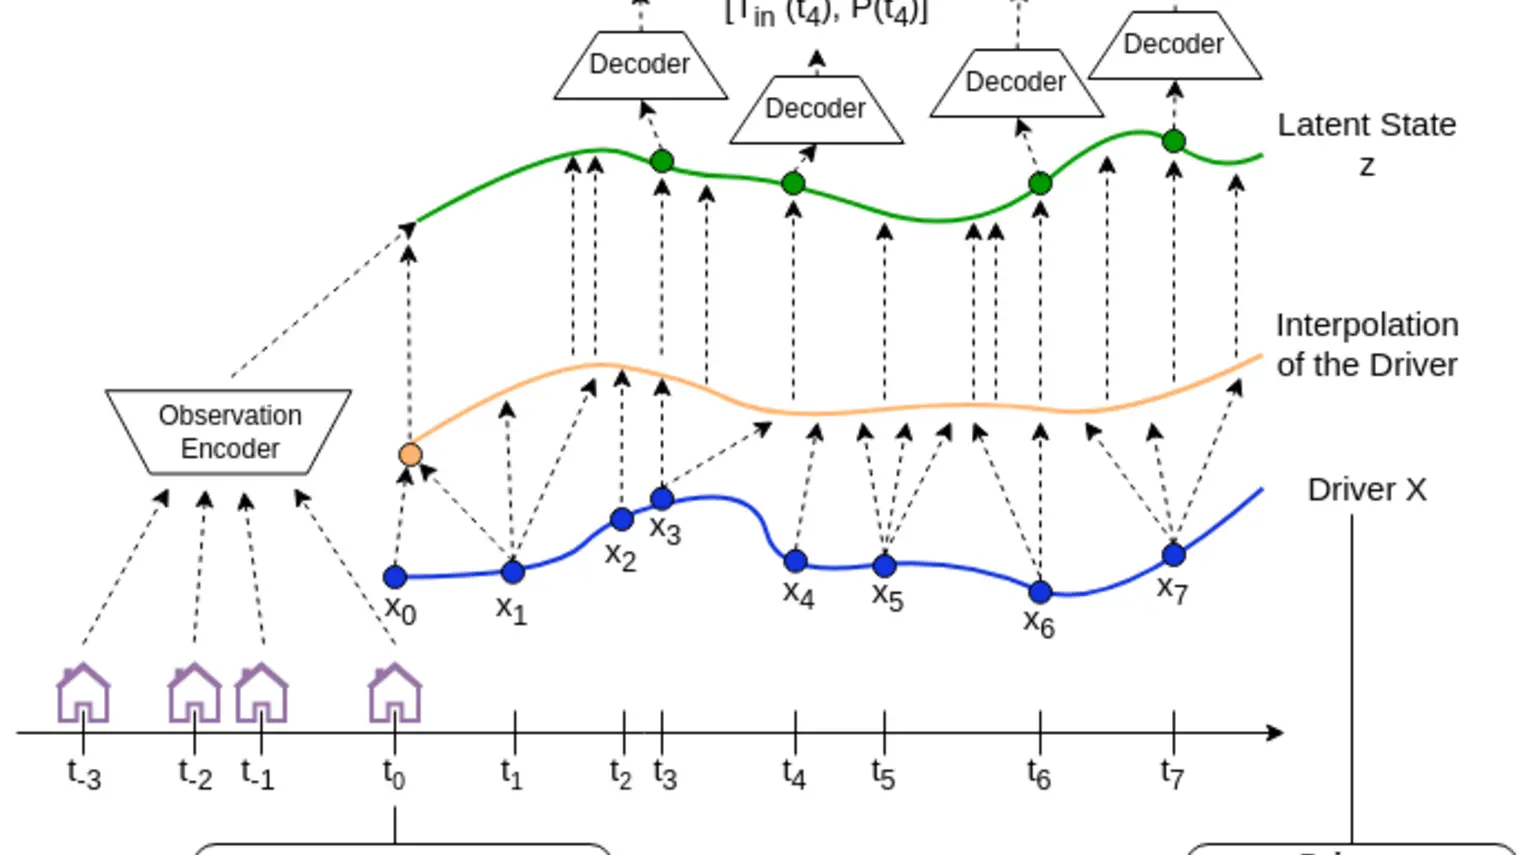
Reinforcement learning (RL) has achieved strong results in control, yet learned policies remain brittle to changes in dynamics, action space… (voir plus)s, observation spaces, or goals, a critical limitation for real-world deployment. Existing benchmarks offer limited diversity and complexity, making it difficult to rigorously study transfer, multi-task learning, and meta-learning in RL. We introduce Building2Building (B2B), a large-scale suite of realistic Heating, Ventilation, and Air Conditioning (HVAC) control environments built on EnergyPlus, a state-of-the-art building simulator. B2B is fully compatible with the Gymnasium interface and features a parametric building generator, enabling the systematic generation of diverse building configurations with heterogeneous observation and action spaces. Based on this suite, we define benchmark tasks targeting key open challenges in RL, including goal adaptation, dynamics adaptation, action-space shifts, and cross-domain transfer. By providing a large-scale, diverse, and physically grounded testbed with standardized evaluation protocols, B2B enables systematic investigation of generalization and transfer in continuous control. Beyond advancing research on generalization in RL, this new benchmark also carries significant societal implications by enabling improved HVAC control at scale, one of the most energy-intensive systems in buildings.
Beyond One-Size-Fits-All: Diagnosis-Driven Online Reinforcement Learning with Offline Priors
Guozheng Ma
Zilin Wang
Dacheng Tao
Online reinforcement learning (RL) agents increasingly depend on knowledge acquired offline to achieve practical efficiency. Originally stud… (voir plus)ied in offline-to-online RL, this paradigm now spans foundation model post-training and embodied intelligence, with prior types expanding from offline datasets and pre-trained policies to increasingly diverse knowledge sources such as multimodal foundation models and generative world models. Offline priors have become central to how deep RL is developed and deployed. However, this reliance introduces a challenge that the prevailing benchmark-driven paradigm cannot resolve: because prior validity varies across deployments and shifts during training, no single approach to managing it is universally optimal, and benchmark rankings offer limited guidance for real-world deployments. Rather than pursuing universal solutions, we argue that the field should shift to diagnosis-driven tension management, in which deployment-specific evidence guides how the learner relates to its priors throughout training, enabling both flexible and adaptive deployment. We support this position with a framework characterizing how priors reshape online optimization through three functional roles, controlled experiments demonstrating help-or-hurt reversals, cross-domain evidence from foundation model post-training to embodied intelligence, and engagement with five substantive counterarguments.
From Static Policies to Adaptive Priors in Offline Reinforcement Learning
Offline reinforcement learning (RL) has traditionally focused on learning policies for direct deployment under conservative objectives, wher… (voir plus)e uncertainty outside the offline dataset is treated pessimistically to ensure robustness. We argue that this formulation becomes incomplete when an offline-trained policy is subsequently updated through online interaction, as increasingly occurs in modern intelligent systems through test-time adaptation and online fine-tuning. This position paper argues that, in such settings, the objective of offline RL should extend beyond immediate deployment and instead prioritize learning *adaptive policy priors*: policies that preserve the capacity to improve during subsequent interaction through memory, exploration, and self-correction. We formalize this perspective as *adaptive offline reinforcement learning* (AORL), distinguish it from offline-to-online RL, and explain why adaptability becomes important under distributional shift, limited dataset coverage, and changing test-time conditions. We further discuss Bayesian offline RL as one principled direction for constructing adaptive policy priors by preserving epistemic uncertainty over plausible environments. Finally, we outline connections, open challenges, and research directions for treating offline RL as preparation for future experience rather than as a static deployment problem.
Long-Horizon Model-Based Offline Reinforcement Learning Without Explicit Conservatism
Popular offline reinforcement learning (RL) methods rely on explicit conservatism, penalizing out-of-dataset actions or restricting… (voir plus) rollout horizons. We question the universality of this principle and revisit a complementary Bayesian perspective for test-time adaptation. By modeling a posterior over world models and training a history-dependent agent to maximize expected return, the Bayesian approach directly addresses epistemic uncertainty without explicit conservatism. We first illustrate in a bandit setting that Bayesianism excels on low-quality datasets where conservatism fails. Scaling to realistic tasks, we find that long-horizon rollouts are essential to control value overestimation once conservatism is removed. We introduce design choices that enable learning from long-horizon rollouts while mitigating compounding model errors, yielding our algorithm, NEUBAY, grounded in the neutral Bayesian principle. On D4RL and NeoRL benchmarks, NEUBAY is competitive with leading conservative algorithms, achieving new state-of-the-art on 7 datasets with rollout horizons of several hundred steps. Finally, we characterize datasets by quality and coverage to identify when NEUBAY is preferable to conservative methods.
Long-Horizon Model-Based Offline Reinforcement Learning Without Conservatism