Portrait de Pierre-Luc Bacon

Pierre-Luc Bacon

Membre académique principal
Chaire en IA Canada-CIFAR
Professeur agrégé, Université de Montréal, Département d'informatique et de recherche opérationnelle
Sujets de recherche
Apprentissage par renforcement

Biographie

Pierre-Luc Bacon est professeur agrégé au Département d'informatique et de recherche opérationnelle de l'Université de Montréal. Il est également membre de Mila – Institut québécois d’intelligence artificielle et d’IVADO et titulaire d'une chaire Facebook-CIFAR. Il dirige un groupe de recherche qui travaille sur le défi posé par la malédiction de l'horizon dans l'apprentissage par renforcement et le contrôle optimal.
Étudiants actuels

Stagiaire de recherche - McGill
Maîtrise recherche - École de technologie suprérieure
Maîtrise professionnelle - UdeM
Collaborateur·rice alumni - UdeM
Co-superviseur⋅e :
Maîtrise recherche - Polytechnique
Superviseur⋅e principal⋅e :
Maîtrise recherche - UdeM
Postdoctorat - McGill
Superviseur⋅e principal⋅e :
Maîtrise recherche - UdeM
Postdoctorat - UdeM
Superviseur⋅e principal⋅e :
Maîtrise recherche - UdeM

Publications

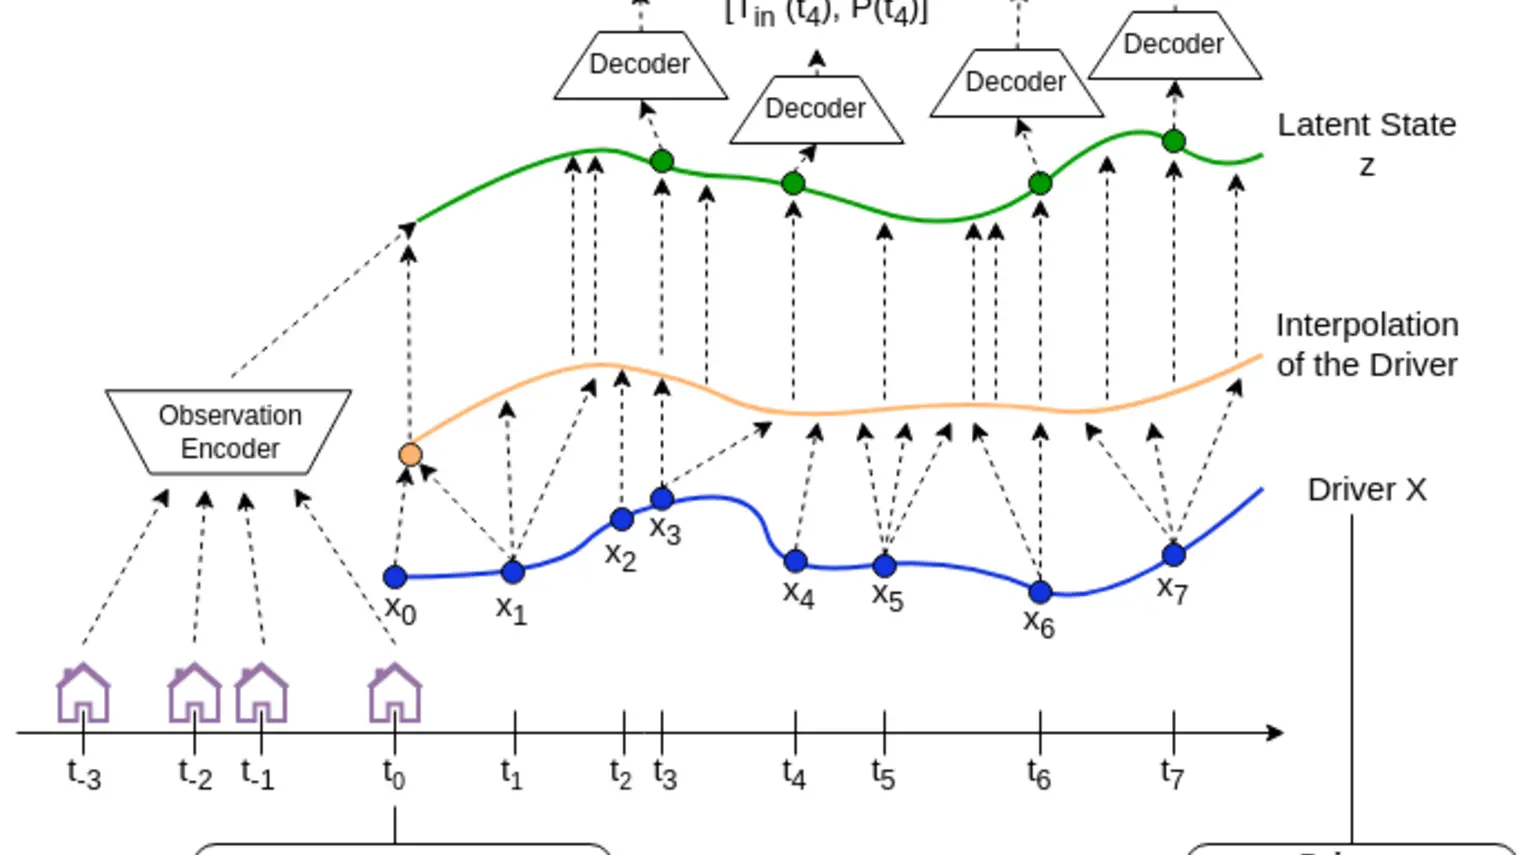
Neural differential equations for temperature control in buildings under demand response programs
Do Transformer World Models Give Better Policy Gradients?
A natural approach for reinforcement learning is to predict future rewards by unrolling a neural network world model, and to backpropagate t… (voir plus)hrough the resulting computational graph to learn a policy. However, this method often becomes impractical for long horizons since typical world models induce hard-to-optimize loss landscapes. Transformers are known to efficiently propagate gradients over long horizons: could they be the solution to this problem? Surprisingly, we show that commonly-used transformer world models produce circuitous gradient paths, which can be detrimental to long-range policy gradients. To tackle this challenge, we propose a class of world models called Actions World Models (AWMs), designed to provide more direct routes for gradient propagation. We integrate such AWMs into a policy gradient framework that underscores the relationship between network architectures and the policy gradient updates they inherently represent. We demonstrate that AWMs can generate optimization landscapes that are easier to navigate even when compared to those from the simulator itself. This property allows transformer AWMs to produce better policies than competitive baselines in realistic long-horizon tasks.
Bridging State and History Representations: Understanding Self-Predictive RL
Representations are at the core of all deep reinforcement learning (RL) methods for both Markov decision processes (MDPs) and partially obse… (voir plus)rvable Markov decision processes (POMDPs). Many representation learning methods and theoretical frameworks have been developed to understand what constitutes an effective representation. However, the relationships between these methods and the shared properties among them remain unclear. In this paper, we show that many of these seemingly distinct methods and frameworks for state and history abstractions are, in fact, based on a common idea of self-predictive abstraction. Furthermore, we provide theoretical insights into the widely adopted objectives and optimization, such as the stop-gradient technique, in learning self-predictive representations. These findings together yield a minimalist algorithm to learn self-predictive representations for states and histories. We validate our theories by applying our algorithm to standard MDPs, MDPs with distractors, and POMDPs with sparse rewards. These findings culminate in a set of preliminary guidelines for RL practitioners.
Course Correcting Koopman Representations
Koopman representations aim to learn features of nonlinear dynamical systems (NLDS) which lead to linear dynamics in the latent space. Theor… (voir plus)etically, such features can be used to simplify many problems in modeling and control of NLDS. In this work we study autoencoder formulations of this problem, and different ways they can be used to model dynamics, specifically for future state prediction over long horizons. We discover several limitations of predicting future states in the latent space and propose an inference-time mechanism, which we refer to as Periodic Reencoding, for faithfully capturing long term dynamics. We justify this method both analytically and empirically via experiments in low and high dimensional NLDS.
Motif: Intrinsic Motivation From Artificial Intelligence Feedback
Exploring rich environments and evaluating one's actions without prior knowledge is immensely challenging. In this paper, we propose Motif, … (voir plus)a general method to interface such prior knowledge from a Large Language Model (LLM) with an agent. Motif is based on the idea of grounding LLMs for decision-making without requiring them to interact with the environment: it elicits preferences from an LLM over pairs of captions to construct an intrinsic reward, which is then used to train agents with reinforcement learning. We evaluate Motif's performance and behavior on the challenging, open-ended and procedurally-generated NetHack game. Surprisingly, by only learning to maximize its intrinsic reward, Motif achieves a higher game score than an algorithm directly trained to maximize the score itself. When combining Motif's intrinsic reward with the environment reward, our method significantly outperforms existing approaches and makes progress on tasks where no advancements have ever been made without demonstrations. Finally, we show that Motif mostly generates intuitive human-aligned behaviors which can be steered easily through prompt modifications, while scaling well with the LLM size and the amount of information given in the prompt.
Maximum entropy GFlowNets with soft Q-learning
Generative Flow Networks (GFNs) have emerged as a powerful tool for sampling discrete objects from unnormalized distributions, offering a sc… (voir plus)alable alternative to Markov Chain Monte Carlo (MCMC) methods. While GFNs draw inspiration from maximum entropy reinforcement learning (RL), the connection between the two has largely been unclear and seemingly applicable only in specific cases. This paper addresses the connection by constructing an appropriate reward function, thereby establishing an exact relationship between GFNs and maximum entropy RL. This construction allows us to introduce maximum entropy GFNs, which, in contrast to GFNs with uniform backward policy, achieve the maximum entropy attainable by GFNs without constraints on the state space.
Decoupling regularization from the action space
Sobhan Mohammadpour
Regularized reinforcement learning (RL), particularly the entropy-regularized kind, has gained traction in optimal control and inverse RL. W… (voir plus)hile standard unregularized RL methods remain unaffected by changes in the number of actions, we show that it can severely impact their regularized counterparts. This paper demonstrates the importance of decoupling the regularizer from the action space: that is, to maintain a consistent level of regularization regardless of how many actions are involved to avoid over-regularization. Whereas the problem can be avoided by introducing a task-specific temperature parameter, it is often undesirable and cannot solve the problem when action spaces are state-dependent. In the state-dependent action context, different states with varying action spaces are regularized inconsistently. We introduce two solutions: a static temperature selection approach and a dynamic counterpart, universally applicable where this problem arises. Implementing these changes improves performance on the DeepMind control suite in static and dynamic temperature regimes and a biological design task.
Generative Active Learning for the Search of Small-Molecule Protein Binders
Cheng-Hao Liu
Éric Jolicoeur
Edward Ruediger
Andrei Nica
Daniel St-Cyr
Doris Alexandra Schuetz
Victor Ion Butoi
Saikrishna Gottipati
Prateek Gupta
Sasikanth Avancha
William Hamilton
Brooks Paige
Sanchit Misra
Bharat Kaul
José Miguel Hernández-Lobato
Marwin Segler
Michael Bronstein
Anne Marinier
Mike Tyers
Despite substantial progress in machine learning for scientific discovery in recent years, truly de novo design of small molecules which exh… (voir plus)ibit a property of interest remains a significant challenge. We introduce LambdaZero, a generative active learning approach to search for synthesizable molecules. Powered by deep reinforcement learning, LambdaZero learns to search over the vast space of molecules to discover candidates with a desired property. We apply LambdaZero with molecular docking to design novel small molecules that inhibit the enzyme soluble Epoxide Hydrolase 2 (sEH), while enforcing constraints on synthesizability and drug-likeliness. LambdaZero provides an exponential speedup in terms of the number of calls to the expensive molecular docking oracle, and LambdaZero de novo designed molecules reach docking scores that would otherwise require the virtual screening of a hundred billion molecules. Importantly, LambdaZero discovers novel scaffolds of synthesizable, drug-like inhibitors for sEH. In in vitro experimental validation, a series of ligands from a generated quinazoline-based scaffold were synthesized, and the lead inhibitor N-(4,6-di(pyrrolidin-1-yl)quinazolin-2-yl)-N-methylbenzamide (UM0152893) displayed sub-micromolar enzyme inhibition of sEH.
Using label propagation for learning temporally abstract actions in reinforcement learning
Pierre‐Luc Bacon
Block-State Transformers
State space models (SSMs) have shown impressive results on tasks that require modeling long-range dependencies and efficiently scale to long… (voir plus) sequences owing to their subquadratic runtime complexity. Originally designed for continuous signals, SSMs have shown superior performance on a plethora of tasks, in vision and audio; however, SSMs still lag Transformer performance in Language Modeling tasks. In this work, we propose a hybrid layer named Block-State Transformer (BST), that internally combines an SSM sublayer for long-range contextualization, and a Block Transformer sublayer for short-term representation of sequences. We study three different, and completely parallelizable, variants that integrate SSMs and block-wise attention. We show that our model outperforms similar Transformer-based architectures on language modeling perplexity and generalizes to longer sequences. In addition, the Block-State Transformer demonstrates more than tenfold increase in speed at the layer level compared to the Block-Recurrent Transformer when model parallelization is employed.
Double Gumbel Q-Learning
Policy Optimization in a Noisy Neighborhood: On Return Landscapes in Continuous Control
Deep reinforcement learning agents for continuous control are known to exhibit significant instability in their performance over time. In th… (voir plus)is work, we provide a fresh perspective on these behaviors by studying the return landscape: the mapping between a policy and a return. We find that popular algorithms traverse noisy neighborhoods of this landscape, in which a single update to the policy parameters leads to a wide range of returns. By taking a distributional view of these returns, we map the landscape, characterizing failure-prone regions of policy space and revealing a hidden dimension of policy quality. We show that the landscape exhibits surprising structure by finding simple paths in parameter space which improve the stability of a policy. To conclude, we develop a distribution-aware procedure which finds such paths, navigating away from noisy neighborhoods in order to improve the robustness of a policy. Taken together, our results provide new insight into the optimization, evaluation, and design of agents.