Portrait of Pierre-Luc Bacon

Pierre-Luc Bacon

Core Academic Member
Canada CIFAR AI Chair
Associate Professor, Université de Montréal
Research Topics
Reinforcement Learning

Biography

Pierre-Luc Bacon is an assistant professor at Université de Montréal in the Department of Computer Science and Operations Research (DIRO). He is also a core academic member of Mila – Quebec Artificial Intelligence Institute and IVADO, and holds a Facebook CIFAR AI Chair. Bacon leads a research group that investigates the challenges posed by the curse of the horizon in reinforcement learning and optimal control.
Current Students

Postdoctorate - Concordia University
Research Intern - McGill University
Master's Research - École de technologie suprérieure
Professional Master's - Université de Montréal
Master's Research - Polytechnique Montréal
Principal supervisor :
Master's Research - Université de Montréal
PhD - Université de Montréal
Postdoctorate - McGill University
Principal supervisor :
PhD - Université de Montréal
Master's Research - Université de Montréal
PhD - Université de Montréal
Master's Research - Université de Montréal
PhD - Université de Montréal
Postdoctorate - Université de Montréal
Collaborating researcher - Université de Montréal
Collaborating Alumni - Polytechnique Montréal
Postdoctorate - Université de Montréal
Principal supervisor :
Master's Research - Université de Montréal

Publications

What Matters when Modeling Human Behavior using Imitation Learning?
As AI systems become increasingly embedded in human decision-making process, aligning their behavior with human values is critical to ensuri… (see more)ng safe and trustworthy deployment. A central approach to AI Alignment called Imitation Learning (IL), trains a learner to directly mimic desirable human behaviors from expert demonstrations. However, standard IL methods assume that (1) experts act to optimize expected returns; (2) expert policies are Markovian. Both assumptions are inconsistent with empirical findings from behavioral economics, according to which humans are (1) risk-sensitive; and (2) make decisions based on past experience. In this work, we examine the implications of risk sensitivity for IL and show that standard approaches do not capture all optimal policies under risk-sensitive decision criteria. By characterizing these expert policies, we identify key limitations of existing IL algorithms in replicating expert performance in risk-sensitive settings. Our findings underscore the need for new IL frameworks that account for both risk-aware preferences and temporal dependencies to faithfully align AI behavior with human experts.
MaestroMotif: Skill Design From Artificial Intelligence Feedback
Describing skills in natural language has the potential to provide an accessible way to inject human knowledge about decision-making into an… (see more) AI system. We present MaestroMotif, a method for AI-assisted skill design, which yields high-performing and adaptable agents. MaestroMotif leverages the capabilities of Large Language Models (LLMs) to effectively create and reuse skills. It first uses an LLM's feedback to automatically design rewards corresponding to each skill, starting from their natural language description. Then, it employs an LLM's code generation abilities, together with reinforcement learning, for training the skills and combining them to implement complex behaviors specified in language. We evaluate MaestroMotif using a suite of complex tasks in the NetHack Learning Environment (NLE), demonstrating that it surpasses existing approaches in both performance and usability.
Mol-MoE: Training Preference-Guided Routers for Molecule Generation
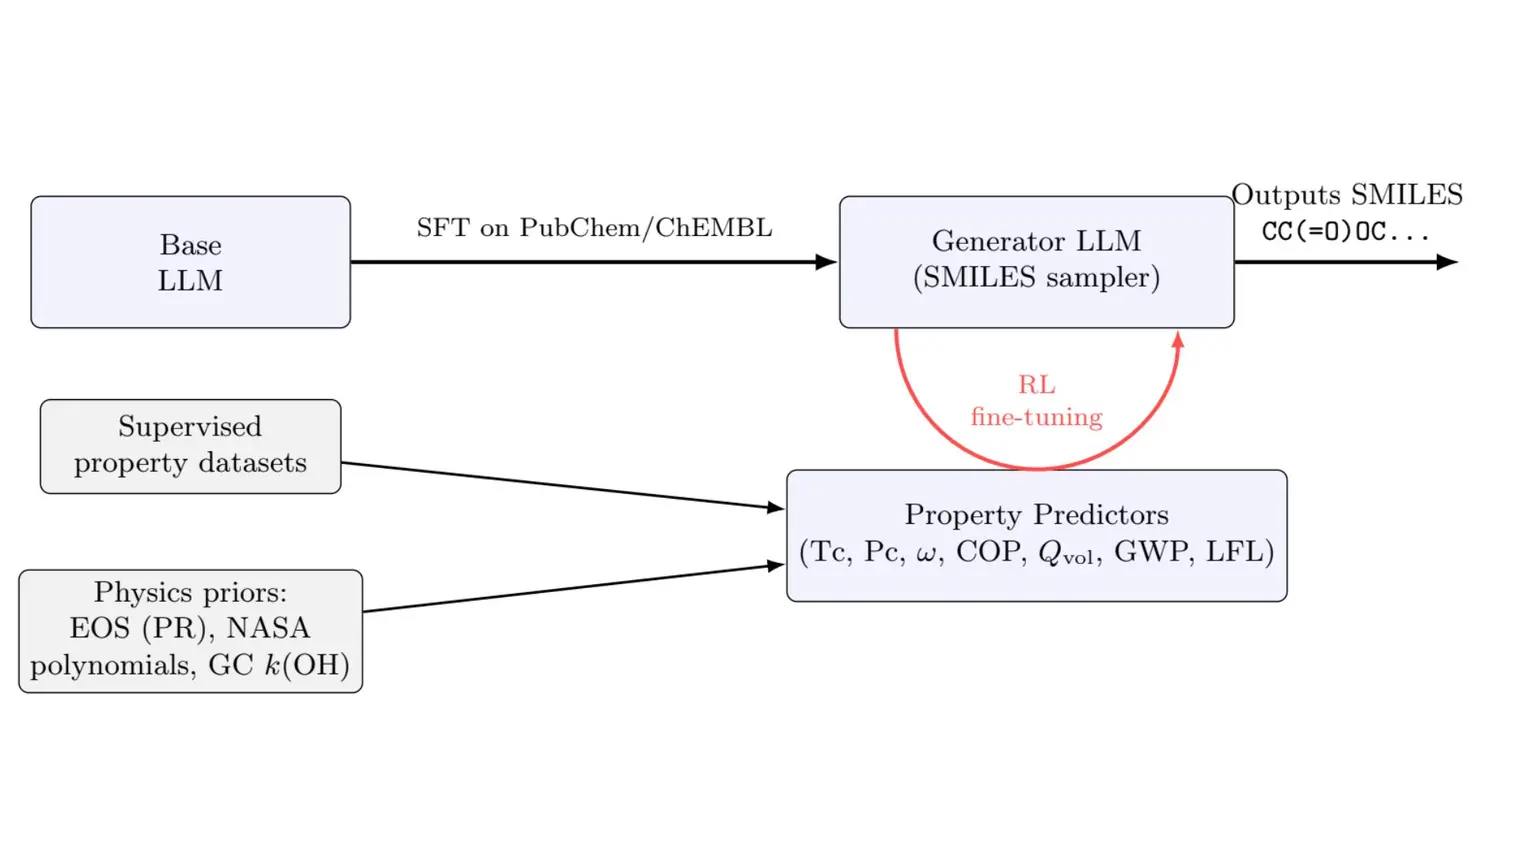
Recent advances in language models have enabled framing molecule generation as sequence modeling. However, existing approaches often rely on… (see more) single-objective reinforcement learning, limiting their applicability to real-world drug design, where multiple competing properties must be optimized. Traditional multi-objective reinforcement learning (MORL) methods require costly retraining for each new objective combination, making rapid exploration of trade-offs impractical. To overcome these limitations, we introduce Mol-MoE, a mixture-of-experts (MoE) architecture that enables efficient test-time steering of molecule generation without retraining. Central to our approach is a preference-based router training objective that incentivizes the router to combine experts in a way that aligns with user-specified trade-offs. This provides improved flexibility in exploring the chemical property space at test time, facilitating rapid trade-off exploration. Benchmarking against state-of-the-art methods, we show that Mol-MoE achieves superior sample quality and steerability.
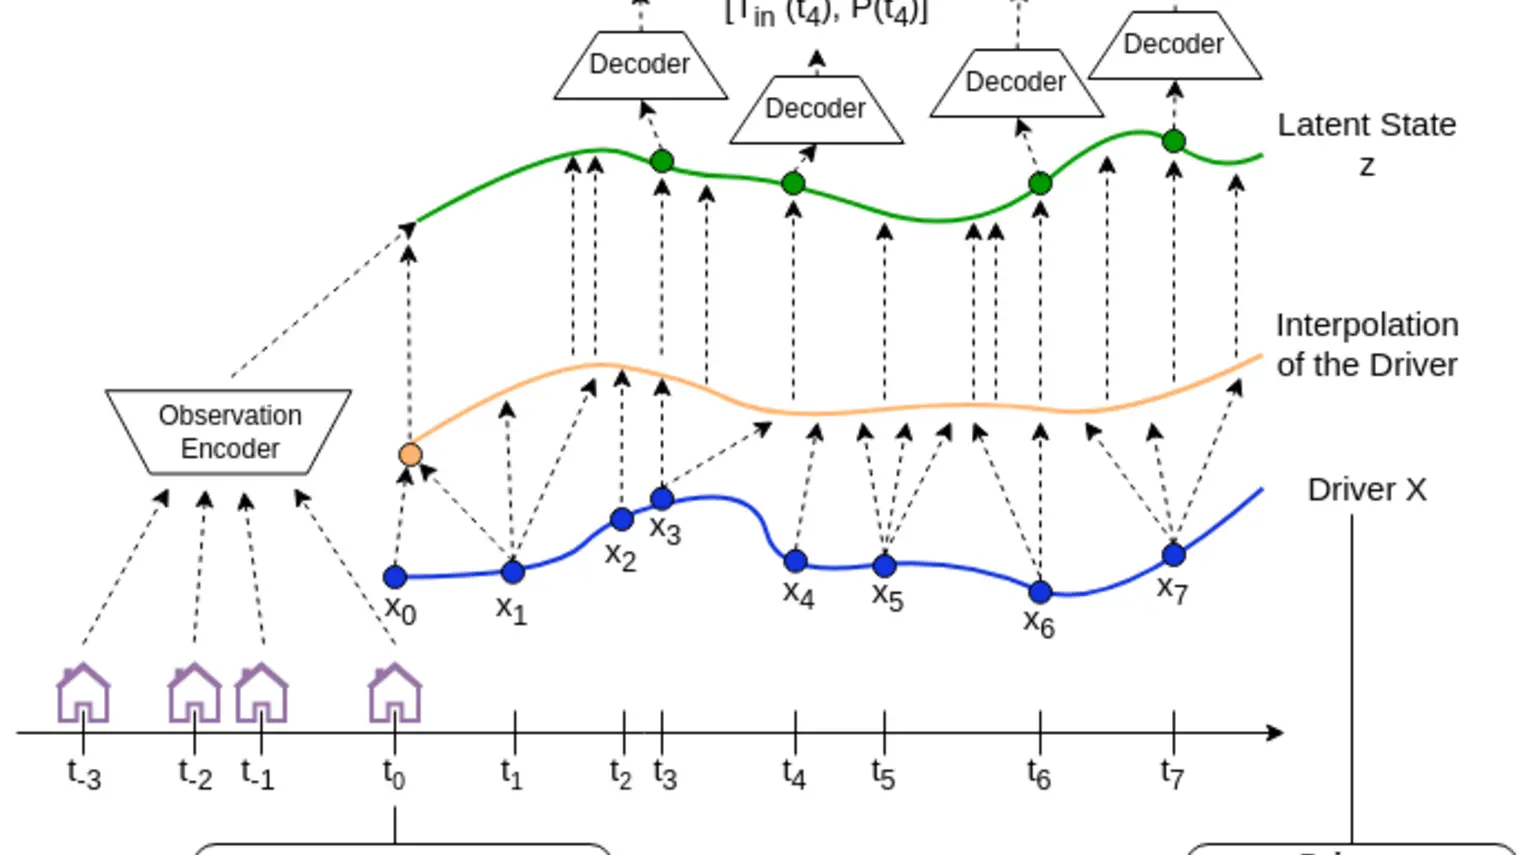
Neural differential equations for temperature control in buildings under demand response programs
Do Transformer World Models Give Better Policy Gradients?
A natural approach for reinforcement learning is to predict future rewards by unrolling a neural network world model, and to backpropagate t… (see more)hrough the resulting computational graph to learn a policy. However, this method often becomes impractical for long horizons since typical world models induce hard-to-optimize loss landscapes. Transformers are known to efficiently propagate gradients over long horizons: could they be the solution to this problem? Surprisingly, we show that commonly-used transformer world models produce circuitous gradient paths, which can be detrimental to long-range policy gradients. To tackle this challenge, we propose a class of world models called Actions World Models (AWMs), designed to provide more direct routes for gradient propagation. We integrate such AWMs into a policy gradient framework that underscores the relationship between network architectures and the policy gradient updates they inherently represent. We demonstrate that AWMs can generate optimization landscapes that are easier to navigate even when compared to those from the simulator itself. This property allows transformer AWMs to produce better policies than competitive baselines in realistic long-horizon tasks.
Bridging State and History Representations: Understanding Self-Predictive RL
Representations are at the core of all deep reinforcement learning (RL) methods for both Markov decision processes (MDPs) and partially obse… (see more)rvable Markov decision processes (POMDPs). Many representation learning methods and theoretical frameworks have been developed to understand what constitutes an effective representation. However, the relationships between these methods and the shared properties among them remain unclear. In this paper, we show that many of these seemingly distinct methods and frameworks for state and history abstractions are, in fact, based on a common idea of self-predictive abstraction. Furthermore, we provide theoretical insights into the widely adopted objectives and optimization, such as the stop-gradient technique, in learning self-predictive representations. These findings together yield a minimalist algorithm to learn self-predictive representations for states and histories. We validate our theories by applying our algorithm to standard MDPs, MDPs with distractors, and POMDPs with sparse rewards. These findings culminate in a set of preliminary guidelines for RL practitioners.
Course Correcting Koopman Representations
Koopman representations aim to learn features of nonlinear dynamical systems (NLDS) which lead to linear dynamics in the latent space. Theor… (see more)etically, such features can be used to simplify many problems in modeling and control of NLDS. In this work we study autoencoder formulations of this problem, and different ways they can be used to model dynamics, specifically for future state prediction over long horizons. We discover several limitations of predicting future states in the latent space and propose an inference-time mechanism, which we refer to as Periodic Reencoding, for faithfully capturing long term dynamics. We justify this method both analytically and empirically via experiments in low and high dimensional NLDS.
Motif: Intrinsic Motivation From Artificial Intelligence Feedback
Exploring rich environments and evaluating one's actions without prior knowledge is immensely challenging. In this paper, we propose Motif, … (see more)a general method to interface such prior knowledge from a Large Language Model (LLM) with an agent. Motif is based on the idea of grounding LLMs for decision-making without requiring them to interact with the environment: it elicits preferences from an LLM over pairs of captions to construct an intrinsic reward, which is then used to train agents with reinforcement learning. We evaluate Motif's performance and behavior on the challenging, open-ended and procedurally-generated NetHack game. Surprisingly, by only learning to maximize its intrinsic reward, Motif achieves a higher game score than an algorithm directly trained to maximize the score itself. When combining Motif's intrinsic reward with the environment reward, our method significantly outperforms existing approaches and makes progress on tasks where no advancements have ever been made without demonstrations. Finally, we show that Motif mostly generates intuitive human-aligned behaviors which can be steered easily through prompt modifications, while scaling well with the LLM size and the amount of information given in the prompt.
Maximum entropy GFlowNets with soft Q-learning
Generative Flow Networks (GFNs) have emerged as a powerful tool for sampling discrete objects from unnormalized distributions, offering a sc… (see more)alable alternative to Markov Chain Monte Carlo (MCMC) methods. While GFNs draw inspiration from maximum entropy reinforcement learning (RL), the connection between the two has largely been unclear and seemingly applicable only in specific cases. This paper addresses the connection by constructing an appropriate reward function, thereby establishing an exact relationship between GFNs and maximum entropy RL. This construction allows us to introduce maximum entropy GFNs, which, in contrast to GFNs with uniform backward policy, achieve the maximum entropy attainable by GFNs without constraints on the state space.
Decoupling regularization from the action space
Sobhan Mohammadpour
Regularized reinforcement learning (RL), particularly the entropy-regularized kind, has gained traction in optimal control and inverse RL. W… (see more)hile standard unregularized RL methods remain unaffected by changes in the number of actions, we show that it can severely impact their regularized counterparts. This paper demonstrates the importance of decoupling the regularizer from the action space: that is, to maintain a consistent level of regularization regardless of how many actions are involved to avoid over-regularization. Whereas the problem can be avoided by introducing a task-specific temperature parameter, it is often undesirable and cannot solve the problem when action spaces are state-dependent. In the state-dependent action context, different states with varying action spaces are regularized inconsistently. We introduce two solutions: a static temperature selection approach and a dynamic counterpart, universally applicable where this problem arises. Implementing these changes improves performance on the DeepMind control suite in static and dynamic temperature regimes and a biological design task.
Generative Active Learning for the Search of Small-Molecule Protein Binders
Cheng-Hao Liu
Éric Jolicoeur
Edward Ruediger
Andrei Nica
Daniel St-Cyr
Doris Alexandra Schuetz
Victor Ion Butoi
Saikrishna Gottipati
Prateek Gupta
Sasikanth Avancha
William Hamilton
Brooks Paige
Sanchit Misra
Bharat Kaul
José Miguel Hernández-Lobato
Marwin Segler
Michael Bronstein
Anne Marinier
Mike Tyers
Despite substantial progress in machine learning for scientific discovery in recent years, truly de novo design of small molecules which exh… (see more)ibit a property of interest remains a significant challenge. We introduce LambdaZero, a generative active learning approach to search for synthesizable molecules. Powered by deep reinforcement learning, LambdaZero learns to search over the vast space of molecules to discover candidates with a desired property. We apply LambdaZero with molecular docking to design novel small molecules that inhibit the enzyme soluble Epoxide Hydrolase 2 (sEH), while enforcing constraints on synthesizability and drug-likeliness. LambdaZero provides an exponential speedup in terms of the number of calls to the expensive molecular docking oracle, and LambdaZero de novo designed molecules reach docking scores that would otherwise require the virtual screening of a hundred billion molecules. Importantly, LambdaZero discovers novel scaffolds of synthesizable, drug-like inhibitors for sEH. In in vitro experimental validation, a series of ligands from a generated quinazoline-based scaffold were synthesized, and the lead inhibitor N-(4,6-di(pyrrolidin-1-yl)quinazolin-2-yl)-N-methylbenzamide (UM0152893) displayed sub-micromolar enzyme inhibition of sEH.
Using label propagation for learning temporally abstract actions in reinforcement learning
Pierre‐Luc Bacon