Portrait de Mirco Ravanelli

Mirco Ravanelli

Membre académique associé
Professeur agrégé, Concordia University, École de génie et d'informatique Gina-Cody
Professeur associé, Université de Montréal, Département d'informatique et de recherche opérationnelle
Sujets de recherche
Apprentissage profond

Biographie

Mirco Ravanelli est professeur adjoint à l'Université Concordia, professeur associé à l'Université de Montréal et membre associé de Mila – Institut québécois d’intelligence artificielle. Lauréat du prix Amazon Research 2022, il est expert en apprentissage profond et en IA conversationnelle, et a publié plus de 60 articles dans ces domaines. Il se concentre principalement sur les nouveaux algorithmes d'apprentissage profond, y compris l'apprentissage autosupervisé, continu, multimodal, coopératif et économe en énergie. Mirco Ravanelli a effectué son postdoctorat à Mila, sous la direction du professeur Yoshua Bengio. Il est notamment le fondateur et le chef de file de SpeechBrain, l'une des boîtes à outils en code source ouvert les plus largement adoptées dans le domaine du traitement de la parole et de l'IA conversationnelle.
Étudiants actuels

Baccalauréat - Concordia
Stagiaire de recherche - Concordia
Maîtrise recherche - Concordia University
Maîtrise recherche - Concordia
Collaborateur·rice de recherche
Superviseur⋅e principal⋅e :
Maîtrise recherche - Concordia
Doctorat - Concordia
Co-superviseur⋅e :
Maîtrise recherche - Concordia
Co-superviseur⋅e :
Maîtrise recherche - Concordia University
Stagiaire de recherche - Concordia
Collaborateur·rice de recherche - Université Laval
Superviseur⋅e principal⋅e :
Doctorat - Université Laval
Superviseur⋅e principal⋅e :
Maîtrise professionnelle - Concordia Univesity
Collaborateur·rice alumni - UdeM
Superviseur⋅e principal⋅e :
Collaborateur·rice de recherche - University of Toulon
Superviseur⋅e principal⋅e :
Stagiaire de recherche - Concordia

Publications

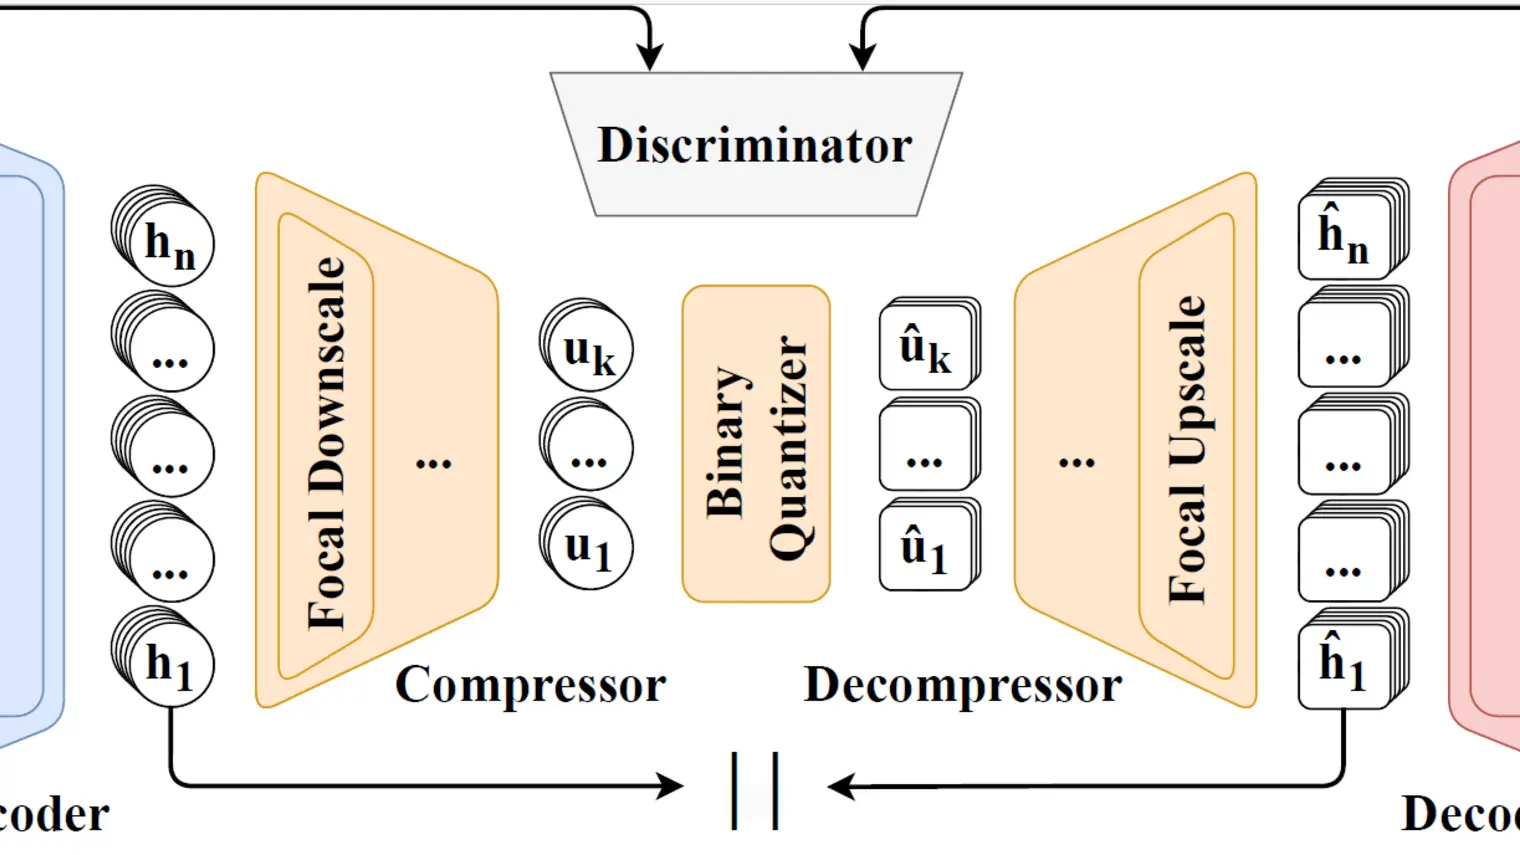
FocalCodec: Low-Bitrate Speech Coding via Focal Modulation Networks
Large language models have revolutionized natural language processing through self-supervised pretraining on massive datasets. Inspired by t… (voir plus)his success, researchers have explored adapting these methods to speech by discretizing continuous audio into tokens using neural audio codecs. However, existing approaches face limitations, including high bitrates, the loss of either semantic or acoustic information, and the reliance on multi-codebook designs when trying to capture both, which increases architectural complexity for downstream tasks. To address these challenges, we introduce FocalCodec, an efficient low-bitrate codec based on focal modulation that utilizes a single binary codebook to compress speech between 0.16 and 0.65 kbps. FocalCodec delivers competitive performance in speech resynthesis and voice conversion at lower bitrates than the current state-of-the-art, while effectively handling multilingual speech and noisy environments. Evaluation on downstream tasks shows that FocalCodec successfully preserves sufficient semantic and acoustic information, while also being well-suited for generative modeling. Demo samples and code are available at https://lucadellalib.github.io/focalcodec-web/.
From Speech to Sonography: Spectral Networks for Ultrasound Microstructure Classification
Ali K. Z. Tehrani
An Tang
Guy Cloutier
Iman Rafati
Bich Ngoc Nguyen
Quoc-Huy Trinh
Ivan Rosado-Mendez
Hassan Rivaz
The frequency dependence of backscattered radiofrequency (RF) signals produced by ultrasound scanners carries rich information related to th… (voir plus)e tissue microstructure (i.e., scatterer size, attenuation). This information can be sue to classify tissues based on microstructural changes associated to disease onset and progression. Conventional convolutional neural networks (CNNs) can learn this information directly from radio-frequency (RF) data, but they often struggle to achieve adequate frequency selectivity. This increases model complexity and convergence time, and limits generalization. To overcome these challenges, SincNet, originally developed for speech processing, was adapted to classify RF data based on differences in frequency properties. Rather than learning every filter coefficient, SincNet only learns each filter's low frequency and bandwidth, dramatically reducing the number of parameters and improving frequency resolution. For model interpretability, a Gradient-Weighted Filter Contribution is introduced, which highlights the importance of spectral bands. The approach was validated on three datasets: simulated data with different scatterer sizes, experimental phantom data, and in vivo data of rats which were fed a methionine and choline- deficient diet to develop liver steatosis, inflammation, and fibrosis. The modified SincNet consistently achieved the best results in material/tissue classifications.
Investigating the Effectiveness of Explainability Methods in Parkinson's Detection from Speech
Speech impairments in Parkinson's disease (PD) provide significant early indicators for diagnosis. While models for speech-based PD detectio… (voir plus)n have shown strong performance, their interpretability remains underexplored. This study systematically evaluates several explainability methods to identify PD-specific speech features, aiming to support the development of accurate, interpretable models for clinical decision-making in PD diagnosis and monitoring. Our methodology involves (i) obtaining attributions and saliency maps using mainstream interpretability techniques, (ii) quantitatively evaluating the faithfulness of these maps and their combinations obtained via union and intersection through a range of established metrics, and (iii) assessing the information conveyed by the saliency maps for PD detection from an auxiliary classifier. Our results reveal that, while explanations are aligned with the classifier, they often fail to provide valuable information for domain experts.
LMAC-TD: Producing Time Domain Explanations for Audio Classifiers
Neural networks are typically black-boxes that remain opaque with regards to their decision mechanisms. Several works in the literature have… (voir plus) proposed post-hoc explanation methods to alleviate this issue. This paper proposes LMAC-TD, a post-hoc explanation method that trains a decoder to produce explanations directly in the time domain. This methodology builds upon the foundation of L-MAC, Listenable Maps for Audio Classifiers, a method that produces faithful and listenable explanations. We incorporate SepFormer, a popular transformer-based time-domain source separation architecture. We show through a user study that LMAC-TD significantly improves the audio quality of the produced explanations while not sacrificing from faithfulness.
What Are They Doing? Joint Audio-Speech Co-Reasoning
In audio and speech processing, tasks usually focus on either the audio or speech modality, even when both sounds and human speech are prese… (voir plus)nt in the same audio clip. Recent Auditory Large Language Models (ALLMs) have made it possible to process audio and speech simultaneously within a single model, leading to further considerations of joint audio-speech tasks. In this paper, we establish a novel benchmark to investigate how well ALLMs can perform joint audio-speech processing. Specifically, we introduce Joint Audio-Speech Co-Reasoning (JASCO), a novel task that unifies audio and speech processing, strictly requiring co-reasoning across both modalities. We also release a scene-reasoning dataset called "What Are They Doing". Additionally, we provide deeper insights into the models' behaviors by analyzing their dependence on each modality.
Audio Prototypical Network For Controllable Music Recommendation
Traditional recommendation systems represent user preferences in dense representations obtained through black-box encoder models. While thes… (voir plus)e models often provide strong recommendation performance, they lack interpretability for users, leaving users unable to understand or control the system's modeling of their preferences. This limitation is especially challenging in music recommendation, where user preferences are highly personal and often evolve based on nuanced qualities like mood, genre, tempo, or instrumentation. In this paper, we propose an audio prototypical network for controllable music recommendation. This network expresses user preferences in terms of prototypes representative of semantically meaningful features pertaining to musical qualities. We show that the model obtains competitive recommendation performance compared to popular baseline models while also providing interpretable and controllable user profiles.
Generalization Limits of Graph Neural Networks in Identity Effects Learning
Graph Neural Networks (GNNs) have emerged as a powerful tool for data-driven learning on various graph domains. They are usually based on a … (voir plus)message-passing mechanism and have gained increasing popularity for their intuitive formulation, which is closely linked to the Weisfeiler-Lehman (WL) test for graph isomorphism to which they have been proven equivalent in terms of expressive power. In this work, we establish new generalization properties and fundamental limits of GNNs in the context of learning so-called identity effects, i.e., the task of determining whether an object is composed of two identical components or not. Our study is motivated by the need to understand the capabilities of GNNs when performing simple cognitive tasks, with potential applications in computational linguistics and chemistry. We analyze two case studies: (i) two-letters words, for which we show that GNNs trained via stochastic gradient descent are unable to generalize to unseen letters when utilizing orthogonal encodings like one-hot representations; (ii) dicyclic graphs, i.e., graphs composed of two cycles, for which we present positive existence results leveraging the connection between GNNs and the WL test. Our theoretical analysis is supported by an extensive numerical study.
A protocol for trustworthy EEG decoding with neural networks
Listenable Maps for Zero-Shot Audio Classifiers
Interpreting the decisions of deep learning models, including audio classifiers, is crucial for ensuring the transparency and trustworthines… (voir plus)s of this technology. In this paper, we introduce LMAC-ZS (Listenable Maps for Audio Classifiers in the Zero-Shot context), which, to the best of our knowledge, is the first decoder-based post-hoc interpretation method for explaining the decisions of zero-shot audio classifiers. The proposed method utilizes a novel loss function that maximizes the faithfulness to the original similarity between a given text-and-audio pair. We provide an extensive evaluation using the Contrastive Language-Audio Pretraining (CLAP) model to showcase that our interpreter remains faithful to the decisions in a zero-shot classification context. Moreover, we qualitatively show that our method produces meaningful explanations that correlate well with different text prompts.
SpeechBrain-MOABB: An open-source Python library for benchmarking deep neural networks applied to EEG signals
Audio Editing with Non-Rigid Text Prompts
In this paper, we explore audio-editing with non-rigid text edits. We show that the proposed editing pipeline is able to create audio edits … (voir plus)that remain faithful to the input audio. We explore text prompts that perform addition, style transfer, and in-painting. We quantitatively and qualitatively show that the edits are able to obtain results which outperform Audio-LDM, a recently released text-prompted audio generation model. Qualitative inspection of the results points out that the edits given by our approach remain more faithful to the input audio in terms of keeping the original onsets and offsets of the audio events.
Speech Self-Supervised Representations Benchmarking: a Case for Larger Probing Heads
Youcef Kemiche
Slim Essid
Self-supervised learning (SSL) leverages large datasets of unlabeled speech to reach impressive performance with reduced amounts of annotate… (voir plus)d data. The high number of proposed approaches fostered the emergence of comprehensive benchmarks that evaluate their performance on a set of downstream tasks exploring various aspects of the speech signal. However, while the number of considered tasks has been growing, most proposals rely upon a single downstream architecture that maps the frozen SSL representations to the task labels. This study examines how benchmarking results are affected by changes in the probing head architecture. Interestingly, we found that altering the downstream architecture structure leads to significant fluctuations in the performance ranking of the evaluated models. Against common practices in speech SSL benchmarking, we evaluate larger-capacity probing heads, showing their impact on performance, inference costs, generalization and multi-level feature exploitation.