Portrait of Mirco Ravanelli

Mirco Ravanelli

Associate Academic Member
Associate Professor, Concordia University
Adjunct Professor, Université de Montréal, Department of Computer Science and Operations Research
Research Topics
Deep Learning

Biography

I am an AI researcher, educator, and open-source leader working on the next generation of intelligent machines. I am also an Associate Professor at Concordia University, Adjunct Professor at Université de Montréal, and Associate Member of Mila – Quebec AI Institute. My research focuses on deep learning for Conversational AI, multimodal foundation models, interpretable AI, and efficient machine learning.

My work has resulted in over 100 scientific publications and has been recognized through international awards, including the Amazon Research Award. I had the privilege of completing my postdoctoral training at Mila under the supervision of Yoshua Bengio.

I am the founder and leader of SpeechBrain, one of the world's most widely adopted open-source toolkits for speech and conversational AI, used by researchers and engineers across academia and industry. SpeechBrain has become a global community effort, helping democratize access to cutting-edge AI technologies.

Beyond research, I am passionate about education and mentorship. I believe that advancing AI requires not only scientific breakthroughs but also training the next generation of researchers and engineers to develop AI responsibly and for the benefit of society.

Research interests: Conversational AI • Multimodal LLMs • Audio Tokens • Representation Learning • Interpretable AI • Efficient Deep Learning • Open-Source AI
Current Students

Undergraduate - Concordia University
Collaborating researcher - Concordia University
Master's Research - Concordia University University
Master's Research - Concordia University
Collaborating researcher
Principal supervisor :
Master's Research - Concordia University
PhD - Concordia University
Co-supervisor :
Master's Research - Concordia University
Co-supervisor :
Master's Research - Concordia University
Master's Research - Concordia University University
Research Intern - Concordia University
Collaborating researcher - Université Laval
Principal supervisor :
PhD - Université Laval
Principal supervisor :
Master's Research - Concordia University
Collaborating Alumni - Université de Montréal
Principal supervisor :
Postdoctorate - McGill University
PhD - Université de Montréal
Research Intern - Concordia University

Publications

Random Recursive Models
Jama Hussein Mohamud
Recursive models create computational depth through parameter reuse, offering a parameter-efficient alternative to increasing model size. Ho… (see more)wever, most recursive models repeatedly apply one learned transformation or a prescribed sequence of transformations, restricting computation to a fixed layer order. We introduce the Random Recursive Model (RRM), which maintains a pool of
GLaS-JEPA: Gaussian-Regularized Speech SSL without Engineered Prediction Targets
Samir Sadok
Thomas Hueber
Xavier Alameda-Pineda
Speech self-supervised learning aims to learn general-purpose representations for downstream speech tasks. However, current approaches rely … (see more)on complex, carefully designed prediction targets. We challenge this necessity with GLaS-JEPA, a framework that directly predicts the current encoder's continuous representations at masked positions, without contrastive learning, discrete targets, or separate EMA target encoders. We prevent representation collapse using SIGReg representation-space regularization, eliminating the need for engineered target-generation mechanisms. Pretrained on 960 hours of LibriSpeech, our 57M-parameter model achieves a 6.89% WER on frozen-encoder SUPERB ASR and a 25.87% CER on slot filling, outperforming the best non-distilled sub-90M baselines by 43.1% and 22.0%, respectively. These results demonstrate that highly competitive speech representations can emerge from a radically simplified training recipe.
Time-Incremental Continued Pretraining of LLMs: Knowledge Updates Without Catastrophic Forgetting
Salman Hussain Ali
Çağatay Yıldız
Large language models (LLMs) drift out of date the moment their pretraining ends, yet retraining from scratch is prohibitively expensive. Co… (see more)ntinued pretraining (CPT) is the natural remedy, but it is typically evaluated through a continual learning lens that assumes disjoint data streams. This is a poor fit for time-incremental updates on web-scale crawls, where successive snapshots share substantial URL overlap by design. We study time-incremental CPT in this realistic regime: continued pretraining on FineWeb-Edu dumps drawn strictly from after each model's knowledge cutoff, evaluated across six open-weight models spanning three families (OLMo2, Llama-3.1/3.2, Gemma-3-1B) and four parameter scales (1B-3B-7B-8B). We organize our findings around four practical questions. (i) Is knowledge acquired? Yes, but heterogeneously, and without catastrophic forgetting: five of six models also improve on pre-cutoff factual recall, and the gains track pretraining saturation (driven primarily by token budget per parameter). (ii) What does it cost? Almost nothing: the macro-average across a thirteen-task suite stays within 0.01 of the base for every model. (iii) What is the recipe? Data quality dominates quantity (a curated 6B-token slice matches a broader 40B one); the optima for knowledge acquisition and general capability are separated by roughly an order of magnitude in learning rate; and LoRA at sufficient rank matches full CPT. (iv) Does it survive deployment? CPT gains transfer through SFT, while DPO's effect is family-dependent. Together, these results paint a more optimistic picture of time-incremental CPT than the prior continual learning literature suggests.
ZipCodec: Ultra-Low-Frame-Rate Streaming Speech Coding
Neural audio codecs are a fundamental component of modern speech generation systems. While recent codecs achieve increasingly low bitrates, … (see more)reducing frame rate remains challenging, as each token must preserve more information while maintaining reconstruction quality. We present ZipCodec, a streaming neural speech codec operating at 6.25 Hz and 0.80 kbps with a theoretical latency of 160 ms. Our approach combines large-scale WavLM distillation with a redesigned transformer-based architecture, a scalar spherical quantizer, and a latency-aware streaming decoder. Experiments show that ZipCodec substantially outperforms existing streaming codecs at comparable bitrates in both reconstruction and downstream tasks, while operating at a significantly lower frame rate. Despite its 842M parameters, ZipCodec achieves real-time single-stream inference on a consumer-grade CPU. Demo samples, code and checkpoints are available at https://lucadellalib.github.io/zipcodec-web/.
Enhancing Audio Reasoning via Semantic Summary Prediction
Large Audio Language Models (LALMs) perform well on complex question answering but often show a reasoning gap, where explicit Chain-of-Thoug… (see more)ht (CoT) reduces accuracy compared to direct answers. We hypothesize that long reasoning sequences shift attention away from the audio input. To address this, we propose SPARE (Semantic Prediction for Audio REasoning), which introduces a register token aligned with the final conclusion using a cosine similarity loss with a Sentence-BERT embedding. This conditions the model's latent space with the target semantic goal before reasoning begins. Experiments on MMAU and MMAR with SALMONN show improved zero-shot reasoning and stronger early attention to audio without additional inference cost.
Controllable and Content-Based Recommendations
Traditional recommendation systems rely on latent (dense) representations, making them difficult to interpret and control. We propose the Co… (see more)ntrollable and Content-Based Recommendations (CCBR) framework, which builds its recommendations from textual user profile representations. CCBR plugs into collaborative filtering models and introduces controllability via text bottlenecks. We show that CCBR enables text-based and multimodal interventions, allowing users to steer the model towards the directions they prefer. Different from existing controllable recommendation systems, CCBR infers the text summaries directly from item contents (images, audio or video). Across image-, audio-, and video-based datasets, we demonstrate that the proposed framework obtains competitive model performance with standard (latent-representation) models while providing controllable model summaries via text. The model also outperforms TEARS, a recent baseline for controllable recommendation systems. Through systematic interventions, we demonstrate the efficacy of the user steering mechanism.
HybridCodec: Modeling Discrete and Continuous Representations for Efficient Speech Language Models
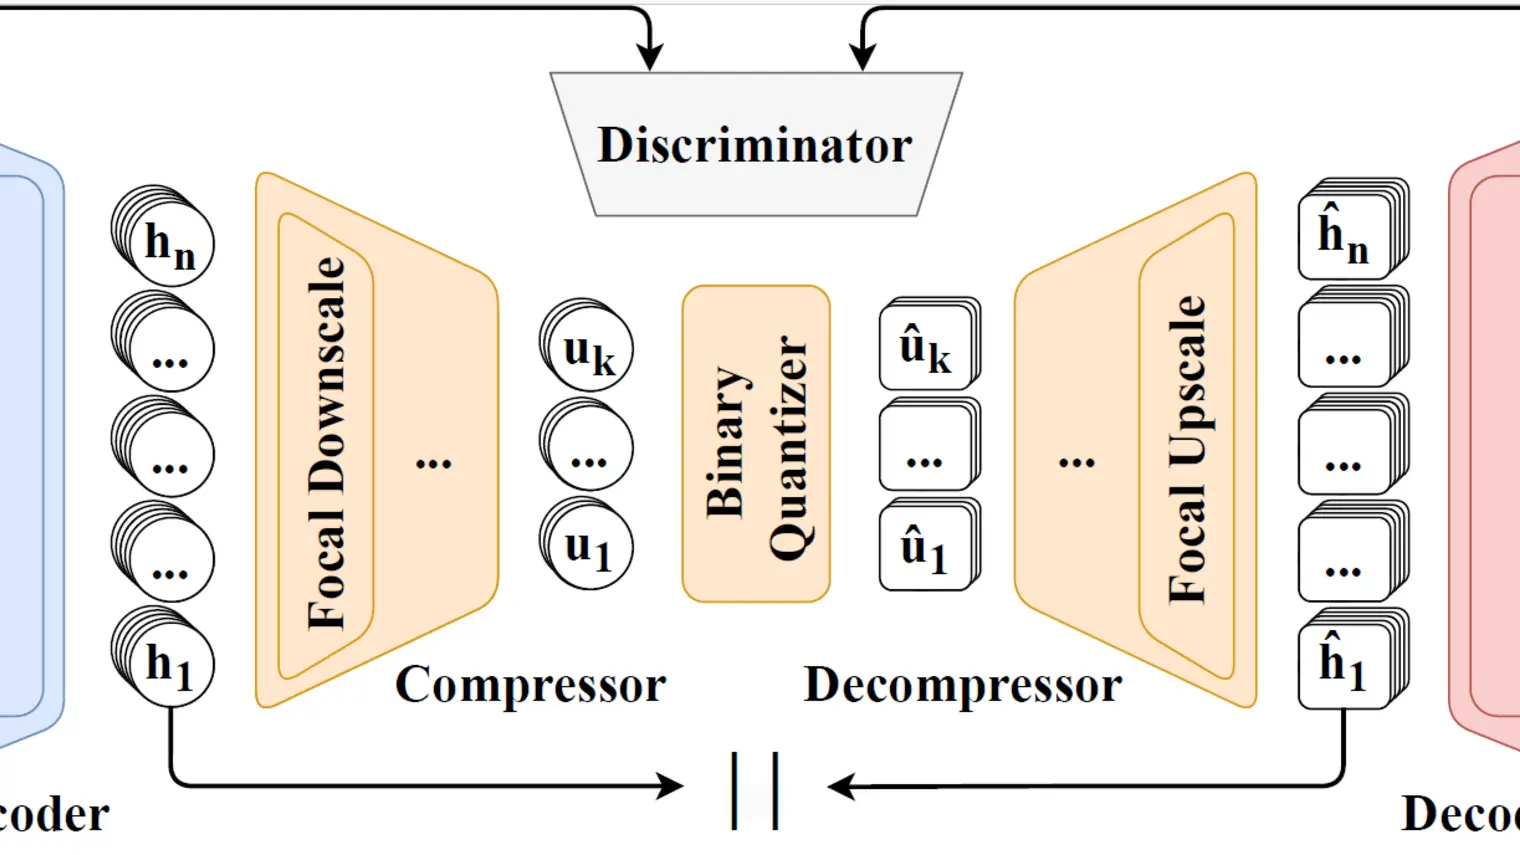
Discrete audio representations have become increasingly popular for building multimodal text-audio systems and integrating audio capabilitie… (see more)s into Large Language Models (LLMs). However, numerous studies report performance degradation on various downstream tasks due to information loss during discretization. To address this, we propose a novel approach combining temporally compressed discrete tokens with dimensionality-reduced continuous residuals. Our framework consists of a hybridized discrete-continuous focal modulation codec and a hybrid Transformer. This architecture performs autoregressive inference in the discrete domain, coupled with non-autoregressive prediction and continuous residual upsampling. Experimental results show that our approach significantly improves the retention of speaker characteristics compared to discrete-only methods, while simultaneously reducing the number of required autoregressive steps.
MambAdapter: Lightweight Mamba-Based Adapters for Parameter-Efficient Transfer Learning in Speech and Audio
Salman Hussain Ali
Umberto Cappellazzo
Fine-tuning Transformer-based foundation models has become the dominant strategy for domain adaptation in audio and speech processing. To re… (see more)duce the computational and memory costs of this process, parameter-efficient transfer learning (PETL) methods have been widely explored. Meanwhile, Mamba, a recent state-space model, has emerged as a promising alternative to Transformers for sequence modeling. In this work, we present MambAdapter, a parameter-efficient transfer learning approach that integrates Mamba into low-rank bottleneck adapters. Our design combines parameter sharing across adapters with the injection of a lightweight Mamba module, enabling more effective modeling of audio features. We demonstrate that MambAdapter matches or outperforms strong PETL baselines on four audio classification tasks and five speech recognition languages, even when operating under reduced parameter budgets.
Exploring Token-Space Manipulation in Latent Audio Tokenizers
Neural audio codecs provide compact discrete representations for speech generation and manipulation. However, most codecs organize tokens as… (see more) frame-level sequences, making it difficult to study or intervene on global factors of variation. In this work, we propose the Latent Audio Tokenizer for Token-space Editing (LATTE) that appends a fixed set of learnable latent tokens to the audio feature sequence and retains only these tokens for quantization and decoding. This design produces a compact, non-temporally aligned bottleneck in which each token can aggregate global information across the full utterance. We show that the resulting tokenizer preserves competitive reconstruction quality in low-bitrate speech coding settings while enabling simple token-space interventions. In particular, we find that swapping selected latent token positions between utterances can modify global attributes, such as speaker identity and background noise, and we evaluate these interventions on voice conversion and denoising tasks. Our results suggest that compact latent audio tokenizers can support controllable audio manipulation without supervision in task-specific editing models.
DASB - Discrete Audio and Speech Benchmark
Jarod Duret
Darius Petermann
Anastasia Kuznetsova
Discrete audio tokens have recently gained considerable attention for their potential to bridge audio and language processing, enabling mult… (see more)imodal language models that can both generate and understand audio. However, preserving key information such as phonetic content, speaker identity, and paralinguistic cues remains a major challenge. Identifying the optimal tokenizer and configuration is further complicated by inconsistent evaluation settings across existing studies. To address this, we introduce the Discrete Audio and Speech Benchmark (DASB), a comprehensive framework for benchmarking discrete audio tokens across speech, general audio, and music domains on a range of discriminative and generative tasks. Our results show that discrete representations are less robust than continuous ones and require careful tuning of factors such as model architecture, data size, learning rate, and capacity. Semantic tokens generally outperform acoustic tokens, but a gap remains between discrete tokens and continuous features, highlighting the need for further research. DASB codes, evaluation setup, and leaderboards are publicly available at https://poonehmousavi.github.io/DASB-website/.
Self-Routing: Parameter-Free Expert Routing from Hidden States
Jama Hussein Mohamud
Drew Wagner
Mixture-of-Experts (MoE) layers increase model capacity by activating only a small subset of experts per token, and typically rely on a lear… (see more)ned router to map hidden states to expert assignments. In this work, we ask whether a dedicated learned router is strictly necessary for MoE routing. We propose Self-Routing, a parameter-free routing mechanism that uses a designated subspace of the token hidden state directly as expert logits, eliminating the router projection entirely while leaving the rest of the MoE layer unchanged. We evaluate Self-Routing on language modeling across different expert counts and model scales, and on ImageNet-1K classification by comparing it against a standard learned router, random-routing baselines, and dense non-MoE baselines. Our results show that Self-Routing remains competitive with the learned-router baseline while removing all dedicated routing parameters, and yields more balanced expert utilization, with about 17\% higher average normalized routing entropy and no explicit load-balancing loss. On ImageNet-1K with DeiT-S/16, Self-Routing also slightly improves over the corresponding learned-router MoE. These findings suggest that effective MoE routing can emerge from the hidden representation itself without requiring a separate learned router module.
Cough acoustic analysis using artificial intelligence for COVID-19 detection: A comparative study of patient cohorts from Lima, Peru and Montreal, Canada
A. Zimmer
Vijay Ravi
Patricia Espinoza-Lopez
George P. Kafentzis
Samira Abbasgholizadeh Rahimi
Madhukar Pai
Cesar Ugarte-Gil
Serge Lapierre