Portrait de Mirco Ravanelli

Mirco Ravanelli

Membre académique associé
Professeur agrégé, Concordia University
Professeur adjoint, Université de Montréal, Département d'informatique et de recherche opérationnelle
Sujets de recherche
Apprentissage profond

Biographie

Je suis chercheur en IA, enseignant et chef de file de l'open source axé sur la prochaine génération de machines intelligentes.

Je suis également professeur agrégé à l'Université Concordia, professeur adjoint à l'Université de Montréal et membre associé de Mila – Institut québécois d'intelligence artificielle. Mes travaux de recherche portent sur l'apprentissage profond appliqué à l'IA conversationnelle, les modèles fondateurs multimodaux, l'IA explicable et l'apprentissage automatique efficient.

Mes travaux ont donné lieu à plus de 100 publications scientifiques et ont été couronnés par plusieurs prix internationaux, dont l'Amazon Research Award. J'ai eu le privilège d'effectuer mon stage postdoctoral à Mila sous la direction de Yoshua Bengio.

Je suis le fondateur et responsable de SpeechBrain, l'une des boîtes à outils open source les plus adoptées au monde pour la parole et l'IA conversationnelle, utilisée par les chercheurs et les ingénieurs tant dans le milieu académique qu'industriel. SpeechBrain est devenu un véritable effort communautaire mondial, contribuant à démocratiser l'accès aux technologies d'IA de pointe.

Au-delà de la recherche, je me passionne pour l'enseignement et le mentorat. Je suis convaincu que le progrès de l'IA ne repose pas uniquement sur les percées scientifiques, mais exige aussi de former la prochaine génération de chercheurs et d'ingénieurs à développer une IA responsable et au service de la société.

Domaines de recherche : IA conversationnelle • LLM multimodaux • Jetons audio (Audio Tokens) • Apprentissage de représentations • IA explicable • Apprentissage profond efficient • IA open source
Étudiants actuels

Baccalauréat - Concordia
Collaborateur·rice de recherche - Concordia
Maîtrise recherche - Concordia University
Maîtrise recherche - Concordia
Collaborateur·rice de recherche
Superviseur⋅e principal⋅e :
Maîtrise recherche - Concordia
Doctorat - Concordia
Co-superviseur⋅e :
Maîtrise recherche - Concordia
Co-superviseur⋅e :
Maîtrise recherche - Concordia University
Stagiaire de recherche - Concordia
Collaborateur·rice de recherche - Université Laval
Superviseur⋅e principal⋅e :
Doctorat - Université Laval
Superviseur⋅e principal⋅e :
Maîtrise recherche - Concordia
Collaborateur·rice alumni - UdeM
Superviseur⋅e principal⋅e :
Stagiaire de recherche - Concordia

Publications

Adaptive Order Policies for Masked Diffusion
Masked diffusion models have seen great success in capturing data distributions over discrete sequences in domains such as text and proteins… (voir plus). These models generate data by iteratively unmasking tokens starting from a fully masked sequence, with the unmasking order typically chosen at random or using a heuristic based on denoiser probabilities. In this work, we propose a scheme for learning the unmasking order using an additional lightweight policy network on top of a diffusion model. Our proposed loss reweights terms in the masked diffusion loss according to policy probabilities, and results in a policy that prefers positions where the denoiser is more likely to be correct. We study this loss in two settings: (i) training solely the policy while using a frozen pre-trained denoiser, and (ii) training the policy and denoiser jointly with the weighted loss to allow for mutual adaptation. We demonstrate that our approach outperforms common heuristics on problems that are sensitive to token ordering, such as combinatorial problems, proteins as well as various coding and language tasks.
DASB - Discrete Audio and Speech Benchmark
Jarod Duret
Darius Petermann
Anastasia Kuznetsova
Duret, Jarod
Kuznetsova, Anastasia
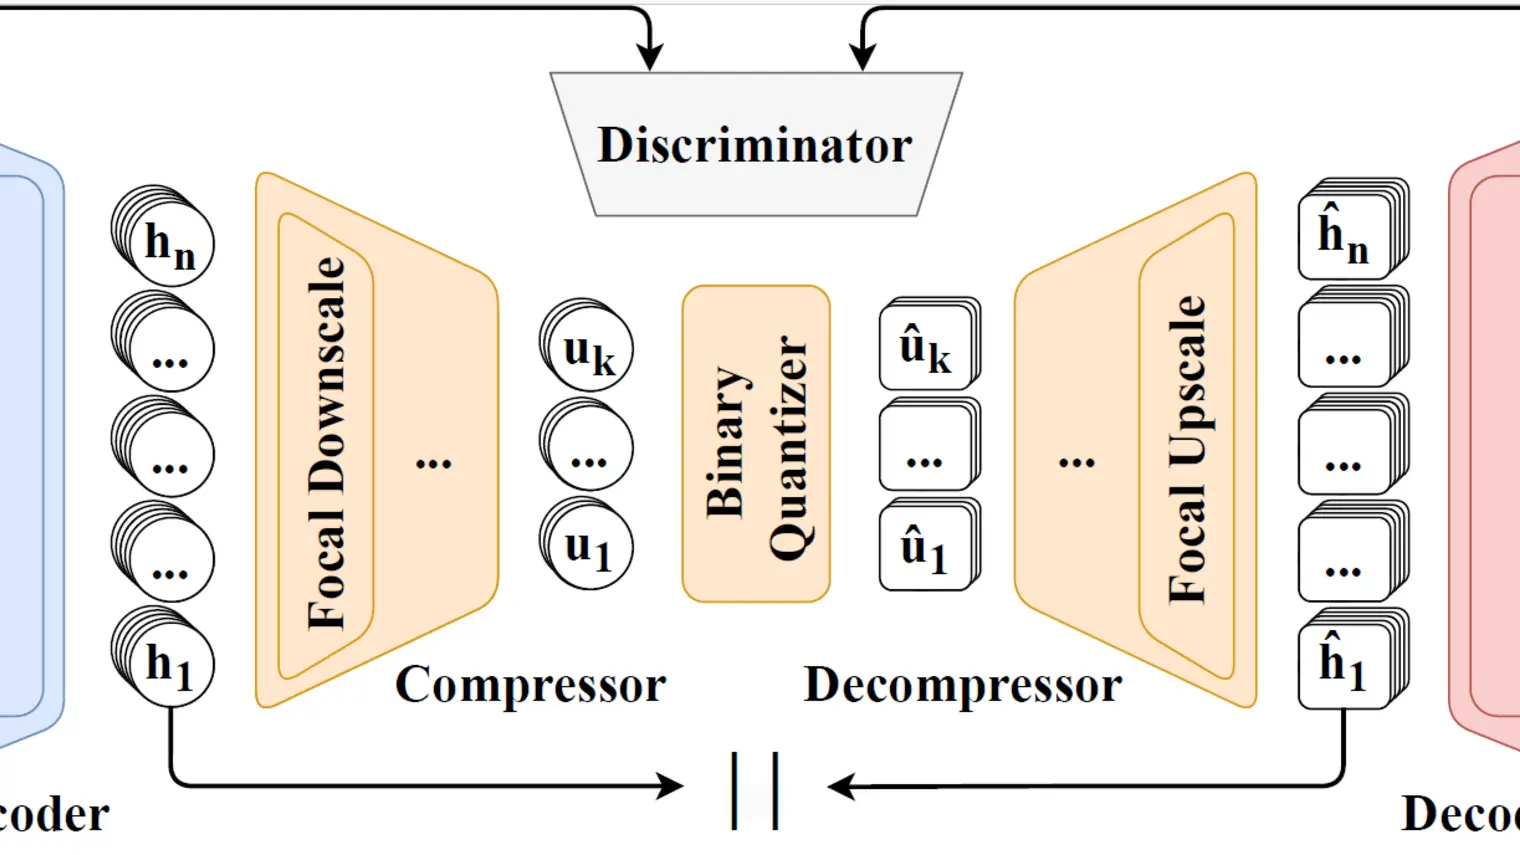
Discrete audio tokens have recently gained considerable attention for their potential to bridge audio and language processing, enabling mult… (voir plus)imodal language models that can both generate and understand audio. However, preserving key information such as phonetic content, speaker identity, and paralinguistic cues remains a major challenge. Identifying the optimal tokenizer and configuration is further complicated by inconsistent evaluation settings across existing studies. To address this, we introduce the Discrete Audio and Speech Benchmark (DASB), a comprehensive framework for benchmarking discrete audio tokens across speech, general audio, and music domains on a range of discriminative and generative tasks. Our results show that discrete representations are less robust than continuous ones and require careful tuning of factors such as model architecture, data size, learning rate, and capacity. Semantic tokens generally outperform acoustic tokens, but a gap remains between discrete tokens and continuous features, highlighting the need for further research. DASB codes, evaluation setup, and leaderboards are publicly available at https://poonehmousavi.github.io/DASB-website/.
Listen First, Then Answer: Timestamp-Grounded Speech Reasoning
Large audio-language models (LALMs) can generate reasoning chains for their predictions, but it remains unclear whether these reasoning chai… (voir plus)ns remain grounded in the input audio. In this paper, we propose an RL-based strategy that grounds the reasoning outputs of LALMs with explicit timestamp annotations referring to relevant segments of the audio signal. Our analysis shows that timestamp grounding leads the model to attend more strongly to audio tokens during reasoning generation. Experiments on four speech-based benchmark datasets demonstrate that our approach improves performance compared to both zero-shot reasoning and fine-tuning without timestamp grounding. Additionally, grounding amplifies desirable reasoning behaviors, such as region exploration, audiology verification, and consistency, underscoring the importance of grounding mechanisms for faithful multimodal reasoning.
LL-SDR: Low-Latency Speech enhancement through Discrete Representations
Many speech enhancement (SE) methods rely on continuous representations. Recently, discrete audio tokens have been explored to enable autore… (voir plus)gressive generation for SE. However, it remains unclear whether discretization itself consistently improves SE performance. In this paper, we introduce LL-SDR, a token-based speech enhancement framework that explicitly leverages discretization to better separate speech and noise. Our first contribution is a Variance-Ordered Residual Vector Quantizer (VO-RVQ), designed to disentangle speech and noise distributions during tokenization. Second, we propose a latent-space discriminator to better align enhanced embeddings with semantic embeddings. Experiments show that LL-SDR outperforms continuous baselines and matches the performance of autoregressive token-based approaches, while enabling lightweight, low-latency speech enhancement in both reverberant and non-reverberant noisy environments. Demos and source code are available at our project websites.
Factorized Self-Supervised Speech Tokenization
Nicol Visser
Hugo Seuté
Herman Kamper
The Kernel Reality Check: Benchmarking and Distilling Efficient Attention at Scale
Wav2Aug: A Drop-In Speech Augmentation Policy
SpecAugment is the dominant speech augmentation policy, but researchers have studied it primarily for automatic speech recognition (ASR), an… (voir plus)d it operates on spectrograms, limiting its applicability to other speech tasks and waveform models. We propose Wav2Aug, a drop-in waveform augmentation policy that randomly samples two augmentations from a calibrated pool of waveform transformations. We calibrate the augmentation hyperparameters once and reuse them across tasks and architectures, eliminating task-specific tuning. Experiments on ten speech benchmarks show that Wav2Aug achieves ASR performance comparable to SpecAugment while improving over it on average across non-ASR tasks, yielding an average relative error reduction of 12.8% over the strongest compatible SpecAugment baseline. We further show that multi-view training provides additional gains, with two augmented views offering the best tradeoff between performance and computational cost.
SMEBENCH: Benchmarking Neural Music Editing with Synthetized MIDI Edits
Neural music editing requires a system to perform a requested change while preserving the musical content that should remain unchanged. Exis… (voir plus)ting evaluations often lack a paired target edit, making these requirements difficult to measure separately. We introduce SMEBench, a large-scale benchmark of controlled music edits constructed by modifying symbolic MIDI performances and rendering matched source and target audio. Each example contains a source, an instruction, a paired target, edit metadata, and complementary descriptions. The benchmark covers twelve instrumentation, articulation, dynamics, and pitch operations and includes a balanced 3,600-example test set together with a smaller real-audio complement derived from multitrack recordings. The paired targets allow source preservation, target agreement, and textual compatibility to be evaluated independently. We use these references to diagnose common audio-editing metrics and benchmark six representative editing systems, showing that the metric used to rank a system can materially change the conclusion. The dataset is available at our repository.
Audio-R1: Audio Reasoning through Reinforcement Learning on Self-Supervised Tasks
Reasoning is increasingly important for large audio-language models (LALMs), yet remains relatively underexplored compared with text-only an… (voir plus)d vision-language models. We introduce Audio-R1, a reinforcement learning (RL) post-training framework that revisits audio self-supervised learning as a source of verifiable rewards for improving audio understanding and reasoning task performance. Audio-R1 uses answers automatically determined during the construction of self-supervised tasks to verify model responses and compute rewards. Experiments across multiple LALMs and diverse audio benchmarks show consistent performance gains, while ablations demonstrate the benefits of each self-supervised task and additional gains from joint training. While both supervised fine-tuning and Audio-R1 improve self-supervised task accuracy, Audio-R1 further improves performance on downstream tasks distinct from the training tasks. These results highlight the potential of RL post-training with self-supervised audio tasks to improve downstream performance and reasoning-trace quality.
Listen-to-Reason: Listen with Experts, Retrieve over a Graph, Reason with LLMs
Large audio-language models (LALMs) fuse an audio encoder into a large language model (LLM) through multi-stage training. This coupling mean… (voir plus)s that a new domain or a stronger LLM requires retraining, and their answers cannot be traced to what the model heard: a chain-of-thought is a post-hoc account. We propose Listen-to-Reason (L2R), an interpretable-by-design pipeline that passes audio to the LLM through an explicit, human-readable tree: small heads on frozen expert encoders map each chunk of a clip to semantically meaningful nodes on the tree (for speech, music and environmental sound), and a frozen text-only LLM answers from these nodes and an ASR transcript without hearing the clip. Every answer can therefore be traced to the nodes and transcript it read, and the nodes are causal: replacing the deciding node with a distractor overturns 78% of correct answers on SAKURA. With a 7B reader, L2R outperforms all LALMs we compare against on SAKURA and trails them by 6-12 points on MMAU and MMAR, despite training about 1,400x fewer parameters on orders of magnitude less audio data. However, because any LLM can serve as the reader, we show that a stronger reader narrows this gap without retraining any audio component. A new domain is added with one small head: with five labelled clips per species, it outperforms QLoRA fine-tuning of an LALM on the same clips by 13-26 points.
Steering Speech-Language Models: Training-Free Task Specialization via Contrastive Activation Addition
Yanis Labrak
Sergio Burdisso
Petr Motlicek
Hervé Bredin
Activation steering has proven effective for controlling the behavior of Large Language Models (LLMs) at inference time, but its application… (voir plus) to SpeechLLMs remains new, and training-free steering approaches for such models are still largely unexplored. We propose a training-free Contrastive Activation Addition (CAA) protocol that derives steering vectors for common speech tasks (e.g. transcription) in SpeechLLMs from a small number of labeled utterances. We showcase that adding these vectors in the representation space, at inference time, enforces better the targeted speech task. We further show that, when combined with prompting, these vectors yield to consistent improvement over prompting alone on most evaluated tasks such as Automatic Speech Recognition (ASR) or Emotion Recognition (ER), and transfer to out-of-domain data. We additionally demonstrate the usefulness of script-normalization directions to enforce the target script of a specific language.
AnchorPrompt: Self-Distilled Soft Prompts for Robust Audio-Language Models
Large audio-language models (LALMs) are sensitive to input perturbations, such as noise, waveform corruption, and adversarial injections. We… (voir plus) propose AnchorPrompt, an efficient adaptation method that keeps the model frozen and learns a single block of prompt vectors inserted at the decoder input, between the audio and question embeddings. We train these vectors through self-distillation over diverse audio and text perturbations. To improve answer consistency and mitigate hallucination, we use the model's prediction on the clean recording as the target for answerable inputs, and assign a refusal target when the audio lacks sufficient evidence to answer. Furthermore, AnchorPrompt is perturbation-agnostic at inference, requiring no prior detection of perturbations and enabling zero-shot transfer to unseen distortions. We evaluate three LALMs across three benchmarks and show that AnchorPrompt improves answer consistency in most tested conditions. Clean accuracy improves in six of nine model-benchmark pairs, with minimal impact on the remainder of 1.2% at most. Crucially, AnchorPrompt reduces hallucinations under severe audio corruption while keeping false refusals on clean audio rare. Finally, these consistency gains transfer to unseen perturbations, such as choice permutations and reverberation.