


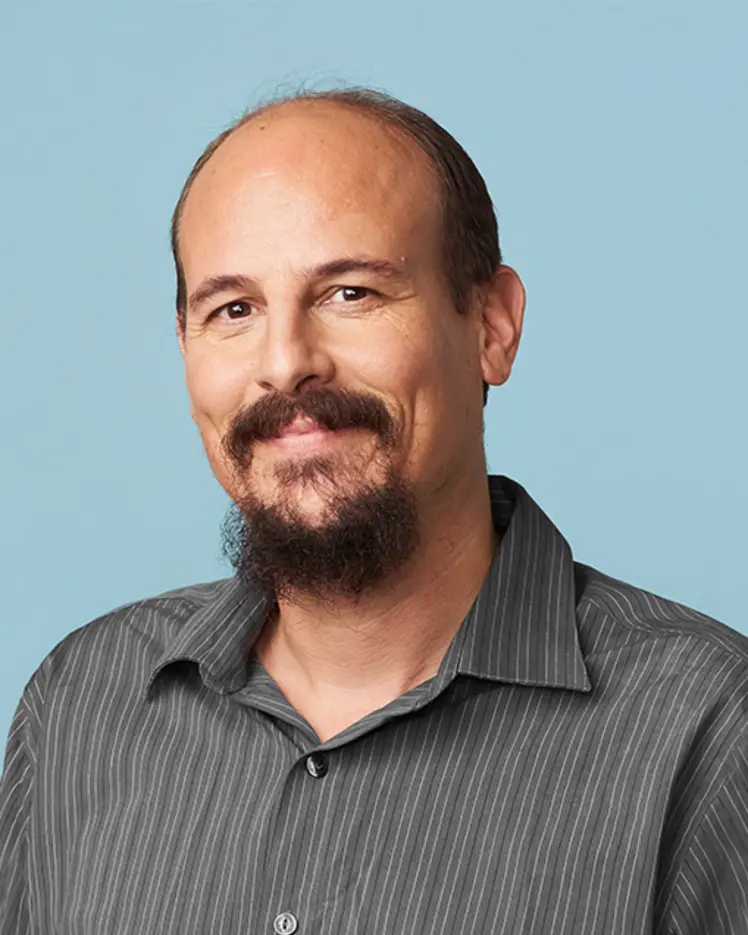
Portrait de Guillaume Rabusseau

Guillaume Rabusseau

Membre académique principal
Chaire en IA Canada-CIFAR
Professeur adjoint, Université de Montréal
Sujets de recherche
Apprentissage profond
Apprentissage sur graphes
Factorisation tensorielle
Modèles probabilistes
Réseaux de neurones en graphes
Réseaux de neurones récurrents
Systèmes de recommandation
Théorie de l'apprentissage automatique
Théorie de l'information quantique

Biographie

Depuis septembre 2018, je suis professeur adjoint à Mila – Institut québécois d’intelligence artificielle et au Département d'informatique et de recherche opérationnelle (DIRO) de l'Université de Montréal (UdeM). Je suis titulaire d’une chaire de recherche en IA Canada-CIFAR depuis mars 2019. Avant de me joindre à l’UdeM, j’ai été chercheur postdoctoral au laboratoire de raisonnement et d'apprentissage de l'Université McGill, où j'ai travaillé avec Prakash Panangaden, Joelle Pineau et Doina Precup.

J'ai obtenu mon doctorat en 2016 à l’Université d’Aix-Marseille (AMU), où j'ai travaillé dans l'équipe Qarma (apprentissage automatique et multimédia), sous la supervision de François Denis et Hachem Kadri. Auparavant, j'ai obtenu une maîtrise en informatique fondamentale de l'AMU et une licence en informatique de la même université en formation à distance.

Je m'intéresse aux méthodes de tenseurs pour l'apprentissage automatique et à la conception d'algorithmes d'apprentissage pour les données structurées par l’utilisation de l'algèbre linéaire et multilinéaire (par exemple, les méthodes spectrales).

Étudiants actuels

Postdoctorat - McGill
Co-superviseur⋅e :
Stagiaire de recherche - UdeM
Collaborateur·rice de recherche - McGill
Superviseur⋅e principal⋅e :
Postdoctorat - McGill
Co-superviseur⋅e :
Stagiaire de recherche - Polytechnique
Collaborateur·rice de recherche - INRIA
Collaborateur·rice de recherche - UdeM
Co-superviseur⋅e :
Stagiaire de recherche - UdeM

Publications

Adaptive Learning of Tensor Network Structures
Tensor Networks (TN) offer a powerful framework to efficiently represent very high-dimensional objects. TN have recently shown their potenti… (voir plus)al for machine learning applications and offer a unifying view of common tensor decomposition models such as Tucker, tensor train (TT) and tensor ring (TR). However, identifying the best tensor network structure from data for a given task is challenging. In this work, we leverage the TN formalism to develop a generic and efficient adaptive algorithm to jointly learn the structure and the parameters of a TN from data. Our method is based on a simple greedy approach starting from a rank one tensor and successively identifying the most promising tensor network edges for small rank increments. Our algorithm can adaptively identify TN structures with small number of parameters that effectively optimize any differentiable objective function. Experiments on tensor decomposition, tensor completion and model compression tasks demonstrate the effectiveness of the proposed algorithm. In particular, our method outperforms the state-of-the-art evolutionary topology search [Li and Sun, 2020] for tensor decomposition of images (while being orders of magnitude faster) and finds efficient tensor network structures to compress neural networks outperforming popular TT based approaches [Novikov et al., 2015].
On Overfitting and Asymptotic Bias in Batch Reinforcement Learning with Partial Observability (Extended Abstract)
When an agent has limited information on its environment, the suboptimality of an RL algorithm can be decomposed into the sum of two terms: … (voir plus)a term related to an asymptotic bias (suboptimality with unlimited data) and a term due to overfitting (additional suboptimality due to limited data). In the context of reinforcement learning with partial observability, this paper provides an analysis of the tradeoff between these two error sources. In particular, our theoretical analysis formally characterizes how a smaller state representation increases the asymptotic bias while decreasing the risk of overfitting.
Efficient Planning under Partial Observability with Unnormalized Q Functions and Spectral Learning
Tensorized Random Projections
Beheshteh T. Rakhshan
RandomNet: Towards Fully Automatic Neural Architecture Design for Multimodal Learning
Almost all neural architecture search methods are evaluated in terms of performance (i.e. test accuracy) of the model structures that it fin… (voir plus)ds. Should it be the only metric for a good autoML approach? To examine aspects beyond performance, we propose a set of criteria aimed at evaluating the core of autoML problem: the amount of human intervention required to deploy these methods into real world scenarios. Based on our proposed evaluation checklist, we study the effectiveness of a random search strategy for fully automated multimodal neural architecture search. Compared to traditional methods that rely on manually crafted feature extractors, our method selects each modality from a large search space with minimal human supervision. We show that our proposed random search strategy performs close to the state of the art on the AV-MNIST dataset while meeting the desirable characteristics for a fully automated design process.
Neural Architecture Search for Class-incremental Learning
In class-incremental learning, a model learns continuously from a sequential data stream in which new classes occur. Existing methods often … (voir plus)rely on static architectures that are manually crafted. These methods can be prone to capacity saturation because a neural network's ability to generalize to new concepts is limited by its fixed capacity. To understand how to expand a continual learner, we focus on the neural architecture design problem in the context of class-incremental learning: at each time step, the learner must optimize its performance on all classes observed so far by selecting the most competitive neural architecture. To tackle this problem, we propose Continual Neural Architecture Search (CNAS): an autoML approach that takes advantage of the sequential nature of class-incremental learning to efficiently and adaptively identify strong architectures in a continual learning setting. We employ a task network to perform the classification task and a reinforcement learning agent as the meta-controller for architecture search. In addition, we apply network transformations to transfer weights from previous learning step and to reduce the size of the architecture search space, thus saving a large amount of computational resources. We evaluate CNAS on the CIFAR-100 dataset under varied incremental learning scenarios with limited computational power (1 GPU). Experimental results demonstrate that CNAS outperforms architectures that are optimized for the entire dataset. In addition, CNAS is at least an order of magnitude more efficient than naively using existing autoML methods.
Recognizable series on graphs and hypergraphs
Raphaël Bailly
François Denis
Connecting Weighted Automata and Recurrent Neural Networks through Spectral Learning
In this paper, we unravel a fundamental connection between weighted finite automata~(WFAs) and second-order recurrent neural networks~(2-RNN… (voir plus)s): in the case of sequences of discrete symbols, WFAs and 2-RNNs with linear activation functions are expressively equivalent. Motivated by this result, we build upon a recent extension of the spectral learning algorithm to vector-valued WFAs and propose the first provable learning algorithm for linear 2-RNNs defined over sequences of continuous input vectors. This algorithm relies on estimating low rank sub-blocks of the so-called Hankel tensor, from which the parameters of a linear 2-RNN can be provably recovered. The performances of the proposed method are assessed in a simulation study.
Learning Graph Weighted Models on Pictures
Graph Weighted Models (GWMs) have recently been proposed as a natural generalization of weighted automata over strings and trees to arbitrar… (voir plus)y families of labeled graphs (and hypergraphs). A GWM generically associates a labeled graph with a tensor network and computes a value by successive contractions directed by its edges. In this paper, we consider the problem of learning GWMs defined over the graph family of pictures (or 2-dimensional words). As a proof of concept, we consider regression and classification tasks over the simple Bars & Stripes and Shifting Bits picture languages and provide an experimental study investigating whether these languages can be learned in the form of a GWM from positive and negative examples using gradient-based methods. Our results suggest that this is indeed possible and that investigating the use of gradient-based methods to learn picture series and functions computed by GWMs over other families of graphs could be a fruitful direction.
Clustering-Oriented Representation Learning with Attractive-Repulsive Loss
The standard loss function used to train neural network classifiers, categorical cross-entropy (CCE), seeks to maximize accuracy on the trai… (voir plus)ning data; building useful representations is not a necessary byproduct of this objective. In this work, we propose clustering-oriented representation learning (COREL) as an alternative to CCE in the context of a generalized attractive-repulsive loss framework. COREL has the consequence of building latent representations that collectively exhibit the quality of natural clustering within the latent space of the final hidden layer, according to a predefined similarity function. Despite being simple to implement, COREL variants outperform or perform equivalently to CCE in a variety of scenarios, including image and news article classification using both feed-forward and convolutional neural networks. Analysis of the latent spaces created with different similarity functions facilitates insights on the different use cases COREL variants can satisfy, where the Cosine-COREL variant makes a consistently clusterable latent space, while Gaussian-COREL consistently obtains better classification accuracy than CCE.
Minimization of Graph Weighted Models over Circular Strings
Nonlinear Weighted Finite Automata