


Portrait de Rishabh Agarwal

Rishabh Agarwal

Membre industriel associé
Professeur associé, McGill University, École d'informatique
Google DeepMind
Sujets de recherche
Apprentissage par renforcement
Apprentissage profond
Grands modèles de langage (LLM)

Biographie

Je suis chercheur dans l'équipe DeepMind de Google à Montréal, professeur adjoint à l'Université McGill et membre industriel associé à Mila - Institut québécois d'intelligence artificielle. J'ai réalisé mon doctorat au sein de Mila sous la supervision d'Aaron Courville et Marc Bellemare. Avant cela, j'ai eu l'opportunité de travailler pendant un an avec l'équipe de Geoffrey Hinton chez Google Brain, à Toronto. J'ai obtenu mon diplôme en informatique et en ingénierie à l'IIT Bombay.

Mes recherches se concentrent sur les modèles de langage et l'apprentissage par renforcement profond (RL). J'ai eu l'honneur de recevoir un prix pour un article exceptionnel présenté à NeurIPS.
Étudiants actuels

Doctorat - UdeM
Superviseur⋅e principal⋅e :

Publications

Proto-Value Networks: Scaling Representation Learning with Auxiliary Tasks
Auxiliary tasks improve the representations learned by deep reinforcement learning agents. Analytically, their effect is reasonably well und… (voir plus)erstood; in practice, however, their primary use remains in support of a main learning objective, rather than as a method for learning representations. This is perhaps surprising given that many auxiliary tasks are defined procedurally, and hence can be treated as an essentially infinite source of information about the environment. Based on this observation, we study the effectiveness of auxiliary tasks for learning rich representations, focusing on the setting where the number of tasks and the size of the agent's network are simultaneously increased. For this purpose, we derive a new family of auxiliary tasks based on the successor measure. These tasks are easy to implement and have appealing theoretical properties. Combined with a suitable off-policy learning rule, the result is a representation learning algorithm that can be understood as extending Mahadevan & Maggioni (2007)'s proto-value functions to deep reinforcement learning -- accordingly, we call the resulting object proto-value networks. Through a series of experiments on the Arcade Learning Environment, we demonstrate that proto-value networks produce rich features that may be used to obtain performance comparable to established algorithms, using only linear approximation and a small number (~4M) of interactions with the environment's reward function.
A Novel Stochastic Gradient Descent Algorithm for LearningPrincipal Subspaces
Joshua Greaves
Mark Rowland
Fabian Pedregosa
Bellemare Marc-Emmanuel
In this paper, we derive an algorithm that learns a principal subspace from sample entries, can be applied when the approximate subspace i… (voir plus)s represented by a neural network, and hence can bescaled to datasets with an effectively infinite number of rows and columns. Our method consistsin defining a loss function whose minimizer is the desired principal subspace, and constructing agradient estimate of this loss whose bias can be controlled.
Reincarnating Reinforcement Learning: Reusing Prior Computation to Accelerate Progress
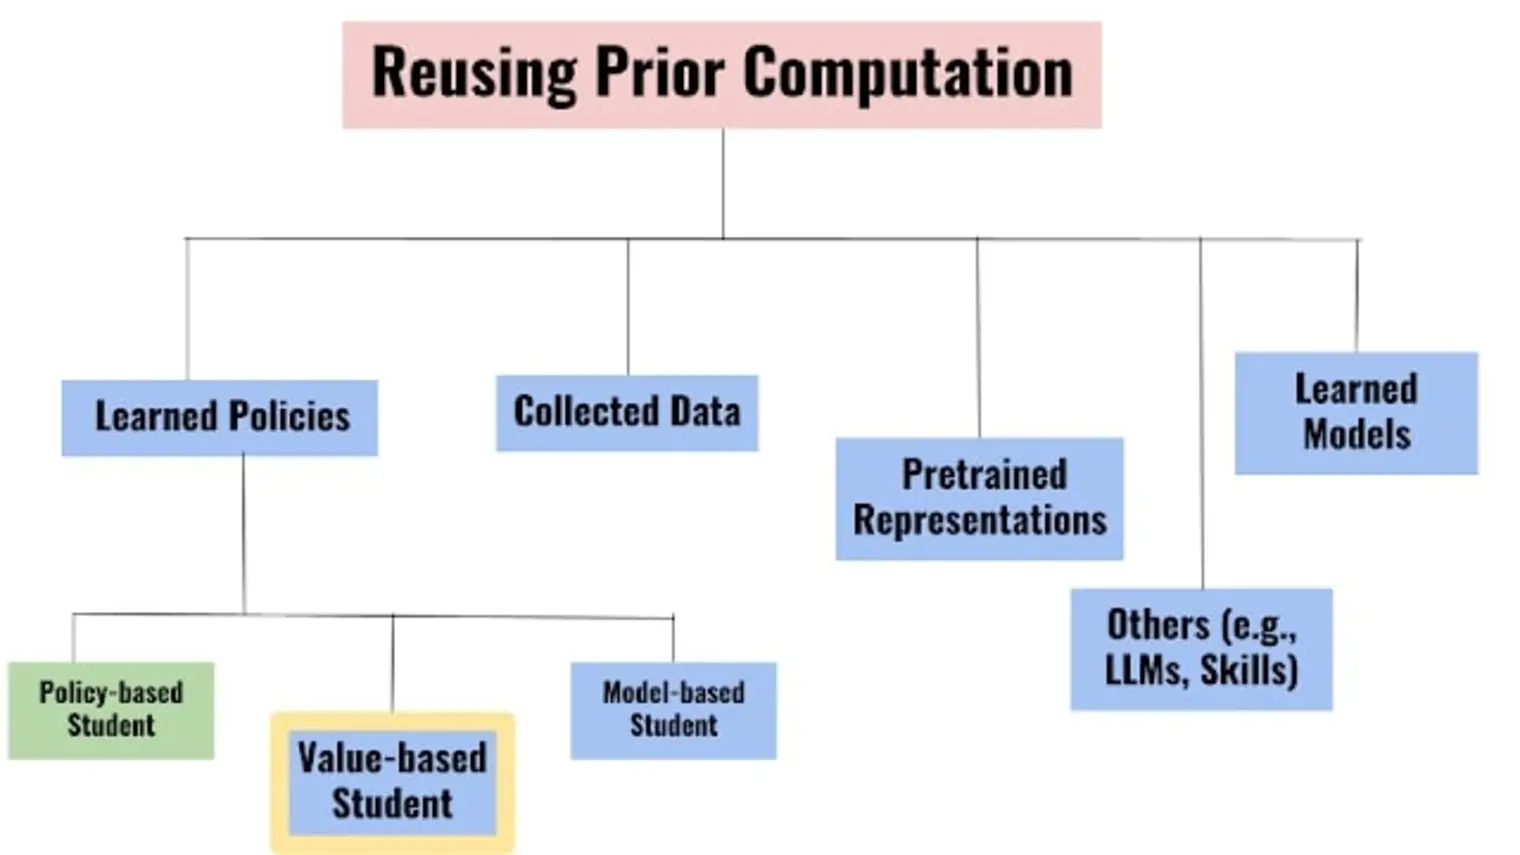
Learning tabula rasa, that is without any prior knowledge, is the prevalent workflow in reinforcement learning (RL) research. However, RL sy… (voir plus)stems, when applied to large-scale settings, rarely operate tabula rasa. Such large-scale systems undergo multiple design or algorithmic changes during their development cycle and use ad hoc approaches for incorporating these changes without re-training from scratch, which would have been prohibitively expensive. Additionally, the inefficiency of deep RL typically excludes researchers without access to industrial-scale resources from tackling computationally-demanding problems. To address these issues, we present reincarnating RL as an alternative workflow or class of problem settings, where prior computational work (e.g., learned policies) is reused or transferred between design iterations of an RL agent, or from one RL agent to another. As a step towards enabling reincarnating RL from any agent to any other agent, we focus on the specific setting of efficiently transferring an existing sub-optimal policy to a standalone value-based RL agent. We find that existing approaches fail in this setting and propose a simple algorithm to address their limitations. Equipped with this algorithm, we demonstrate reincarnating RL's gains over tabula rasa RL on Atari 2600 games, a challenging locomotion task, and the real-world problem of navigating stratospheric balloons. Overall, this work argues for an alternative approach to RL research, which we believe could significantly improve real-world RL adoption and help democratize it further. Open-sourced code and trained agents at https://agarwl.github.io/reincarnating_rl.
Reincarnating Reinforcement Learning: Reusing Prior Computation to Accelerate Progress
DR3: Value-Based Deep Reinforcement Learning Requires Explicit Regularization
Aviral Kumar
Tengyu Ma
George Tucker
Sergey Levine
Despite overparameterization, deep networks trained via supervised learning are surprisingly easy to optimize and exhibit excellent generali… (voir plus)zation. One hypothesis to explain this is that overparameterized deep networks enjoy the benefits of implicit regularization induced by stochastic gradient descent, which favors parsimonious solutions that generalize well on test inputs. It is reasonable to surmise that deep reinforcement learning (RL) methods could also benefit from this effect. In this paper, we discuss how the implicit regularization effect of SGD seen in supervised learning could in fact be harmful in the offline deep RL setting, leading to poor generalization and degenerate feature representations. Our theoretical analysis shows that when existing models of implicit regularization are applied to temporal difference learning, the resulting derived regularizer favors degenerate solutions with excessive aliasing, in stark contrast to the supervised learning case. We back up these findings empirically, showing that feature representations learned by a deep network value function trained via bootstrapping can indeed become degenerate, aliasing the representations for state-action pairs that appear on either side of the Bellman backup. To address this issue, we derive the form of this implicit regularizer and, inspired by this derivation, propose a simple and effective explicit regularizer, called DR3, that counteracts the undesirable effects of this implicit regularizer. When combined with existing offline RL methods, DR3 substantially improves performance and stability, alleviating unlearning in Atari 2600 games, D4RL domains, and robotic manipulation from images.
Behavior Predictive Representations for Generalization in Reinforcement Learning
Siddhant Agarwal
Deep reinforcement learning (RL) agents trained on a few environments, often struggle to generalize on unseen environments, even when such e… (voir plus)nvironments are semantically equivalent to training environments. Such agents learn representations that overfit the characteristics of the training environments. We posit that generalization can be improved by assigning similar representations to scenarios with similar sequences of long-term optimal behavior. To do so, we propose behavior predictive representations (BPR) that capture long-term optimal behavior. BPR trains an agent to predict latent state representations multiple steps into the future such that these representations can predict the optimal behavior at the future steps. We demonstrate that BPR provides large gains on a jumping task from pixels, a problem designed to test generalization.
Deep Reinforcement Learning at the Edge of the Statistical Precipice
Deep reinforcement learning (RL) algorithms are predominantly evaluated by comparing their relative performance on a large suite of tasks. M… (voir plus)ost published results on deep RL benchmarks compare point estimates of aggregate performance such as mean and median scores across tasks, ignoring the statistical uncertainty implied by the use of a finite number of training runs. Beginning with the Arcade Learning Environment (ALE), the shift towards computationally-demanding benchmarks has led to the practice of evaluating only a small number of runs per task, exacerbating the statistical uncertainty in point estimates. In this paper, we argue that reliable evaluation in the few run deep RL regime cannot ignore the uncertainty in results without running the risk of slowing down progress in the field. We illustrate this point using a case study on the Atari 100k benchmark, where we find substantial discrepancies between conclusions drawn from point estimates alone versus a more thorough statistical analysis. With the aim of increasing the field's confidence in reported results with a handful of runs, we advocate for reporting interval estimates of aggregate performance and propose performance profiles to account for the variability in results, as well as present more robust and efficient aggregate metrics, such as interquartile mean scores, to achieve small uncertainty in results. Using such statistical tools, we scrutinize performance evaluations of existing algorithms on other widely used RL benchmarks including the ALE, Procgen, and the DeepMind Control Suite, again revealing discrepancies in prior comparisons. Our findings call for a change in how we evaluate performance in deep RL, for which we present a more rigorous evaluation methodology, accompanied with an open-source library rliable, to prevent unreliable results from stagnating the field.
Contrastive Behavioral Similarity Embeddings for Generalization in Reinforcement Learning
Marlos C. Machado
Bellemare Marc-Emmanuel
Reinforcement learning methods trained on few environments rarely learn policies that generalize to unseen environments. To improve generali… (voir plus)zation, we incorporate the inherent sequential structure in reinforcement learning into the representation learning process. This approach is orthogonal to recent approaches, which rarely exploit this structure explicitly. Specifically, we introduce a theoretically motivated policy similarity metric (PSM) for measuring behavioral similarity between states. PSM assigns high similarity to states for which the optimal policies in those states as well as in future states are similar. We also present a contrastive representation learning procedure to embed any state similarity metric, which we instantiate with PSM to obtain policy similarity embeddings (PSEs). We demonstrate that PSEs improve generalization on diverse benchmarks, including LQR with spurious correlations, a jumping task from pixels, and Distracting DM Control Suite.
Revisiting Fundamentals of Experience Replay
William Fedus
Prajit Ramachandran
Mark Rowland
Will Dabney
Experience replay is central to off-policy algorithms in deep reinforcement learning (RL), but there remain significant gaps in our understa… (voir plus)nding. We therefore present a systematic and extensive analysis of experience replay in Q-learning methods, focusing on two fundamental properties: the replay capacity and the ratio of learning updates to experience collected (replay ratio). Our additive and ablative studies upend conventional wisdom around experience replay -- greater capacity is found to substantially increase the performance of certain algorithms, while leaving others unaffected. Counterintuitively we show that theoretically ungrounded, uncorrected n-step returns are uniquely beneficial while other techniques confer limited benefit for sifting through larger memory. Separately, by directly controlling the replay ratio we contextualize previous observations in the literature and empirically measure its importance across a variety of deep RL algorithms. Finally, we conclude by testing a set of hypotheses on the nature of these performance benefits.