
Ce programme à temps partiel offre aux scientifiques l'opportunité de tester leur intérêt pour l'entrepreneuriat. Vous avez jusqu'au 5 octobre pour postuler.

La prochaine rencontre, qui aura lieu le 10 novembre à Mila, permettra d'explorer comment pouvons-nous collectivement développer, encadrer et déployer des systèmes agentiques performants, fiables et sécuritaires en connectant chercheur·euse·s académiques, expert·e·s industriel·le·s et praticien·ne·s.

Avantage IA : productivité dans la fonction publique
Apprenez à tirer parti de l’IA générative pour soutenir et améliorer votre productivité au travail. La prochaine cohorte se déroulera en ligne les 6 et 8 octobre 2026, en anglais.
Nous utilisons des témoins pour analyser le trafic et l’utilisation de notre site web, afin de personnaliser votre expérience. Vous pouvez désactiver ces technologies à tout moment, mais cela peut restreindre certaines fonctionnalités du site. Consultez notre Politique de protection de la vie privée pour en savoir plus.
Paramètre des cookies
Vous pouvez activer et désactiver les types de cookies que vous souhaitez accepter. Cependant certains choix que vous ferez pourraient affecter les services proposés sur nos sites (ex : suggestions, annonces personnalisées, etc.).
Cookies essentiels
Ces cookies sont nécessaires au fonctionnement du site et ne peuvent être désactivés. (Toujours actif)
Cookies analyse
Acceptez-vous l'utilisation de cookies pour mesurer l'audience de nos sites ?
Lecteur Multimédia
Acceptez-vous l'utilisation de cookies pour afficher et vous permettre de regarder les contenus vidéo hébergés par nos partenaires (YouTube, etc.) ?
Safe exploration is a prerequisite for deploying reinforcement learning (RL) agents in safety-critical domains. In this paper, we approach s… (voir plus)afe exploration through the lens of epistemic uncertainty, where the actor’s sensitivity to parameter perturbations serves as a practical proxy for regions of high uncertainty. We propose Sharpness-Aware Policy Optimization (SHAPO), a sharpness-aware policy update rule that evaluates gradients at perturbed parameters, making policy updates pessimistic with respect to the actor’s epistemic uncertainty. Analytically we show that this adjustment implicitly reweighs policy gradients, amplifying the influence of rare unsafe actions while tempering contributions from already safe ones, thereby biasing learning toward conservative behavior in under-explored regions. Across several continuous-control tasks, our method consistently improves both safety and task performance over existing baselines, significantly expanding their Pareto frontiers.
2025-12-31
International Conference on Learning Representations (Accept (Poster))
Reinforcement learning algorithms typically necessitate extensive exploration of the state space to find optimal policies. However, in safet… (voir plus)y-critical applications, the risks associated with such exploration can lead to catastrophic consequences. Existing safe exploration methods attempt to mitigate this by imposing constraints, which often result in overly conservative behaviours and inefficient learning. Heavy penalties for early constraint violations can trap agents in local optima, deterring exploration of risky yet high-reward regions of the state space. To address this, we introduce a method that explicitly learns state-conditioned safety representations. By augmenting the state features with these safety representations, our approach naturally encourages safer exploration without being excessively cautious, resulting in more efficient and safer policy learning in safety-critical scenarios. Empirical evaluations across diverse environments show that our method significantly improves task performance while reducing constraint violations during training, underscoring its effectiveness in balancing exploration with safety.
2025-04-22
International Conference on Learning Representations (Accept (Poster))
While modern deep neural networks are performant perception modules, performance (accuracy) alone is insufficient, particularly for safety-c… (voir plus)ritical robotic applications such as self-driving vehicles. Robot autonomy stacks also require these otherwise blackbox models to produce reliable and calibrated measures of confidence on their predictions. Existing approaches estimate uncertainty from these neural network perception stacks by modifying network architectures, inference procedure, or loss functions. However, in general, these methods lack calibration, meaning that the predictive uncertainties do not faithfully represent the true underlying uncertainties (process noise). Our key insight is that calibration is only achieved by imposing constraints across multiple examples, such as those in a mini-batch; as opposed to existing approaches which only impose constraints per-sample, often leading to overconfident (thus miscalibrated) uncertainty estimates. By enforcing the distribution of outputs of a neural network to resemble a target distribution by minimizing an
2022-05-22
IEEE Conference on Robotics and Automation (publié)
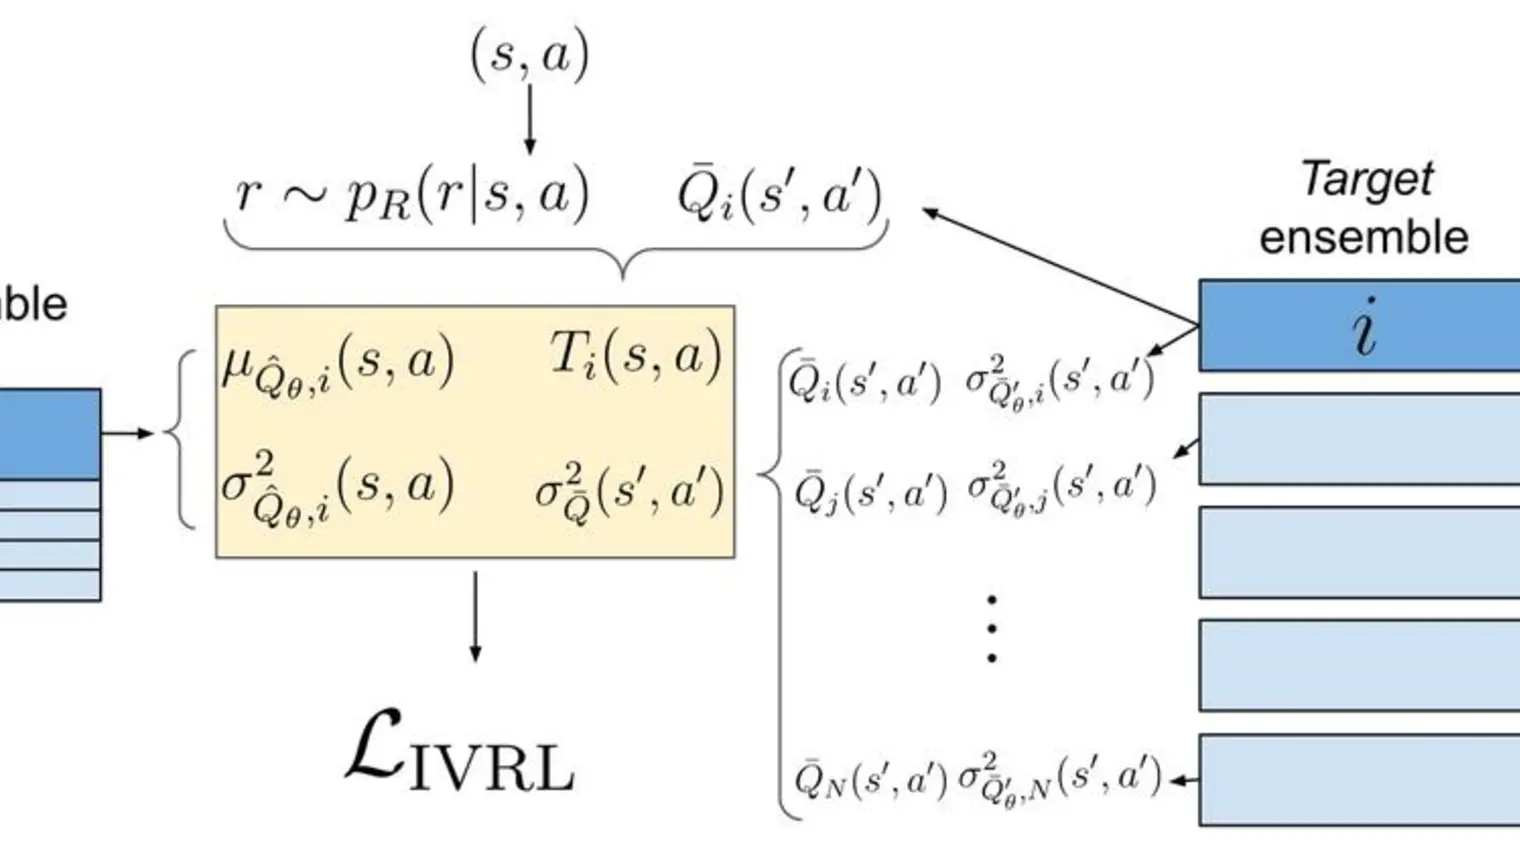
In model-free deep reinforcement learning (RL) algorithms, using noisy value estimates to supervise policy evaluation and optimization is de… (voir plus)trimental to the sample efficiency. As this noise is heteroscedastic, its effects can be mitigated using uncertainty-based weights in the optimization process. Previous methods rely on sampled ensembles, which do not capture all aspects of uncertainty. We provide a systematic analysis of the sources of uncertainty in the noisy supervision that occurs in RL, and introduce inverse-variance RL, a Bayesian framework which combines probabilistic ensembles and Batch Inverse Variance weighting. We propose a method whereby two complementary uncertainty estimation methods account for both the Q-value and the environment stochasticity to better mitigate the negative impacts of noisy supervision. Our results show significant improvement in terms of sample efficiency on discrete and continuous control tasks.
2022-04-24
International Conference on Learning Representations (Accept (Spotlight))
