La prochaine rencontre, qui aura lieu le 10 novembre à Mila, permettra d'explorer comment pouvons-nous collectivement développer, encadrer et déployer des systèmes agentiques performants, fiables et sécuritaires en connectant chercheur·euse·s académiques, expert·e·s industriel·le·s et praticien·ne·s.

Les inscriptions sont ouvertes pour notre programme de 4 mois à temps plein, à Mila, conçu spécifiquement pour les fondateurs et fondatrices de la deep tech issus de parcours d'élite en STIM. Vous avez jusqu'au 21 novembre 2026 pour appliquer!

Le processus de demandes de supervision à Mila est maintenant ouvert! Vous pouvez appliquer dès maintenant à la maitrise de recherche ou Doctorat et joindre notre grande communauté de chercheur·euse·s à Mila pour l’automne 2027. Date limite : 1er décembre 2026
Nous utilisons des témoins pour analyser le trafic et l’utilisation de notre site web, afin de personnaliser votre expérience. Vous pouvez désactiver ces technologies à tout moment, mais cela peut restreindre certaines fonctionnalités du site. Consultez notre Politique de protection de la vie privée pour en savoir plus.
Paramètre des cookies
Vous pouvez activer et désactiver les types de cookies que vous souhaitez accepter. Cependant certains choix que vous ferez pourraient affecter les services proposés sur nos sites (ex : suggestions, annonces personnalisées, etc.).
Cookies essentiels
Ces cookies sont nécessaires au fonctionnement du site et ne peuvent être désactivés. (Toujours actif)
Cookies analyse
Acceptez-vous l'utilisation de cookies pour mesurer l'audience de nos sites ?
Lecteur Multimédia
Acceptez-vous l'utilisation de cookies pour afficher et vous permettre de regarder les contenus vidéo hébergés par nos partenaires (YouTube, etc.) ?
Protein language models (pLMs) are powerful tools for protein annotation and mutation-effect prediction, but progress has largely depended o… (voir plus)n scaling model size and data, making them expensive and prone to memorization. Test-time scaling offers a complementary path, but methods developed for autoregressive LLMs do not transfer directly: masked encoders lack a generation loop, and amino acids do not verbalize in a reasoning language. Instead, we adapt recursive pretraining to masked pLMs, where a weight-tied Transformer core refines residue-aligned hidden states over an adjustable number of cycles. We instantiate this recipe as recAMPLIFY, a pLM with 155M unique parameters trained on the same 2T tokens as AMPLIFY-350M. Despite 56% fewer parameters, it improves CASP contact recovery and three out of four supervised tasks, notably raising fold accuracy by 22.5%. Because optimal depth for recAMPLIFY varies across tasks and assays, we then introduce Gated Mixture Recurrence (GMR), a framework that decodes each protein from a probability-weighted mixture of hidden states visited during recursion. GMR employs a learned residual gate at scalar, low-rank, or per-dimension resolution to control how much of each cycle's proposed update is accepted into the state. This unifies halting and gating into a single adaptive computation objective while recovering PonderNet-style halting as a special case without gates. Layered on top of recAMPLIFY, GMR further reduces expected layer depth by up to 37%, although the accuracy trade-off varies by task. Mechanistic analyses show that residual gating controls recurrence stability beyond the trained depth and that halt depth tracks biological properties.
Antibody therapeutics have transformed treatment across diverse therapeutic areas and have become central to modern medicine. While recent m… (voir plus)achine learning approaches aim to accelerate antibody discovery through structure-based design and target-affinity optimization, successful candidates must also satisfy broad developability constraints, including structural compatibility, low immunogenicity, and favorable biophysical properties, while remaining sufficiently diverse to provide sufficient coverage of design space to mitigate later-stage development failures. We introduce a preference-conditioned multi-objective generative flow network (GFN) fine-tuning pipeline for fixed-framework CDRH3 loop redesign that fine-tunes a biological sequence model against many inexpensive proxies covering backbone compatibility, sequence likelihood, immunogenicity risk, novelty, and developability liabilities. It combines up to fourteen predictive rewards in a single policy trained to sample CDRH3 loops across 623 SAbDab antibody structures, leveraging a reward reduction strategy to preserve Pareto dominance under this learned map. We also introduce a novel autoregressive span-in-filling variant of AMPLIFY-350M that serves both as a scaffold-conditioned CDRH3 generation prior and as a direct conditional likelihood scorer. We evaluated reward scores, diversity, and design quality on loops sampled on 45 held-out antibody complexes to assess structural consistency, confidence, aggregation propensity, stability, and antigen binding. Compared with the inverse-folding methods ProteinMPNN and ESM-IF, our approach produces roughly 10x more distinct acceptable candidates per design at 50% sequence identity, while holding 10% of the 14-objective Pareto front pooled across methods, trading per-sample quality for greater exploration of novel possible structures.
Abstract Accurately predicting cellular responses to drugs remains a challenge with the potential to reduce experimental screening costs and… (voir plus) accelerate drug discovery. Current computational approaches represent compounds through chemical structures, which carry little information regarding their activity within biological systems. We show that gene expression responses, measured in a reference cell line, can instead serve as transferable representations of chemical perturbations. The proposed framework, BioPert, uses biological representations with a small neural network to predict transcriptional delta responses in cell lines of different lineages. Across the Tahoe-100M and LINCS L1000 datasets, BioPert outperforms molecular fingerprints and embeddings learned from chemical structure, which provide limited improvements over random controls. BioPert’s prediction correlations reach 0.79 on Tahoe-100M, corresponding to an improvement of 0.34 over the next-best representation. On LINCS, performance varies with the experimental reproducibility of the test conditions, highlighting the impact of batch effects. Notably, BioPert considerably surpasses predictions obtained by copying the reference response, demonstrating that it captures context-dependent effects. Further analysis of a C32-cobimetinib case shows pathway-level accuracy of the predictions, including when the reference and target responses differ. These results open a new path for chemical perturbation prediction and could ultimately reduce the burden of phenotypic screening.
Protein language models (pLMs) have recently gained significant attention for their ability to uncover relationships between sequence, struc… (voir plus)ture, and function from evolutionary statistics, thereby accelerating therapeutic drug discovery. These models learn from large protein databases that are continuously updated by the biology community and whose dynamic nature motivates the application of continual learning, not only to keep up with the ever-growing data, but also as an opportunity to take advantage of the temporal meta-information that is created during this process. As a result, we introduce the Continual Pretraining of Protein Language Models (CoPeP) benchmark, a novel benchmark for evaluating continual learning approaches on pLMs. Specifically, we curate a sequence of protein datasets derived from the UniProt Knowledgebase spanning a decade and define metrics to assess pLM performance across 31 protein understanding tasks. We evaluate several methods from the continual learning literature, including replay, unlearning, and plasticity-based methods, some of which have never been applied to models and data of this scale. Our findings reveal that incorporating temporal meta-information improves perplexity by up to 7% even when compared to training on data from all tasks jointly. Moreover, even at scale, several continual learning methods outperform naive continual pretraining. The CoPeP benchmark offers an exciting opportunity to study these methods at scale in an impactful real-world application.
2026-08-24
Work-In-Progress Track @ Conference on Lifelong Learning Agents (poster)
Metagenomic sequencing has uncovered billions of proteins from uncultured microorganisms, vastly expanding the known protein space. Yet most… (voir plus) remain functionally inaccessible because existing annotation methods depend on close homologs or accurate structure predictions. Here, we show that protein language models (pLMs) can unlock this diversity only when their training data are appropriately curated. We introduce Residue Embedding Diversity (RED), a metric for protein quality assessment orders of magnitude cheaper than likelihood, and a calibration task that measures model alignment with natural evolutionary distributions. We discover a fundamental trade-off between evolutionary calibration and structural modeling, establishing training data composition as a primary determinant of pLM behavior. Finally, we successfully retrieve diverse enzyme candidates from billions of metagenomic sequences and validate their expression in vivo .
Protein language models have been increasingly successful on tasks ranging from fitness prediction to functional design, yet what biological… (voir plus) knowledge they acquire and where it is encoded within their internal representations remain underexplored. Through a high-resolution layer-by-layer interpretability analysis of 8 models from the ESM2 and AMPLIFY families on 22 concepts from human proteome annotations, we found that these models encode concepts of increasing levels of complexity along their depth: basic physicochemical properties and linear motifs are best captured by early-layer embeddings, secondary structure from subsequent layers, and domain-level semantics from middle layers. Principal component projections of these embeddings showed that they separate biologically meaningful protein groupings, and molecular-biology-inspired interventions demonstrated that pLM embeddings can discriminate phosphomimic-active from inactive mutants. Perhaps surprisingly, we observed that pretraining data and compute had a greater impact on the linear emergence of biological concepts than scaling up parameters. By revealing where biological knowledge is captured in pLMs and which choices shape its emergence, our work offers insights to develop more robust, biologically grounded protein language models.
Abstract Motivation Antimicrobial resistance (AMR) has been identified as a top global public health threat. Accurate AMR phenotype predicti… (voir plus)on from whole-genome sequencing data is an essential tool for accelerating clinical decision-making and mitigating resistance spread. Although many previous works have explored the use of tree-based machine learning (ML) models to predict resistance, the field lacks a systematic evaluation of the training pipeline across a variety of pathogenic species and antibiotics. Results Using nine clinically relevant species–antibiotic combinations from the NCBI antimicrobial susceptibility testing database, we present a detailed analysis of the ML pipeline and identify key factors affecting model performance and evaluation. We begin by relabelling all isolates using current CLSI minimum inhibitory concentration breakpoints to resolve inconsistencies and increase available data, resulting in up to a 19% label swap and 56% data enlargement per species– antibiotic combination. We identify several key training parameters including k -mer length, which can increase classification F1 scores by over 20 points compared to commonly used k -values, feature matrix truncation, which can induce polynomial time reductions with limited performance reduction, and ML model class. By comparing 5-fold cross-validation with evaluation on an unseen clinical dataset, we show that random cross-validation splits—often criticized as overly optimistic—can act as a strong proxy for downstream clinical performance, yielding closer F1 scores than phylogeny-aware splits in all cases. We finally present an interpretability study which shows that over 95% of k -mers used by our models are associated with identifiable genomic features. Our results highlight the importance of feature design, evaluation protocol, and biological analysis in genomic AMR prediction, and support tree-based models as a robust and interpretable method. Availability and implementation Python code is made freely available: https://github.com/chandar-lab/amr-pred
Public protein sequence databases contain samples from the fitness landscape explored by nature. Protein language models (pLMs) pre-trained … (voir plus)on these sequences aim to capture this landscape for tasks like property prediction and protein design. Following the same trend as in natural language processing, pLMs have continuously been scaled up. However, the premise that scale leads to better performance assumes that source databases provide an accurate representation of the underlying fitness landscape, which is likely false. By developing an efficient codebase, designing a modern architecture, and addressing data quality concerns such as sample bias, we introduce AMPLIFY, a best-in-class pLM that is orders of magnitude less expensive to train and deploy than previous models. Furthermore, to support the scientific community and democratize the training of pLMs, we have open-sourced AMPLIFY’s pre-training codebase, data, and model checkpoints.
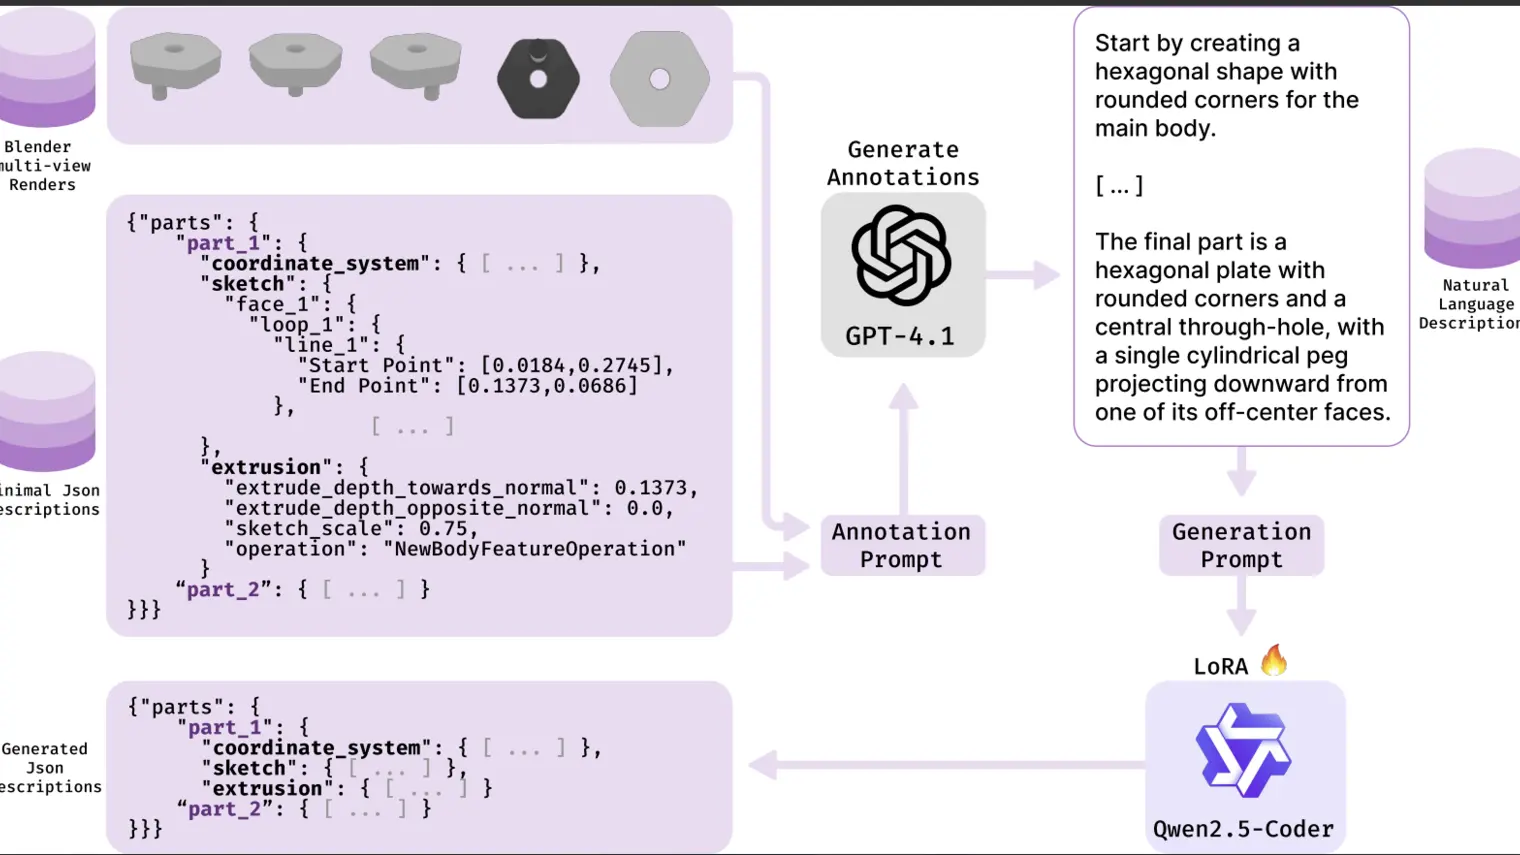
Computer-aided design (CAD) is the digital construction of 2D and 3D objects, and is central to a wide range of engineering and manufacturin… (voir plus)g applications like automobile and aviation. Despite its importance, CAD modeling remains largely a time-intensive, manual task. Recent works have attempted to automate this process with small transformer-based models and handcrafted CAD sequence representations. However, there has been little effort to leverage the potential of large language models (LLMs) for sequential CAD design. In this work, we introduce a new large-scale dataset of more than 170k CAD models annotated with high-quality, human-like descriptions generated with our pipeline based on GPT-4.1. Using this dataset, we fine-tune powerful code-LLMs to generate CAD sequences represented in a JSON-based format from natural language descriptions, demonstrating the viability and effectiveness of this approach for text-conditioned CAD generation. Because simple metrics often fail to reflect the quality of generated objects, we introduce geometric and topological metrics based on sphericity, mean curvature, and Euler characteristic to provide richer structural insights. Our experiments and ablation studies on both synthetic and human-annotated data demonstrate that CADmium is able to automate CAD design, drastically speeding up the design of new objects. The dataset, code, and fine-tuned models are available online.
Augmenting large language models (LLMs) with external context significantly improves their performance in natural language processing (NLP) … (voir plus)tasks. However, LLMs struggle to answer queries reliably when the provided context lacks information, often resorting to ungrounded speculation or internal knowledge. Groundedness - generating responses strictly supported by the context - is essential for ensuring factual consistency and trustworthiness. This study focuses on detecting whether a given query is grounded in a document provided in context before the costly answer generation by LLMs. Such a detection mechanism can significantly reduce both inference time and resource consumption. We show that lightweight, task specific encoder models such as RoBERTa and NomicBERT, fine-tuned on curated datasets, can achieve accuracy comparable to state-of-the-art LLMs, such as Llama3 8B and GPT4o, in groundedness detection while reducing inference latency by orders of magnitude. The code is available at : https://github.com/chandarlab/Hallucinate-less
