


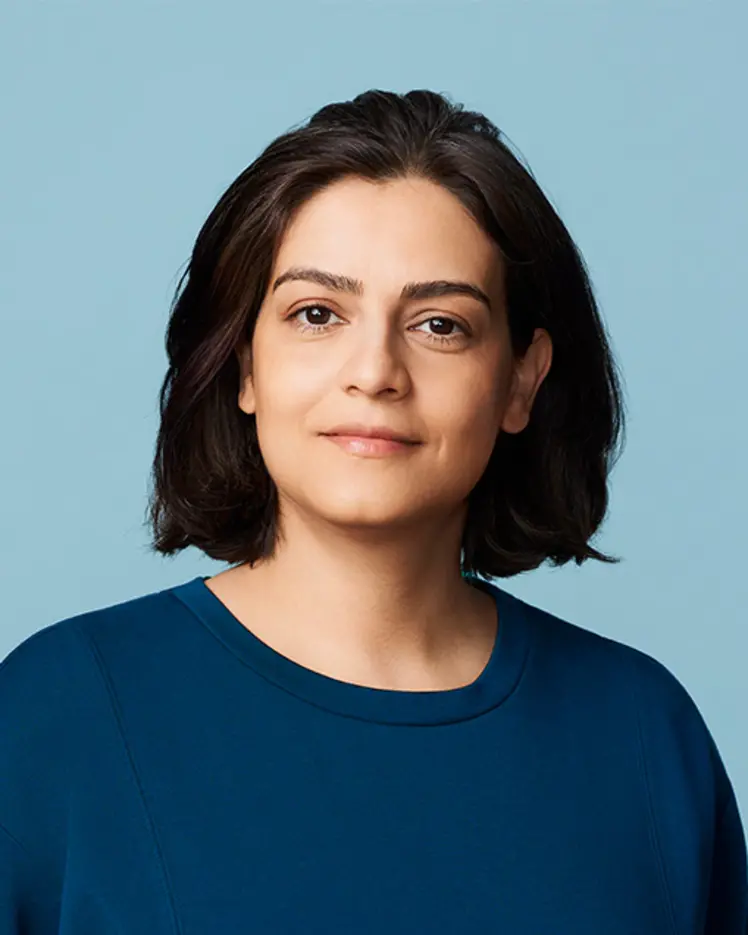
Portrait of Reihaneh Rabbany

Reihaneh Rabbany

Core Academic Member
Canada CIFAR AI Chair
Assistant Professor, McGill University
Research Topics
Data Mining
Graph Neural Networks
Learning on Graphs
Natural Language Processing
Representation Learning

Biography

Reihaneh Rabbany is an assistant professor at the School of Computer Science, McGill University, and a core academic member of Mila – Quebec Artificial Intelligence Institute. She is also a Canada CIFAR AI Chair and on the faculty of McGill’s Centre for the Study of Democratic Citizenship.

Before joining McGill, Rabbany was a postdoctoral fellow at the School of Computer Science, Carnegie Mellon University. She completed her PhD in the Department of Computing Science at the University of Alberta.

Rabbany heads McGill’s Complex Data Lab, where she conducts research at the intersection of network science, data mining and machine learning, with a focus on analyzing real-world interconnected data and social good applications.
Current Students

PhD - Université de Montréal
Principal supervisor :
Collaborating researcher - McGill University University
Master's Research - McGill University
Independent visiting researcher - Mila
Research Intern - Université de Montréal
Principal supervisor :
PhD - McGill University
Collaborating researcher - McGill University
PhD - Université de Montréal
Principal supervisor :
Research Intern - McGill University
Independent visiting researcher - Brno University of Technology
Collaborating researcher - McGill University University
Collaborating researcher - McGill University
Co-supervisor :
PhD - McGill University
Principal supervisor :
Research Intern - McGill University University
Postdoctorate - McGill University
Principal supervisor :
Postdoctorate - Université de Montréal
Principal supervisor :
PhD - Université de Montréal
Principal supervisor :
Master's Research - McGill University University
Independent visiting researcher - McGill University
Master's Research - McGill University
Master's Research - McGill University University
Master's Research - McGill University
Collaborating researcher - Université de Montréal
Principal supervisor :
Master's Research - McGill University
Undergraduate - McGill University University
Co-supervisor :
Master's Research - McGill University
Master's Research - Université de Montréal
Principal supervisor :

Publications

MiNT: Multi-Network Training for Transfer Learning on Temporal Graphs
Tran Gia Bao Ngo
Kiarash Shamsi
Poupak Azad
Baris Coskunuzer
Cuneyt Gurcan Akcora
Party Prediction for Twitter
Sacha Lévy
Gabrielle Desrosiers-Brisebois
Cécile Amadoro
Andre Blais
A large number of studies on social media compare the behaviour of users from different political parties. As a basic step, they employ a pr… (see more)edictive model for inferring their political affiliation. The accuracy of this model can change the conclusions of a downstream analysis significantly, yet the choice between different models seems to be made arbitrarily. In this paper, we provide a comprehensive survey and an empirical comparison of the current party prediction practices and propose several new approaches which are competitive with or outperform state-of-the-art methods, yet require less computational resources. Party prediction models rely on the content generated by the users (e.g., tweet texts), the relations they have (e.g., who they follow), or their activities and interactions (e.g., which tweets they like). We examine all of these and compare their signal strength for the party prediction task. This paper lets the practitioner select from a wide range of data types that all give strong performance. Finally, we conduct extensive experiments on different aspects of these methods, such as data collection speed and transfer capabilities, which can provide further insights for both applied and methodological research.
Static graph approximations of dynamic contact networks for epidemic forecasting
Epidemic modeling is essential in understanding the spread of infectious diseases like COVID-19 and devising effective intervention strategi… (see more)es to control them. Recently, network-based disease models have integrated traditional compartment-based modeling with real-world contact graphs and shown promising results. However, in an ongoing epidemic, future contact network patterns are not observed yet. To address this, we use aggregated static networks to approximate future contacts for disease modeling. The standard method in the literature concatenates all edges from a dynamic graph into one collapsed graph, called the full static graph. However, the full static graph often leads to severe overestimation of key epidemic characteristics. Therefore, we propose two novel static network approximation methods, DegMST and EdgeMST, designed to preserve the sparsity of real world contact network while remaining connected. DegMST and EdgeMST use the frequency of temporal edges and the node degrees respectively to preserve sparsity. Our analysis show that our models more closely resemble the network characteristics of the dynamic graph compared to the full static ones. Moreover, our analysis on seven real-world contact networks suggests EdgeMST yield more accurate estimations of disease dynamics for epidemic forecasting when compared to the standard full static method.
Towards Foundational Models for Molecular Learning on Large-Scale Multi-Task Datasets
Joao Alex Cunha
Zhiyi Li
Samuel Maddrell-Mander
Callum McLean
Jama Hussein Mohamud
Michael Craig
Cristian Gabellini
Kerstin Klaser
Josef Dean
Maciej Sypetkowski
Hadrien Mary
Therence Bois
Andrew Fitzgibbon
Błażej Banaszewski
Chad Martin
Dominic Masters
Recently, pre-trained foundation models have shown significant advancements in multiple fields. However, the lack of datasets with labeled f… (see more)eatures and codebases has hindered the development of a supervised foundation model for molecular tasks. Here, we have carefully curated seven datasets specifically tailored for node- and graph-level prediction tasks to facilitate supervised learning on molecules. Moreover, to support the development of multi-task learning on our proposed datasets, we created the Graphium graph machine learning library. Our dataset collection encompasses two distinct categories. Firstly, the TOYMIX category modifies three small existing datasets with additional data for multi-task learning. Secondly, the LARGEMIX category includes four large-scale datasets with 344M graph-level data points and 409M node-level data points from ∼5M unique molecules. Finally, the ultra-large dataset contains 2,210M graph-level data points and 2,031M node-level data points coming from 86M molecules. Hence our datasets represent an order of magnitude increase in data volume compared to other 2D-GNN datasets. In addition, recognizing that molecule-related tasks often span multiple levels, we have designed our library to explicitly support multi-tasking, offering a diverse range of multi-level representations, i.e., representations at the graph, node, edge, and node-pair level. We equipped the library with an extensive collection of models and features to cover different levels of molecule analysis. By combining our curated datasets with this versatile library, we aim to accelerate the development of molecule foundation models. Datasets and code are available at https://github.com/datamol-io/graphium.
T-NET: Weakly Supervised Graph Learning for Combatting Human Trafficking
Javin Liu
Catalina Vajiac
Andreas Olligschlaeger
Duen Horng Chau
Mirela Cazzolato
Cara Jones
Christos Faloutsos
Human trafficking (HT) for forced sexual exploitation, often described as modern-day slavery, is a pervasive problem that affects millions o… (see more)f people worldwide. Perpetrators of this crime post advertisements (ads) on behalf of their victims on adult service websites (ASW). These websites typically contain hundreds of thousands of ads including those posted by independent escorts, massage parlor agencies and spammers (fake ads). Detecting suspicious activity in these ads is difficult and developing data-driven methods is challenging due to the hard-to-label, complex and sensitive nature of the data. In this paper, we propose T-Net, which unlike previous solutions, formulates this problem as weakly supervised classification. Since it takes several months to years to investigate a case and obtain a single definitive label, we design domain-specific signals or indicators that provide weak labels. T-Net also looks into connections between ads and models the problem as a graph learning task instead of classifying ads independently. We show that T-Net outperforms all baselines on a real-world dataset of ads by 7% average weighted F1 score. Given that this data contains personally identifiable information, we also present a realistic data generator and provide the first publicly available dataset in this domain which may be leveraged by the wider research community.
Temporal Graph Analysis with TGX
Real-world networks, with their evolving relations, are best captured as temporal graphs. However, existing software libraries are largely d… (see more)esigned for static graphs where the dynamic nature of temporal graphs is ignored. Bridging this gap, we introduce TGX, a Python package specially designed for analysis of temporal networks that encompasses an automated pipeline for data loading, data processing, and analysis of evolving graphs. TGX provides access to eleven built-in datasets and eight external Temporal Graph Benchmark (TGB) datasets as well as any novel datasets in the .csv format. Beyond data loading, TGX facilitates data processing functionalities such as discretization of temporal graphs and node subsampling to accelerate working with larger datasets. For comprehensive investigation, TGX offers network analysis by providing a diverse set of measures, including average node degree and the evolving number of nodes and edges per timestamp. Additionally, the package consolidates meaningful visualization plots indicating the evolution of temporal patterns, such as Temporal Edge Appearance (TEA) and Temporal Edge Trafficc (TET) plots. The TGX package is a robust tool for examining the features of temporal graphs and can be used in various areas like studying social networks, citation networks, and tracking user interactions. We plan to continuously support and update TGX based on community feedback. TGX is publicly available on: https://github.com/ComplexData-MILA/TGX.
Combining Confidence Elicitation and Sample-based Methods for Uncertainty Quantification in Misinformation Mitigation
Comparing GPT-4 and Open-Source Language Models in Misinformation Mitigation
Recent large language models (LLMs) have been shown to be effective for misinformation detection. However, the choice of LLMs for experiment… (see more)s varies widely, leading to uncertain conclusions. In particular, GPT-4 is known to be strong in this domain, but it is closed source, potentially expensive, and can show instability between different versions. Meanwhile, alternative LLMs have given mixed results. In this work, we show that Zephyr-7b presents a consistently viable alternative, overcoming key limitations of commonly used approaches like Llama-2 and GPT-3.5. This provides the research community with a solid open-source option and shows open-source models are gradually catching up on this task. We then highlight how GPT-3.5 exhibits unstable performance, such that this very widely used model could provide misleading results in misinformation detection. Finally, we validate new tools including approaches to structured output and the latest version of GPT-4 (Turbo), showing they do not compromise performance, thus unlocking them for future research and potentially enabling more complex pipelines for misinformation mitigation.
GPS-SSL: Guided Positive Sampling to Inject Prior Into Self-Supervised Learning
Randall Balestriero
Arantxa Casanova
Adriana Romero
We propose Guided Positive Sampling Self-Supervised Learning (GPS-SSL), a general method to inject a priori knowledge into Self-Supervised L… (see more)earning (SSL) positive samples selection. Current SSL methods leverage Data-Augmentations (DA) for generating positive samples and incorporate prior knowledge - an incorrect, or too weak DA will drastically reduce the quality of the learned representation. GPS-SSL proposes instead to design a metric space where Euclidean distances become a meaningful proxy for semantic relationship. In that space, it is now possible to generate positive samples from nearest neighbor sampling. Any prior knowledge can now be embedded into that metric space independently from the employed DA. From its simplicity, GPS-SSL is applicable to any SSL method, e.g. SimCLR or BYOL. A key benefit of GPS-SSL is in reducing the pressure in tailoring strong DAs. For example GPS-SSL reaches 85.58% on Cifar10 with weak DA while the baseline only reaches 37.51%. We therefore move a step forward towards the goal of making SSL less reliant on DA. We also show that even when using strong DAs, GPS-SSL outperforms the baselines on under-studied domains. We evaluate GPS-SSL along with multiple baseline SSL methods on numerous downstream datasets from different domains when the models use strong or minimal data augmentations. We hope that GPS-SSL will open new avenues in studying how to inject a priori knowledge into SSL in a principled manner.
Uncertainty Resolution in Misinformation Detection
An Evaluation of Language Models for Hyperpartisan Ideology Detection in Persian Twitter
Large Language Models (LLMs) have shown significant promise in various tasks, including identifying the political beliefs of English-speakin… (see more)g social media users from their posts. However, assessing LLMs for this task in non-English languages remains unexplored. In this work, we ask to what extent LLMs can predict the political ideologies of users in Persian social media. To answer this question, we first acknowledge that political parties are not well-defined among Persian users, and therefore, we simplify the task to a much simpler task of hyperpartisan ideology detection. We create a new benchmark and show the potential and limitations of both open-source and commercial LLMs in classifying the hyper-partisan ideologies of users. We compare these models with smaller fine-tuned models, both on the Persian language (ParsBERT) and translated data (RoBERTa), showing that they considerably outperform generative LLMs in this task. We further demonstrate that the performance of the generative LLMs degrades when classifying users based on their tweets instead of their bios and even when tweets are added as additional information, whereas the smaller fine-tuned models are robust and achieve similar performance for all classes. This study is a first step toward political ideology detection in Persian Twitter, with implications for future research to understand the dynamics of ideologies in Persian social media.
Quantifying learning-style adaptation in effectiveness of LLM teaching
Ruben Weijers
Gabrielle Fidelis de Castilho
This preliminary study aims to investigate whether AI, when prompted based on individual learning styles, can effectively improve comprehens… (see more)ion and learning experiences in educational settings. It involves tailoring LLMs baseline prompts and comparing the results of a control group receiving standard content and an experimental group receiving learning style-tailored content. Preliminary results suggest that GPT-4 can generate responses aligned with various learning styles, indicating the potential for enhanced engagement and comprehension. However, these results also reveal challenges, including the model’s tendency for sycophantic behavior and variability in responses. Our findings suggest that a more sophisticated prompt engineering approach is required for integrating AI into education (AIEd) to improve educational outcomes.