


Portrait of Ioannis Mitliagkas

Ioannis Mitliagkas

Core Academic Member
Canada CIFAR AI Chair
Associate Professor, Université de Montréal
Research Scientist, Google DeepMind
Research Topics
Deep Learning
Distributed Systems
Dynamical Systems
Generative Models
Machine Learning Theory
Optimization
Representation Learning

Biography

Ioannis Mitliagkas (Γιάννης Μητλιάγκας) is an associate professor in the Department of Computer Science and Operations Research (DIRO) at Université de Montréal, as well as a Core Academic member of Mila – Quebec Artificial Intelligence Institute and a Canada CIFAR AI Chair. He holds a part-time position as a staff research scientist at Google DeepMind Montréal.

Previously, he was a postdoctoral scholar in the Departments of statistics and computer science at Stanford University. He obtained his PhD from the Department of Electrical and Computer Engineering at the University of Texas at Austin.

His research includes topics in machine learning, with emphasis on optimization, deep learning theory, statistical learning. His recent work includes methods for efficient and adaptive optimization, studying the interaction between optimization and the dynamics of large-scale learning systems and the dynamics of games.
Current Students

PhD - Université de Montréal
Principal supervisor :
Professional Master's - Université de Montréal
PhD - Université de Montréal
Collaborating researcher - Université de Montréal
Principal supervisor :

Publications

Towards Out-of-Distribution Adversarial Robustness
Adversarial robustness continues to be a major challenge for deep learning. A core issue is that robustness to one type of attack often fail… (see more)s to transfer to other attacks. While prior work establishes a theoretical trade-off in robustness against different
Empirical Study on Optimizer Selection for Out-of-Distribution Generalization
Shiro Takagi
Tetsuya Motokawa
Rio Yokota
Kohta Ishikawa
Ikuro Sato
Modern deep learning systems do not generalize well when the test data distribution is slightly different to the training data distribution.… (see more) While much promising work has been accomplished to address this fragility, a systematic study of the role of optimizers and their out-of-distribution generalization performance has not been undertaken. In this study, we examine the performance of popular first-order optimizers for different classes of distributional shift under empirical risk minimization and invariant risk minimization. We address this question for image and text classification using DomainBed, WILDS, and Backgrounds Challenge as testbeds for studying different types of shifts---namely correlation and diversity shift. We search over a wide range of hyperparameters and examine classification accuracy (in-distribution and out-of-distribution) for over 20,000 models. We arrive at the following findings, which we expect to be helpful for practitioners: i) adaptive optimizers (e.g., Adam) perform worse than non-adaptive optimizers (e.g., SGD, momentum SGD) on out-of-distribution performance. In particular, even though there is no significant difference in in-distribution performance, we show a measurable difference in out-of-distribution performance. ii) in-distribution performance and out-of-distribution performance exhibit three types of behavior depending on the dataset---linear returns, increasing returns, and diminishing returns. For example, in the training of natural language data using Adam, fine-tuning the performance of in-distribution performance does not significantly contribute to the out-of-distribution generalization performance.
Neural Networks Efficiently Learn Low-Dimensional Representations with SGD
Alireza Mousavi-Hosseini
Sejun Park
Murat A. Erdogdu
We study the problem of training a two-layer neural network (NN) of arbitrary width using stochastic gradient descent (SGD) where the input …
A Unified Approach to Reinforcement Learning, Quantal Response Equilibria, and Two-Player Zero-Sum Games
Samuel Sokota
J. Zico Kolter
Marc Lanctot
Noam Brown
Christian Kroer
This work studies an algorithm, which we call magnetic mirror descent, that is inspired by mirror descent and the non-Euclidean proximal gra… (see more)dient algorithm. Our contribution is demonstrating the virtues of magnetic mirror descent as both an equilibrium solver and as an approach to reinforcement learning in two-player zero-sum games. These virtues include: 1) Being the first quantal response equilibria solver to achieve linear convergence for extensive-form games with first order feedback; 2) Being the first standard reinforcement learning algorithm to achieve empirically competitive results with CFR in tabular settings; 3) Achieving favorable performance in 3x3 Dark Hex and Phantom Tic-Tac-Toe as a self-play deep reinforcement learning algorithm.
Performative Prediction with Neural Networks
Performative prediction is a framework for learning models that influence the data they intend to predict. We focus on finding classifiers t… (see more)hat are performatively stable, i.e. optimal for the data distribution they induce. Standard convergence results for finding a performatively stable classifier with the method of repeated risk minimization assume that the data distribution is Lipschitz continuous to the model's parameters. Under this assumption, the loss must be strongly convex and smooth in these parameters; otherwise, the method will diverge for some problems. In this work, we instead assume that the data distribution is Lipschitz continuous with respect to the model's predictions, a more natural assumption for performative systems. As a result, we are able to significantly relax the assumptions on the loss function. In particular, we do not need to assume convexity with respect to the model's parameters. As an illustration, we introduce a resampling procedure that models realistic distribution shifts and show that it satisfies our assumptions. We support our theory by showing that one can learn performatively stable classifiers with neural networks making predictions about real data that shift according to our proposed procedure.
Gradient Descent Is Optimal Under Lower Restricted Secant Inequality And Upper Error Bound
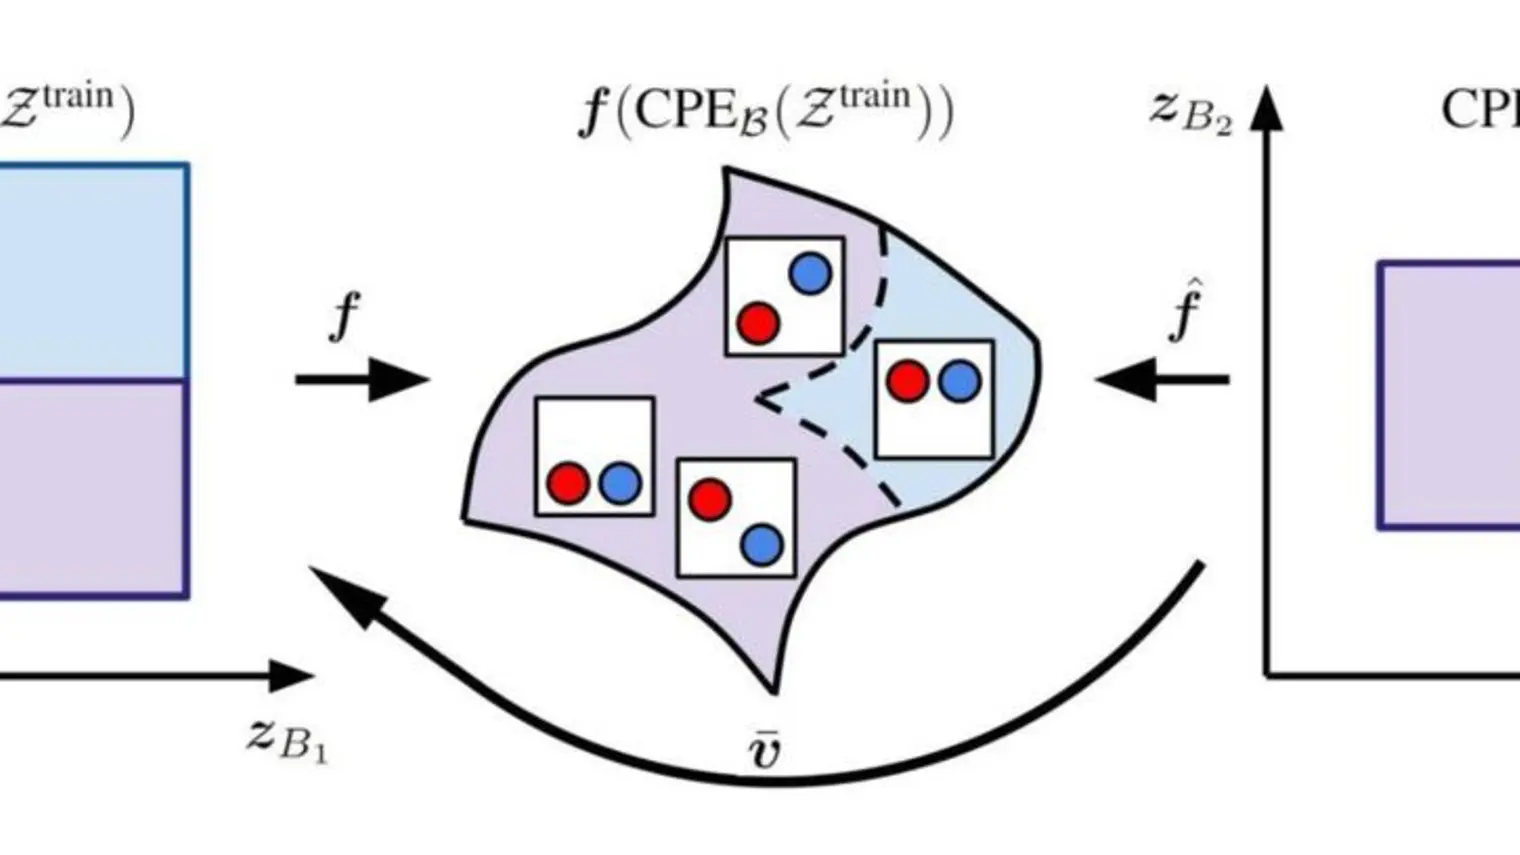
The study of first-order optimization is sensitive to the assumptions made on the objective functions. These assumptions induce complexity c… (see more)lasses which play a key role in worst-case analysis, including the fundamental concept of algorithm optimality. Recent work argues that strong convexity and smoothness, popular assumptions in literature, lead to a pathological definition of the condition number (Guille-Escuret et al., 2021). Motivated by this result, we focus on the class of functions satisfying a lower restricted secant inequality and an upper error bound. On top of being robust to the aforementioned pathological behavior and including some non-convex functions, this pair of conditions displays interesting geometrical properties. In particular, the necessary and sufficient conditions to interpolate a set of points and their gradients within the class can be separated into simple conditions on each sampled gradient. This allows the performance estimation problem (PEP, Drori and Teboulle (2012)) to be solved analytically, leading to a lower bound on the convergence rate that proves gradient descent to be exactly optimal on this class of functions among all first-order algorithms.
Towards efficient representation identification in supervised learning
Humans have a remarkable ability to disentangle complex sensory inputs (e.g., image, text) into simple factors of variation (e.g., shape, co… (see more)lor) without much supervision. This ability has inspired many works that attempt to solve the following question: how do we invert the data generation process to extract those factors with minimal or no supervision? Several works in the literature on non-linear independent component analysis have established this negative result; without some knowledge of the data generation process or appropriate inductive biases, it is impossible to perform this inversion. In recent years, a lot of progress has been made on disentanglement under structural assumptions, e.g., when we have access to auxiliary information that makes the factors of variation conditionally independent. However, existing work requires a lot of auxiliary information, e.g., in supervised classification, it prescribes that the number of label classes should be at least equal to the total dimension of all factors of variation. In this work, we depart from these assumptions and ask: a) How can we get disentanglement when the auxiliary information does not provide conditional independence over the factors of variation? b) Can we reduce the amount of auxiliary information required for disentanglement? For a class of models where auxiliary information does not ensure conditional independence, we show theoretically and experimentally that disentanglement (to a large extent) is possible even when the auxiliary information dimension is much less than the dimension of the true latent representation.
Invariance Principle Meets Information Bottleneck for Out-of-Distribution Generalization
The invariance principle from causality is at the heart of notable approaches such as invariant risk minimization (IRM) that seek to address… (see more) out-of-distribution (OOD) generalization failures. Despite the promising theory, invariance principle-based approaches fail in common classification tasks, where invariant (causal) features capture all the information about the label. Are these failures due to the methods failing to capture the invariance? Or is the invariance principle itself insufficient? To answer these questions, we revisit the fundamental assumptions in linear regression tasks, where invariance-based approaches were shown to provably generalize OOD. In contrast to the linear regression tasks, we show that for linear classification tasks we need much stronger restrictions on the distribution shifts, or otherwise OOD generalization is impossible. Furthermore, even with appropriate restrictions on distribution shifts in place, we show that the invariance principle alone is insufficient. We prove that a form of the information bottleneck constraint along with invariance helps address key failures when invariant features capture all the information about the label and also retains the existing success when they do not. We propose an approach that incorporates both of these principles and demonstrate its effectiveness in several experiments.
Stochastic Gradient Descent-Ascent and Consensus Optimization for Smooth Games: Convergence Analysis under Expected Co-coercivity
Two of the most prominent algorithms for solving unconstrained smooth games are the classical stochastic gradient descent-ascent (SGDA) and … (see more)the recently introduced stochastic consensus optimization (SCO) [Mescheder et al., 2017]. SGDA is known to converge to a stationary point for specific classes of games, but current convergence analyses require a bounded variance assumption. SCO is used successfully for solving large-scale adversarial problems, but its convergence guarantees are limited to its deterministic variant. In this work, we introduce the expected co-coercivity condition, explain its benefits, and provide the first last-iterate convergence guarantees of SGDA and SCO under this condition for solving a class of stochastic variational inequality problems that are potentially non-monotone. We prove linear convergence of both methods to a neighborhood of the solution when they use constant step-size, and we propose insightful stepsize-switching rules to guarantee convergence to the exact solution. In addition, our convergence guarantees hold under the arbitrary sampling paradigm, and as such, we give insights into the complexity of minibatching.
Convergence Analysis and Implicit Regularization of Feedback Alignment for Deep Linear Networks
We theoretically analyze the Feedback Alignment (FA) algorithm, an efficient alternative to backpropagation for training neural networks. We… (see more) provide convergence guarantees with rates for deep linear networks for both continuous and discrete dynamics. Additionally, we study incremental learning phenomena for shallow linear networks. Interestingly, certain specific initializations imply that negligible components are learned before the principal ones, thus potentially negatively affecting the effectiveness of such a learning algorithm; a phenomenon we classify as implicit anti-regularization. We also provide initialization schemes where the components of the problem are approximately learned by decreasing order of importance, thus providing a form of implicit regularization.
Gotta Go Fast When Generating Data with Score-Based Models
Score-based (denoising diffusion) generative models have recently gained a lot of success in generating realistic and diverse data. These ap… (see more)proaches define a forward diffusion process for transforming data to noise and generate data by reversing it (thereby going from noise to data). Unfortunately, current score-based models generate data very slowly due to the sheer number of score network evaluations required by numerical SDE solvers. In this work, we aim to accelerate this process by devising a more efficient SDE solver. Existing approaches rely on the Euler-Maruyama (EM) solver, which uses a fixed step size. We found that naively replacing it with other SDE solvers fares poorly - they either result in low-quality samples or become slower than EM. To get around this issue, we carefully devise an SDE solver with adaptive step sizes tailored to score-based generative models piece by piece. Our solver requires only two score function evaluations, rarely rejects samples, and leads to high-quality samples. Our approach generates data 2 to 10 times faster than EM while achieving better or equal sample quality. For high-resolution images, our method leads to significantly higher quality samples than all other methods tested. Our SDE solver has the benefit of requiring no step size tuning.
A Study of Condition Numbers for First-Order Optimization
The study of first-order optimization algorithms (FOA) typically starts with assumptions on the objective functions, most commonly smoothnes… (see more)s and strong convexity. These metrics are used to tune the hyperparameters of FOA. We introduce a class of perturbations quantified via a new norm, called *-norm. We show that adding a small perturbation to the objective function has an equivalently small impact on the behavior of any FOA, which suggests that it should have a minor impact on the tuning of the algorithm. However, we show that smoothness and strong convexity can be heavily impacted by arbitrarily small perturbations, leading to excessively conservative tunings and convergence issues. In view of these observations, we propose a notion of continuity of the metrics, which is essential for a robust tuning strategy. Since smoothness and strong convexity are not continuous, we propose a comprehensive study of existing alternative metrics which we prove to be continuous. We describe their mutual relations and provide their guaranteed convergence rates for the Gradient Descent algorithm accordingly tuned. Finally we discuss how our work impacts the theoretical understanding of FOA and their performances.