


Portrait of Ioannis Mitliagkas

Ioannis Mitliagkas

Core Academic Member
Canada CIFAR AI Chair
Associate Professor, Université de Montréal
Research Scientist, Google DeepMind
Research Topics
Deep Learning
Distributed Systems
Dynamical Systems
Generative Models
Machine Learning Theory
Optimization
Representation Learning

Biography

Ioannis Mitliagkas (Γιάννης Μητλιάγκας) is an associate professor in the Department of Computer Science and Operations Research (DIRO) at Université de Montréal, as well as a Core Academic member of Mila – Quebec Artificial Intelligence Institute and a Canada CIFAR AI Chair. He holds a part-time position as a staff research scientist at Google DeepMind Montréal.

Previously, he was a postdoctoral scholar in the Departments of statistics and computer science at Stanford University. He obtained his PhD from the Department of Electrical and Computer Engineering at the University of Texas at Austin.

His research includes topics in machine learning, with emphasis on optimization, deep learning theory, statistical learning. His recent work includes methods for efficient and adaptive optimization, studying the interaction between optimization and the dynamics of large-scale learning systems and the dynamics of games.
Current Students

PhD - Université de Montréal
Principal supervisor :
Professional Master's - Université de Montréal
PhD - Université de Montréal
Collaborating researcher - Université de Montréal
Principal supervisor :

Publications

DisTaC: Conditioning Task Vectors via Distillation for Robust Model Merging
Kotaro Yoshida
Yuji Naraki
Takafumi Horie
Ryotaro Shimizu
Model merging has emerged as an efficient and flexible paradigm for multi-task learning, with numerous methods being proposed in recent year… (see more)s. However, these state-of-the-art techniques are typically evaluated on benchmark suites that are highly favorable to model merging, and their robustness in more realistic settings remains largely unexplored. In this work, we first investigate the vulnerabilities of model-merging methods and pinpoint the source-model characteristics that critically underlie them. Specifically, we identify two factors that are particularly harmful to the merging process: (1) disparities in task vector norms, and (2) the low confidence of the source models. To address this issue, we propose **DisTaC** (**Dis**tillation for **Ta**sk vector **C**onditioning), a novel method that pre-conditions these problematic task vectors before the merge. DisTaC leverages knowledge distillation to adjust a task vector's norm and increase source-model confidence while preserving its essential task-specific knowledge. Our extensive experiments demonstrate that by pre-conditioning task vectors with DisTaC, state-of-the-art merging techniques can successfully integrate models that exhibit these harmful traits, where they would otherwise fail, and achieve significant performance gains.
Understanding Adam Requires Better Rotation Dependent Assumptions
Despite its widespread adoption, Adam's advantage over Stochastic Gradient Descent (SGD) lacks a comprehensive theoretical explanation. This… (see more) paper investigates Adam's sensitivity to rotations of the parameter space. We observe that Adam's performance in training transformers degrades under random rotations of the parameter space, indicating a crucial sensitivity to the choice of basis in practice. This reveals that conventional rotation-invariant assumptions are insufficient to capture Adam's advantages theoretically. To better understand the rotation-dependent properties that benefit Adam, we also identify structured rotations that preserve or even enhance its empirical performance. We then examine the rotation-dependent assumptions in the literature and find that they fall short in explaining Adam's behaviour across various rotation types. In contrast, we verify the orthogonality of the update as a promising indicator of Adam's basis sensitivity, suggesting it may be the key quantity for developing rotation-dependent theoretical frameworks that better explain its empirical success.
A Derandomization Framework for Structure Discovery: Applications in Neural Networks and Beyond
Nikos Tsikouras
Yorgos Pantis
Christos Tzamos
Compositional Risk Minimization
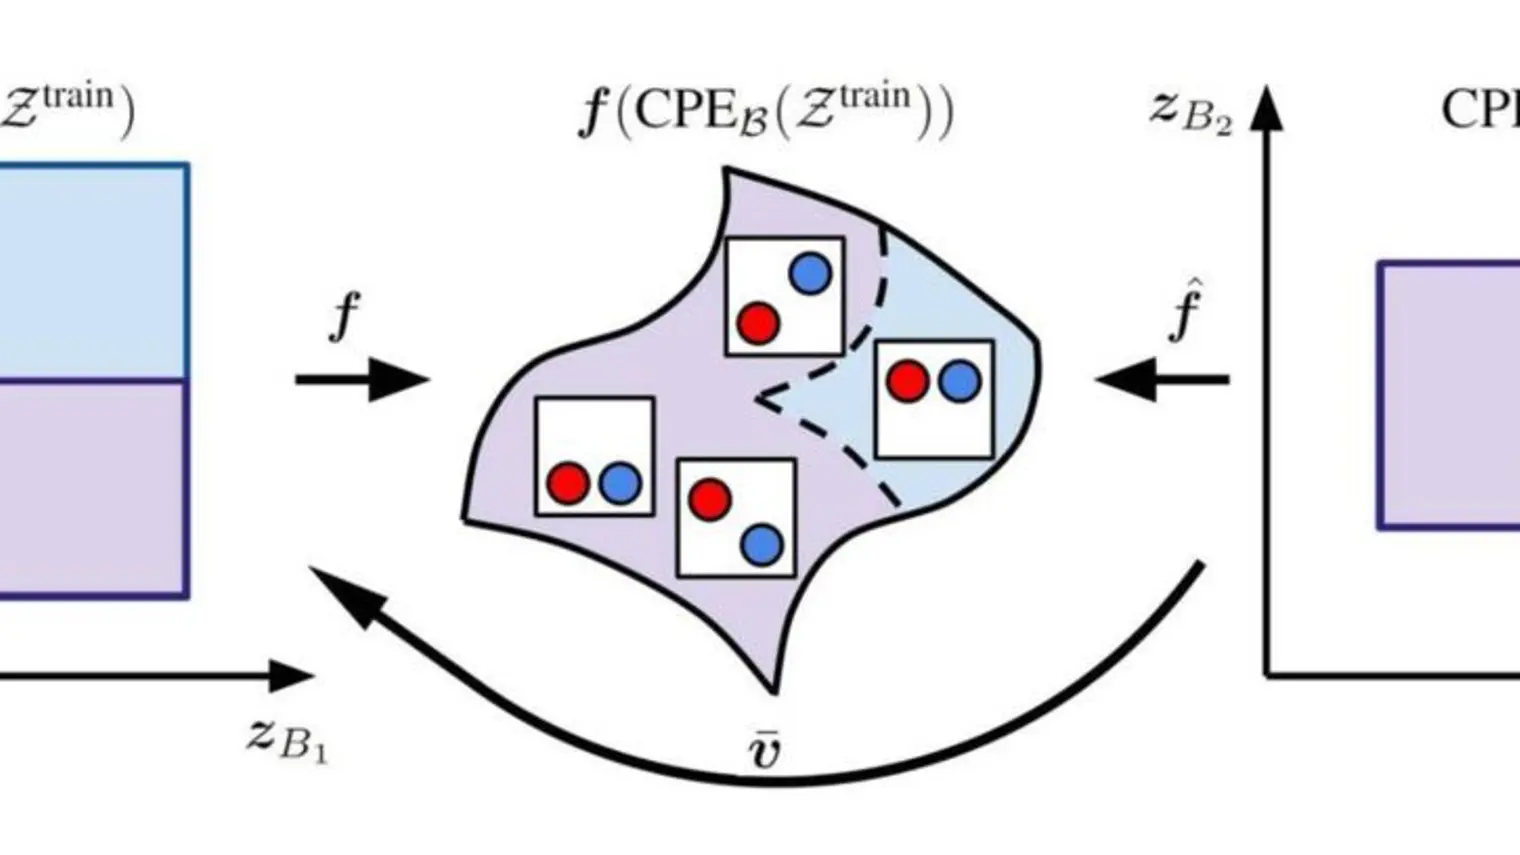
Compositional generalization is a crucial step towards developing data-efficient intelligent machines that generalize in human-like ways. In… (see more) this work, we tackle a challenging form of distribution shift, termed compositional shift, where some attribute combinations are completely absent at training but present in the test distribution. This shift tests the model's ability to generalize compositionally to novel attribute combinations in discriminative tasks. We model the data with flexible additive energy distributions, where each energy term represents an attribute, and derive a simple alternative to empirical risk minimization termed compositional risk minimization (CRM). We first train an additive energy classifier to predict the multiple attributes and then adjust this classifier to tackle compositional shifts. We provide an extensive theoretical analysis of CRM, where we show that our proposal extrapolates to special affine hulls of seen attribute combinations. Empirical evaluations on benchmark datasets confirms the improved robustness of CRM compared to other methods from the literature designed to tackle various forms of subpopulation shifts.
Pseudo-Asynchronous Local SGD: Robust and Efficient Data-Parallel Training
Xinzhi Zhang
Man-Chung Yue
Russell J. Hewett
Philipp Andre Witte
Yin Tat Lee
An Empirical Study of Pre-trained Model Selection for Out-of-Distribution Generalization and Calibration
Ryuichiro Hataya
Kotaro Yoshida
Solving Hidden Monotone Variational Inequalities with Surrogate Losses
Deep learning has proven to be effective in a wide variety of loss minimization problems. However, many applications of interest, like minim… (see more)izing projected Bellman error and min-max optimization, cannot be modelled as minimizing a scalar loss function but instead correspond to solving a variational inequality (VI) problem. This difference in setting has caused many practical challenges as naive gradient-based approaches from supervised learning tend to diverge and cycle in the VI case. In this work, we propose a principled surrogate-based approach compatible with deep learning to solve VIs. We show that our surrogate-based approach has three main benefits: (1) under assumptions that are realistic in practice (when hidden monotone structure is present, interpolation, and sufficient optimization of the surrogates), it guarantees convergence, (2) it provides a unifying perspective of existing methods, and (3) is amenable to existing deep learning optimizers like ADAM. Experimentally, we demonstrate our surrogate-based approach is effective in min-max optimization and minimizing projected Bellman error. Furthermore, in the deep reinforcement learning case, we propose a novel variant of TD(0) which is more compute and sample efficient.
Learning to Defer for Causal Discovery with Imperfect Experts
Integrating expert knowledge, e.g. from large language models, into causal discovery algorithms can be challenging when the knowledge is not… (see more) guaranteed to be correct. Expert recommendations may contradict data-driven results, and their reliability can vary significantly depending on the domain or specific query. Existing methods based on soft constraints or inconsistencies in predicted causal relationships fail to account for these variations in expertise. To remedy this, we propose L2D-CD, a method for gauging the correctness of expert recommendations and optimally combining them with data-driven causal discovery results. By adapting learning-to-defer (L2D) algorithms for pairwise causal discovery (CD), we learn a deferral function that selects whether to rely on classical causal discovery methods using numerical data or expert recommendations based on textual meta-data. We evaluate L2D-CD on the canonical Tübingen pairs dataset and demonstrate its superior performance compared to both the causal discovery method and the expert used in isolation. Moreover, our approach identifies domains where the expert's performance is strong or weak. Finally, we outline a strategy for generalizing this approach to causal discovery on graphs with more than two variables, paving the way for further research in this area.
Expecting The Unexpected: Towards Broad Out-Of-Distribution Detection
Pierre-Andre Noel
Joao Monteiro
Improving the reliability of deployed machine learning systems often involves developing methods to detect out-of-distribution (OOD) inputs.… (see more) However, existing research often narrowly focuses on samples from classes that are absent from the training set, neglecting other types of plausible distribution shifts. This limitation reduces the applicability of these methods in real-world scenarios, where systems encounter a wide variety of anomalous inputs. In this study, we categorize five distinct types of distribution shifts and critically evaluate the performance of recent OOD detection methods on each of them. We publicly release our benchmark under the name BROAD (Benchmarking Resilience Over Anomaly Diversity). Our findings reveal that while these methods excel in detecting unknown classes, their performance is inconsistent when encountering other types of distribution shifts. In other words, they only reliably detect unexpected inputs that they have been specifically designed to expect. As a first step toward broad OOD detection, we learn a generative model of existing detection scores with a Gaussian mixture. By doing so, we present an ensemble approach that offers a more consistent and comprehensive solution for broad OOD detection, demonstrating superior performance compared to existing methods. Our code to download BROAD and reproduce our experiments is publicly available.
Feature learning as alignment: a structural property of gradient descent in non-linear neural networks
Daniel Beaglehole
Atish Agarwala
Understanding the mechanisms through which neural networks extract statistics from input-label pairs through feature learning is one of the … (see more)most important unsolved problems in supervised learning. Prior works demonstrated that the gram matrices of the weights (the neural feature matrices, NFM) and the average gradient outer products (AGOP) become correlated during training, in a statement known as the neural feature ansatz (NFA). Through the NFA, the authors introduce mapping with the AGOP as a general mechanism for neural feature learning. However, these works do not provide a theoretical explanation for this correlation or its origins. In this work, we further clarify the nature of this correlation, and explain its emergence. We show that this correlation is equivalent to alignment between the left singular structure of the weight matrices and the newly defined pre-activation tangent features at each layer. We further establish that the alignment is driven by the interaction of weight changes induced by SGD with the pre-activation features, and analyze the resulting dynamics analytically at early times in terms of simple statistics of the inputs and labels. We prove the derivative alignment occurs with high probability in specific high dimensional settings. Finally, motivated by the observation that the NFA is driven by this centered correlation, we introduce a simple optimization rule that dramatically increases the NFA correlations at any given layer and improves the quality of features learned.
Generating Tabular Data Using Heterogeneous Sequential Feature Forest Flow Matching
No Wrong Turns: The Simple Geometry Of Neural Networks Optimization Paths
Understanding the optimization dynamics of neural networks is necessary for closing the gap between theory and practice. Stochastic first-or… (see more)der optimization algorithms are known to efficiently locate favorable minima in deep neural networks. This efficiency, however, contrasts with the non-convex and seemingly complex structure of neural loss landscapes. In this study, we delve into the fundamental geometric properties of sampled gradients along optimization paths. We focus on two key quantities, which appear in the restricted secant inequality and error bound. Both hold high significance for first-order optimization. Our analysis reveals that these quantities exhibit predictable, consistent behavior throughout training, despite the stochasticity induced by sampling minibatches. Our findings suggest that not only do optimization trajectories never encounter significant obstacles, but they also maintain stable dynamics during the majority of training. These observed properties are sufficiently expressive to theoretically guarantee linear convergence and prescribe learning rate schedules mirroring empirical practices. We conduct our experiments on image classification, semantic segmentation and language modeling across different batch sizes, network architectures, datasets, optimizers, and initialization seeds. We discuss the impact of each factor. Our work provides novel insights into the properties of neural network loss functions, and opens the door to theoretical frameworks more relevant to prevalent practice.