Portrait of Mark Coates

Mark Coates

Associate Academic Member
Associate Professor, McGill University
Research Topics
Dynamical Systems
Graph Neural Networks
Learning on Graphs
Recommender Systems
Representation Learning

Biography

Mark Coates is a professor in the Department of Electrical and Computer Engineering at McGill University, which he joined in 2002. He received his Bachelor of Engineering degree in computer systems engineering from the University of Adelaide, Australia, in 1995 and his PhD degree in information engineering from the University of Cambridge, U.K., in 1999. Coates was formerly a research associate and lecturer at Rice University, Texas (1999–2001) and a senior scientist at Winton Capital Management, Oxford, U.K. (2012–2013).

He has assumed multiple editorial roles, including senior area editor of IEEE Signal Processing Letters, associate editor of IEEE Transactions on Signal Processing, and associate editor of IEEE Transactions on Signal and Information Processing over Networks. His research interests include machine learning and statistical signal processing, Bayesian and Monte Carlo inference, and learning on graphs and networks. His most influential and widely cited contributions have been on the topics of network tomography and distributed particle filtering.
Current Students

Publications

SKOLR: Structured Koopman Operator Linear RNN for Time-Series Forecasting
Koopman operator theory provides a framework for nonlinear dynamical system analysis and time-series forecasting by mapping dynamics to a sp… (see more)ace of real-valued measurement functions, enabling a linear operator representation. Despite the advantage of linearity, the operator is generally infinite-dimensional. Therefore, the objective is to learn measurement functions that yield a tractable finite-dimensional Koopman operator approximation. In this work, we establish a connection between Koopman operator approximation and linear Recurrent Neural Networks (RNNs), which have recently demonstrated remarkable success in sequence modeling. We show that by considering an extended state consisting of lagged observations, we can establish an equivalence between a structured Koopman operator and linear RNN updates. Building on this connection, we present SKOLR, which integrates a learnable spectral decomposition of the input signal with a multilayer perceptron (MLP) as the measurement functions and implements a structured Koopman operator via a highly parallel linear RNN stack. Numerical experiments on various forecasting benchmarks and dynamical systems show that this streamlined, Koopman-theory-based design delivers exceptional performance.
Sparse Decomposition of Graph Neural Networks
Yaochen Hu
Mai Zeng
Ge Zhang
Pavel Rumiantsev
Yingxue Zhang
Is the acquisition worth the cost? Surrogate losses for Consistent Two-stage Classifiers
E-CARE: An Efficient LLM-based Commonsense-Augmented Framework for E-Commerce
Ge Zhang
Rohan Deepak Ajwani
Yaochen Hu
Tony Zheng
Wei Guo
Yingxue Zhang
Finding relevant products given a user query is pivotal to an e-commerce platform, as it can drive shopping behavior and generate revenue. T… (see more)he challenge lies in accurately predicting the correlation between queries and products. Recently, mining commonsense knowledge between queries and products using Large Language Models (LLMs) has shown promising results in boosting recommendation performance. However, such methods incur high costs due to intensive real-time LLM decoding during inference, as well as human annotation and potential Supervised Fine-Tuning (SFT) during training. To boost efficiency while leveraging LLMs' commonsense reasoning for various e-commerce tasks, we propose the Efficient Commonsense-Augmented Recommendation Enhancer (E-CARE), which requires neither SFT nor human annotation. The recommendation models augmented with E-CARE can access commonsense reasoning by leveraging a reasoning factor graph that encodes most of the reasoning schema from powerful LLMs, without requiring real-time LLM decoding. The experiments on 2 downstream tasks show improvements of up to 12.1% in precision@5.
It Takes Two: Your GRPO Is Secretly DPO
Yihong Wu
Lei Ding
Muzhi Li
Xinyu Wang
Kejia Chen
Chenyang Huang
Zhanguang Zhang
Derek Li
Yingxue Zhang
Jian-Yun Nie
GRPO has emerged as a prominent reinforcement learning algorithm for post-training LLMs. Unlike critic-based methods, GRPO computes advantag… (see more)es by estimating the \emph{value baselines} from group-level statistics, eliminating the need for a critic network. Consequently, the prevailing view emphasizes the necessity of large group sizes, which are assumed to yield more accurate statistical estimates. In this paper, we propose a different view that the efficacy of GRPO stems from its implicit contrastive objective in the optimization, which helps reduce variance via the control variate method. This makes GRPO structurally related to preference learning methods such as DPO. This perspective motivates 2-GRPO, a minimal group-size variant that constructs contrastive signals with only two rollouts. We provide a rigorous theoretical analysis of 2-GRPO and empirically validate its effectiveness: 2-GRPO retains
Dynamic layer selection in decoder-only transformers
Joud Chataoui
Florence Regol
Wassim Jabbour
Boris N. Oreshkin
The vast size of Large Language Models (LLMs) has prompted a search to optimize inference. One effective approach is dynamic inference, whic… (see more)h adapts the architecture to the sample-at-hand to reduce the overall computational cost. We empirically examine two common dynamic inference methods for natural language generation (NLG): layer skipping and early exiting. We find that a pre-trained decoder-only model is significantly more robust to layer removal via layer skipping, as opposed to early exit. We demonstrate the difficulty of using hidden state information to adapt computation on a per-token basis for layer skipping. Finally, we show that dynamic computation allocation on a per-sequence basis holds promise for significant efficiency gains by constructing an oracle controller. Remarkably, we find that there exists an allocation which achieves equal performance to the full model using only 23.3% of its layers on average.
Bidirectional Learning for Offline Model-based Biological Sequence Design
Yingxue Zhang
Xue Liu
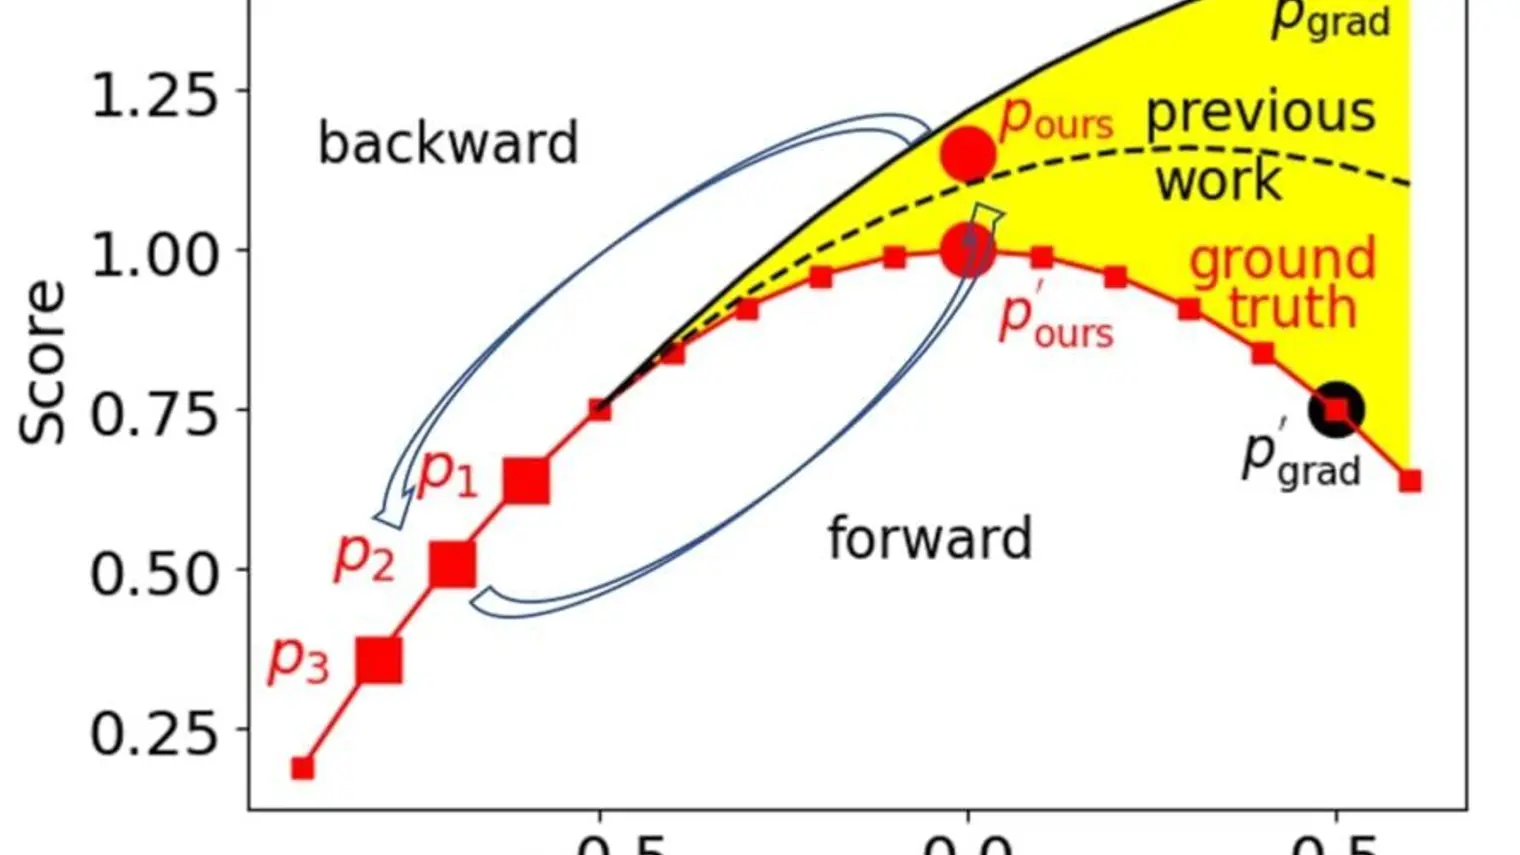
Offline model-based optimization aims to maximize a black-box objective function with a static dataset of designs and their scores. In this … (see more)paper, we focus on biological sequence design to maximize some sequence score. A recent approach employs bidirectional learning, combining a forward mapping for exploitation and a backward mapping for constraint, and it relies on the neural tangent kernel (NTK) of an infinitely wide network to build a proxy model. Though effective, the NTK cannot learn features because of its parametrization, and its use prevents the incorporation of powerful pre-trained Language Models (LMs) that can capture the rich biophysical information in millions of biological sequences. We adopt an alternative proxy model, adding a linear head to a pre-trained LM, and propose a linearization scheme. This yields a closed-form loss and also takes into account the biophysical information in the pre-trained LM. In addition, the forward mapping and the backward mapping play different roles and thus deserve different weights during sequence optimization. To achieve this, we train an auxiliary model and leverage its weak supervision signal via a bi-level optimization framework to effectively learn how to balance the two mappings. Further, by extending the framework, we develop the first learning rate adaptation module \textit{Adaptive}-