


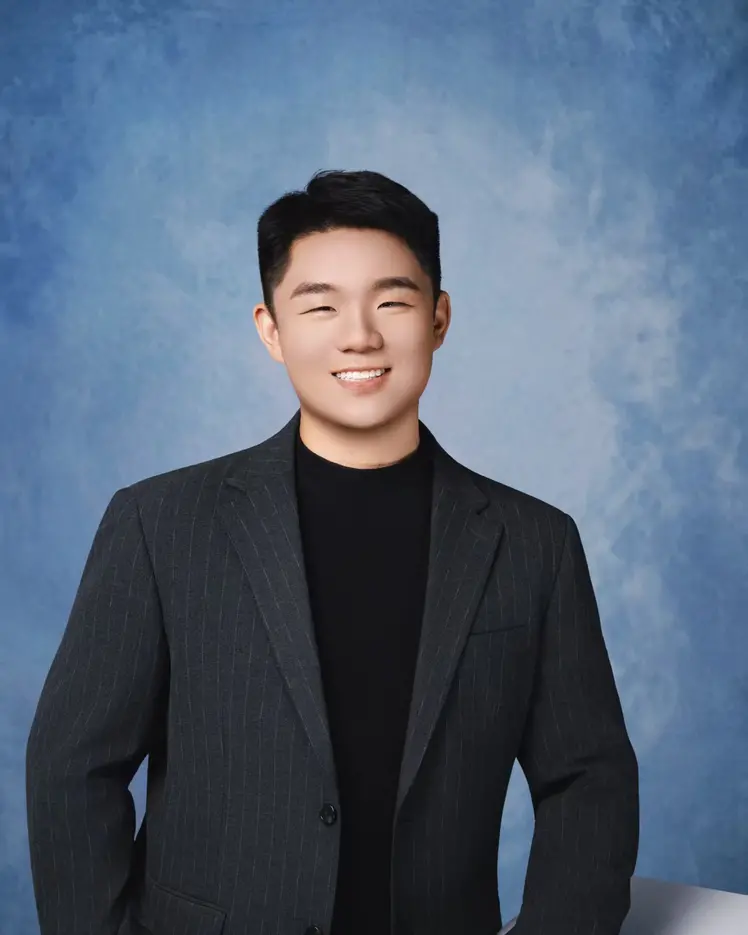
Portrait of Pingsheng Li

Pingsheng Li

Lab Representative
PhD
Supervisor
Co-supervisor
Research Topics
Computational Neuroscience
Foundation Models
Multimodal Learning
Representation Learning

Biography

I am a 1st-year Ph.D. student at McGill University, co-supervised by Prof. Blake Richards and Prof. Guillaume Lajoie. My research focuses on building multimodal, scalable foundation models for complex neural data, with the aim of developing better brain decoders and intelligent neural interfaces (broadly within NeuroAI). Previously, I completed my Master’s in the Neuro-X program at EPFL in Switzerland. Now at Mila, I aim to facilitate the synergy between academia and industry to promote a better future for human-AI co-evolution.

Publications

Exponentiated gradient learning yields brain-like synaptic distributions
Jonathan H. Cornford
Kaiwen Sheng
Brendan A. Bicknell
Beverley A. Clark
Blake A. Richards
Artificial neural networks trained with gradient descent (GD) are widely used to model brain learning, but GD allows synapses to switch betw… (see more)een excitatory and inhibitory and produces weight distributions unlike those observed experimentally. We show that an alternative rule, exponentiated gradient (EG), avoids these problems because its multiplicative, exponential weight updates mathematically prohibit synapses from changing sign and preferentially scale already-large weights, naturally generating log-normal distributions. This mechanism also concentrates task-relevant computation onto a smaller subset of strong connections, which we show makes EG-trained recurrent neural networks more robust to synaptic pruning and better able to learn from sparsely relevant inputs than GD-trained networks, while matching GD's performance on standard cognitive tasks. These findings tie a normative optimization principle directly to observed features of synaptic organization in the brain.
Learning better with Dale's Law: A Spectral Perspective
Most recurrent neural networks (RNNs) do not include a fundamental constraint of real neural circuits: Dale’s Law, which implies that neur… (see more)ons must be excitatory (E) or inhibitory (I). Dale’s Law is generally absent from RNNs because simply partitioning a standard network’s units into E and I populations impairs learning. However, here we extend a recent feedforward bio-inspired EI network architecture, named Dale’s ANNs, to recurrent networks, and demonstrate that good performance is possible while respecting Dale’s Law. This begs the question: What makes some forms of EI network learn poorly and others learn well? And, why does the simple approach of incorporating Dale’s Law impair learning? Historically the answer was thought to be the sign constraints on EI network parameters, and this was a motivation behind Dale’s ANNs. However, here we show the spectral properties of the recurrent weight matrix at initialisation are more impactful on network performance than sign constraints. We find that simple EI partitioning results in a singular value distribution that is multimodal and dispersed, whereas standard RNNs have an unimodal, more clustered singular value distribution, as do recurrent Dale’s ANNs. We also show that the spectral properties and performance of partitioned EI networks are worse for small networks with fewer I units, and we present normalised SVD entropy as a measure of spectrum pathology that correlates with performance. Overall, this work sheds light on a long-standing mystery in neuroscience-inspired AI and computational neuroscience, paving the way for greater alignment between neural networks and biology.